---
title: "Attention and Memory"
description: "Compare execution, retained history, selected reads and recurrent state without mixing their costs."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Attention and Memory
import FocusCanvas from '../../../../components/FocusCanvas.astro';
import ArchitectureAtlas from '../../../../components/architectures/ArchitectureAtlas.astro';
import SourceFigure from '../../../../components/architectures/SourceFigure.astro';
“Efficient attention” can mean faster execution, a smaller record of each
token, fewer positions read, or a different memory altogether. These choices
solve different problems. Start with **what is stored** and **what a query can read**,
then ask how the operation runs.[^flash][^gqa][^mla][^linear]
## Four memory contracts
**Four ways to retain or read the past**
**Explicit history**: Store keys and values by position. GQA reduces the number of KV heads, not the number of retained positions.
**Compressed history**: MLA retains a compact content latent plus a positional key for each token. The history still grows.
**Selected reads**: An indexer selects tokens or blocks before the main attention operation. Unselected history may still occupy storage.
**Recurrent state**: Update a fixed-shape state instead of appending one record per token. Earlier details must survive compression.
FlashAttention is a separate execution choice: it avoids a full score matrix in HBM without removing dense pairwise arithmetic.
**Figure 1.** Retaining history and reading history are different decisions. Original synthesis; cells and selected rows are illustrative.[^gqa][^mla][^msa][^linear]
The four panels in [Figure 1](#figure-1) are not interchangeable replacements. A model can combine
compressed history, sparse reads, and recurrent layers. An exact attention
kernel can improve the remaining softmax operation without changing those
architectural choices.
## Execute the same operator more efficiently
FlashAttention brings tiles of queries, keys, and values into fast on chip
memory, updates softmax statistics incrementally, and avoids materializing
the full score matrix in high bandwidth memory. Backward recomputation replaces
storage of that matrix.[^flash]
It preserves dense softmax attention, subject to numerical differences.
The pairwise arithmetic remains quadratic in sequence length. Kernel speed,
attention workspace, persistent KV cache, and total model memory are distinct
measurements. A kernel improvement is not a proof that the model retains less history.
## Share heads or compress content
**GQA** shares a key head and value head within each query group. MQA uses
one KV group; ordinary MHA uses one per query head. None removes positions
from the retained prefix.[^gqa]
For equal key and value head widths, a local tensor count gives:
$$
M_{\mathrm{KV}}=2LBT H_{\mathrm{KV}}d_h s
\tag{1}
$$
Here L is layer count, B batch size, T retained positions, HKV
KV heads, dh elements per head, and s bytes per element. This counts
keys and values only, excluding runtime overhead. Reducing KV heads by four
reduces this storage by four, not necessarily latency by four.
**MLA** instead jointly compresses content keys and values into a latent for
each token. DeepSeek-V2 also retains a separate positional key. Suitable
projection absorption allows an optimized implementation to read the latent
without reconstructing every old head representation.[^mla]
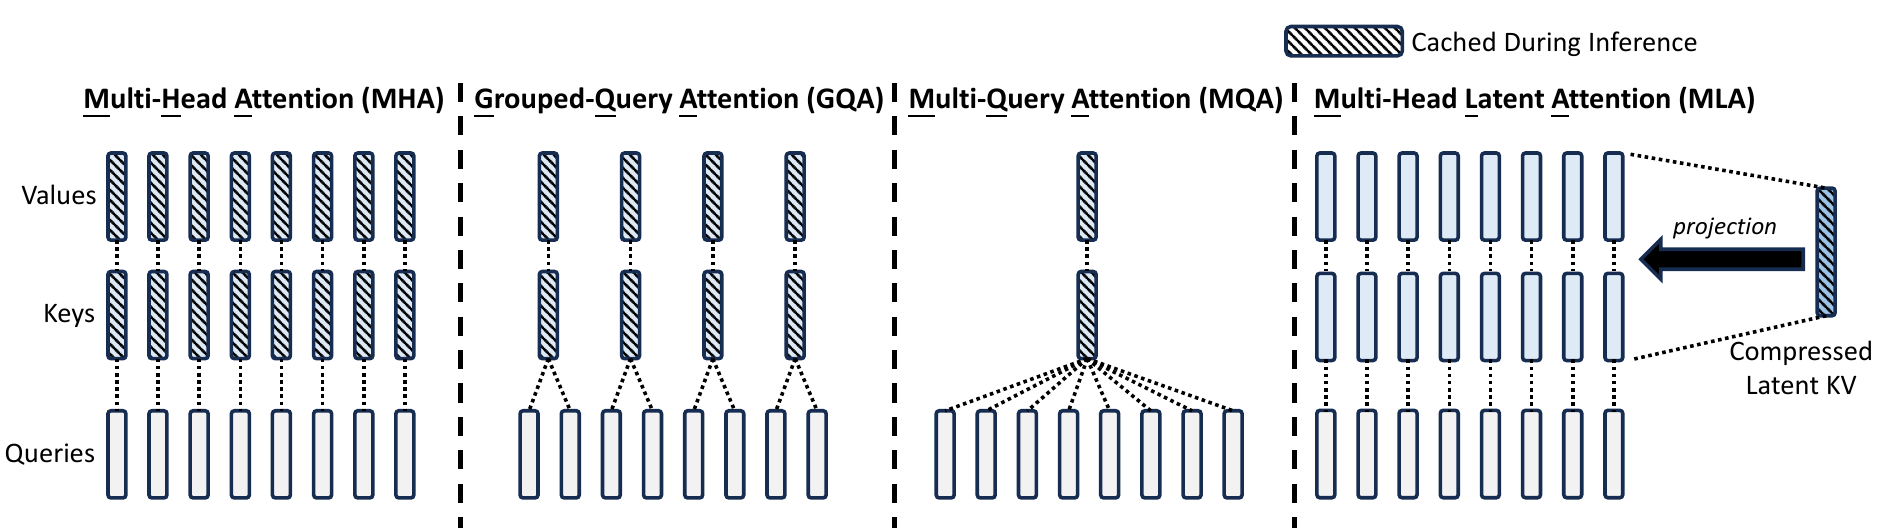
**Figure 2.** Sharing heads versus compressing content. Reproduced from DeepSeek-AI, V2 documentation Figure 3; unchanged figure crop, [MIT notice](/figures/model-studies/deepseek-v2/NOTICE.md).[^mla]
**Image description:** MHA stores keys and values per head, GQA and MQA share KV heads, and MLA jointly compresses content into a latent.
[Figure 2](#figure-2) is a simplified content view. MLA's separate positional
key belongs in the complete cache count. Its history still grows with T.
The [V2 study](/architectures/models/deepseek-v2/#how-mla-compresses-history)
also documents why a reference implementation and an optimized latent cache
need not store the same tensors.
## Restrict which history participates
A sliding window changes connectivity: each layer reads a bounded recent
region. Older information can travel through intermediate representations
across depth, but an arbitrarily distant token is not directly visible to
every layer. [Mistral 7B](/architectures/models/mistral-7b/) supplies a concrete
example.[^mistral]
Learned sparse attention adds a different choice. A cheaper indexer selects
history, then the main attention reads selected tokens or blocks. GLM-5 uses
DSA; MiniMax Sparse Attention selects blocks separately for GQA groups.[^glm][^msa]
Selection can reduce expensive reads while leaving growing storage and
indexing work. “Exact attention on selected entries” is not the same operator
as dense attention over every entry.
For compressed and selected history together, continue with
[DeepSeek-V4](/architectures/models/deepseek-v4/) or
[Qwen3.8-Next](/architectures/models/qwen3-8-flash-next/).
## Replace an append-only history with state
The causal linear Transformer writes key and value associations to a matrix.
Using column vectors, a positive feature map φ, and zero initial states:[^linear]
$$
\begin{aligned}
S_t &= S_{t-1}+\phi(k_t)v_t^\top\\
z_t &= z_{t-1}+\phi(k_t)\\
y_t^\top &= \frac{\phi(q_t)^\top S_t}{\phi(q_t)^\top z_t}
\end{aligned}
\tag{2}
$$
The denominator must be nonzero. With feature width dφ and value
width dv, the state contains dφdv + dφ
elements, independent of T. This is a different matching operator, not exact
softmax attention in another order.
[Mamba](/architectures/models/mamba/) uses a selective state space model:
input dependent dynamics control what survives and how it is read.[^mamba]
[Kimi Linear](/architectures/models/kimi-linear/) adds corrective writes and
channel specific forgetting. These are distinct update rules, not synonyms
for the additive recurrence above.[^kimi]
## Hybrids preserve more than one kind of history
**A hybrid has more than one memory lifetime**
**Kimi Linear · 3 KDA : 1 MLA**: KDA layers retain fixed-shape recurrent state; periodic global MLA layers still retain growing token history.
**Gemma 3 · 5 local : 1 global**: Local layers keep a bounded attention window; periodic global layers retain full history. Local attention is not recurrence.
R: recurrent KDA. L: local window. G: global MLA or softmax, as named above. These layer patterns are not interchangeable definitions of hybrid attention. FFNs and residuals are omitted.
**Figure 3.** Fixed or bounded local state can coexist with growing global history. Original comparison of the named reports' layer patterns.[^kimi][^gemma]
The global path in [Figure 3](#figure-3) still grows with context. Do not
assign a recurrent layer's fixed state to the entire hybrid model.
[MiniMax 01](/architectures/models/minimax-01/) provides another instructive
hybrid, with seven lightning layers before each softmax layer.[^minimax]
## Compare the right budgets
Report quality, prefill latency, decoding latency, persistent state, peak
workspace, total weights, and throughput at a stated concurrency. Control
hardware, precision, lengths, and backend. Inspect retrieval under distance
and distractors, not only easy recent facts.
This is a proposed measurement framework, not a benchmark result. Selected
mechanisms rechecked October 10, 2026. For the original attention shapes,
see [Foundations](/architectures/foundations/#attention-and-masking).
[^flash]: Tri Dao et al. [FlashAttention](https://arxiv.org/html/2205.14135v2), 2022, sections 2 and 3. Dense exact attention is separate from the block sparse extension.
[^gqa]: Joshua Ainslie et al. [GQA](https://arxiv.org/html/2305.13245v3), 2023, section 2. Equation (1) is a local KV tensor count.
[^mla]: DeepSeek-AI. [DeepSeek-V2](https://arxiv.org/html/2405.04434v1), 2024, sections 2.1.2 to 2.1.4 and Appendix B. Source Figure 3 is reproduced from the matching repository documentation edition; the complete MLA includes the positional key.
[^linear]: Angelos Katharopoulos et al. [Transformers are RNNs](https://arxiv.org/html/2006.16236v3), 2020, section 3. Equation (2) restates the normalized causal recurrence with local notation.
[^mistral]: Albert Q. Jiang et al. [Mistral 7B](https://arxiv.org/html/2310.06825v1), 2023, section 2.
[^glm]: GLM-5 Team. [GLM-5](https://arxiv.org/html/2602.15763v1), 2026, sections 2.1.1 to 2.1.2.
[^msa]: MiniMax. [MiniMax Sparse Attention](https://arxiv.org/html/2606.13392v2), 2026, sections 2.2 and 3: group specific block selection and index cost.
[^mamba]: Albert Gu and Tri Dao. [Mamba](https://arxiv.org/html/2312.00752v2), 2024 revision, section 3.
[^kimi]: Kimi Team. [Kimi Linear](https://arxiv.org/html/2510.26692v1), 2025, sections 3, 4 and 6: KDA and the 3:1 hybrid.
[^gemma]: Gemma Team. [Gemma 3 Technical Report](https://arxiv.org/html/2503.19786v1), 2025, local/global attention design and memory ablations.
[^minimax]: MiniMax. [MiniMax-01](https://arxiv.org/html/2501.08313v1), 2025, section 2.2: lightning and hybrid attention.
Source: https://latentlit.com/architectures/evolution/attention-and-memory/index.mdx