---
title: "Edge AI"
description: "Build useful AI within device budgets, from efficient models and inference to multimodal systems, agents and product design."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Edge AI
import FocusCanvas from '../../../components/FocusCanvas.astro';
import ModelFlow from '../../../components/architectures/ModelFlow.astro';
import SourceFigure from '../../../components/architectures/SourceFigure.astro';
import ComparisonTable from '../../../components/ComparisonTable.astro';
Edge AI brings intelligence close to where it is used: a phone, a laptop,
a camera, an embedded system or a small sensor. The challenge is not simply
to make a large model smaller. It is to deliver a useful capability within
the device's memory, compute, responsiveness and energy limits.
[Figure 1](#figure-1) maps the collection: capable models, efficient execution
and dependable systems, all shaped by shared device budgets.
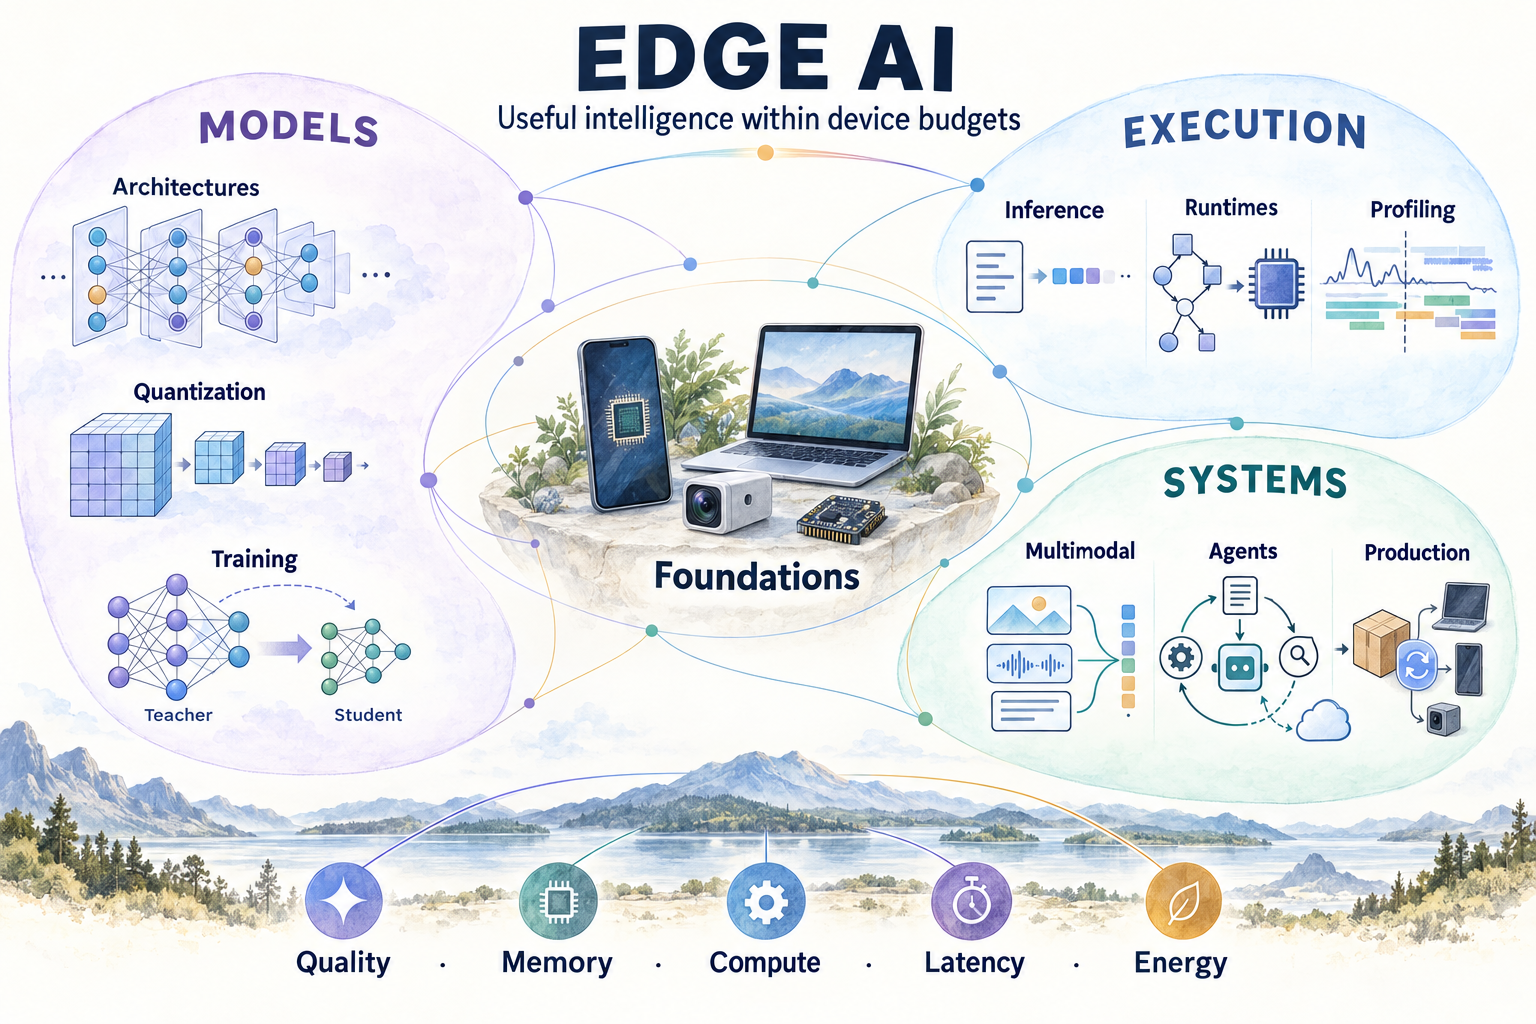
**Figure 1.** The Edge AI learning landscape. AI generated illustration informed by device deployment and co-design.[^ort][^mcunet]
**Image description:** Models: architectures, quantization and training. Execution: inference, runtimes and profiling. Systems: multimodal inputs, agents and production. Foundations connects phones, laptops, cameras and microcontrollers with quality, memory, compute, latency and energy budgets.
This is broader than a smaller language model. It includes speech, streaming
perception and specialist models. Local execution is a design option, not a
rule that every task must stay on the device.
The three territories are connected decisions, not fixed pipeline stages.
An architecture or training change can alter execution cost; the product's
deadline or sensory inputs can change which model is useful. The image's
shrinking blocks represent cheaper numerical storage, not removed layers;
its traces are schematic, not measured performance.
## Explore the topics
Start with foundations, then follow the bottleneck or question that matters
to your work. Chapters and focused companions explain mechanisms, tradeoffs and the evidence
needed to choose between them.
**Topics and focused companions**
| Topic | The question it helps answer |
| --- | --- |
| [Foundations and bottlenecks](/edge-ai/foundations/) | What really limits the workload: capacity, movement, arithmetic or sustained operation? |
| [On device computing](/edge-ai/on-device-computing/) | How do CPU, GPU, NPU, memory and power differ from cloud computing, and which platforms serve each device? |
| [Efficient model architectures](/edge-ai/efficient-models/) | Which design choices reduce stored weights, cache or work without losing the needed capability? |
| [Quantization and compression](/edge-ai/quantization-compression/) | What can be represented more cheaply, and will the backend exploit it? |
| [Training capable small models](/edge-ai/training-small-models/) | How can data, distillation and task training make a small model useful? |
| [Efficient inference](/edge-ai/efficient-inference/) | How do prefill, decoding, caching and scheduling change the execution cost? |
| [Runtimes, compilers and kernels](/edge-ai/runtimes-compilers/) | How does a checkpoint become a supported, efficient device workload? |
| [Multimodal and continuous workloads](/edge-ai/multimodal/) | How do images, audio and video change context, evidence and resource budgets? |
| [Edge agents and hybrid systems](/edge-ai/agents-hybrid-systems/) | What stays local, what goes remote, and how are actions controlled? |
| [Local and cloud model collaboration](/edge-ai/local-cloud-collaboration/) | How can local specialists and stronger remote models cooperate, and when does the whole system improve? |
| [Evaluation and profiling](/edge-ai/evaluation-profiling/) | How do we measure useful quality, latency, memory and energy on the actual path? |
| [Production and product design](/edge-ai/production-product-design/) | How does the capability survive downloads, updates, failures and diverse devices? |
## Choose a reading path
- **Fit the capability** — Understand the memory budget, choose an architecture, then decide whether
compression or better training addresses the limiting factor.
[Foundations](/edge-ai/foundations/) → [Models](/edge-ai/efficient-models/) → [Compression](/edge-ai/quantization-compression/) → [Training](/edge-ai/training-small-models/)
- **Make it run well** — Understand the device hardware, separate inference phases, inspect the
backend contract, and measure
the complete workload rather than a favorable kernel alone.
[Hardware](/edge-ai/on-device-computing/) → [Inference](/edge-ai/efficient-inference/) → [Runtimes](/edge-ai/runtimes-compilers/) → [Evaluation](/edge-ai/evaluation-profiling/)
- **Build the useful system** — Add real sensory inputs, bounded actions and local or remote routing.
Then consider the lifecycle that makes the feature dependable.
[Multimodal](/edge-ai/multimodal/) → [Agents](/edge-ai/agents-hybrid-systems/) → [Production](/edge-ai/production-product-design/)
The [Transformer foundations](/architectures/foundations/) supply prerequisites
for the language and vision language chapters.
[Hardware 101](/hardware/) introduces circuits, sensors, memory, firmware and
power for readers who want to build physical AI devices.
[On device computing](/edge-ai/on-device-computing/) adds a hardware companion
to the landscape, with current chips and device execution paths.
[Model Deep Dives](/architectures/models/) examine individual
reports, while [Agents](/agents/) and [Document AI](/document-ai/) explore
systems that may benefit from local execution.
## From the task to the device
A model that fits on disk can still fail in memory. An accelerated graph
can lose time crossing processor boundaries. Mobile deployment guidance
makes both constraints explicit; MCUNet demonstrates designing a model and
runtime together.[^ort][^mcunet]
[Figure 2](#figure-2) turns the landscape into a practical feedback loop:
**task needs, model choices, execution and device evidence**.
**Start with a useful task. Close the loop on the device.**
**Design and test**
1. **Task contract**: Quality, deadline, privacy and allowed actions
2. **Model and data**: Capacity, architecture, training and compression
3. **Execution path**: Runtime, kernels, memory and scheduling
4. **Device evidence**: Completed tasks under realistic conditions
Return the measured failure to the right decision: change the model, execution path or product scope.
This is an editorial decision loop, not a literal neural-network graph.
**Figure 2.** Capability, execution and product design form one feedback loop. Independent synthesis informed by mobile deployment guidance and MCUNet.[^ort][^mcunet]
## How to read the evidence
This is a learning map, not a device leaderboard. Chapters distinguish
reported findings, mechanism explanations and our own illustrative
calculations. The original collection was reviewed on October 12, 2026;
focused companions give their own review dates. Mutable runtime documentation
should be checked again for the versions you deploy.
No device benchmark was run for this collection.
The practical goal is to find a **feasible design that meets the task**.
When a reported gain matters, carry its model, precision, input length,
backend and measurement conditions with it.
[^ort]: ONNX Runtime, [Deploy on mobile](https://onnxruntime.ai/docs/tutorials/mobile/), model size, execution providers and performance considerations. Inspected October 12, 2026.
[^mcunet]: Ji Lin et al., [MCUNet: Tiny Deep Learning on IoT Devices](https://hanlab.mit.edu/projects/mcunet), official project summary of model and inference-engine co-design, NeurIPS 2020.
Source: https://latentlit.com/edge-ai/index.mdx