---
title: "Local and Cloud Model Collaboration"
description: "How local specialists and stronger cloud models divide work, what the evidence supports, and how to evaluate the complete system."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Local and Cloud Model Collaboration
import FocusCanvas from '../../../components/FocusCanvas.astro';
import SourceFigure from '../../../components/architectures/SourceFigure.astro';
import ModelFlow from '../../../components/architectures/ModelFlow.astro';
import ComparisonTable from '../../../components/ComparisonTable.astro';
A local model does not have to replace a powerful cloud model to be useful.
It can handle routine requests, supply specialized evidence, carry out focused
subtasks or ask for help only when needed. This page explains how those forms
of cooperation work, where they help, and what a convincing evaluation requires.
**The opportunity is a better complete system, not automatically a better answer.**
Apple discloses a product architecture spanning device and server models;
research explores much tighter cooperation. Neither establishes that a hybrid
system always beats a strong cloud baseline.[^apple][^minions]
[Figure 1](#figure-1) gives the central mental model: divide the work, but keep
the data boundary and the authority to act explicit.
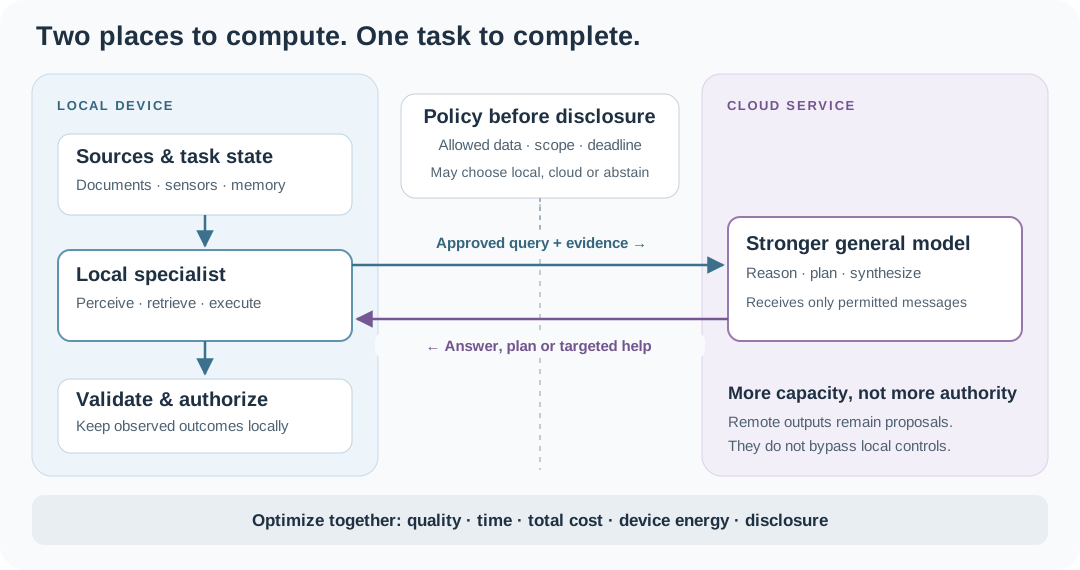
**Figure 1.** Share computation without silently sharing all data or authority. Independent synthesis informed by routing, collaboration and cloud privacy architectures.[^routing][^minions][^pcc]
**Image description:** Local sources feed a specialist. A policy gates requests and evidence sent to a stronger cloud model. Returned answers, plans or help pass local validation and authorization. Quality, time, cost, energy and disclosure constrain the design.
Three distinctions make the rest easier to read:
- **Placement is not capability.** A local model may be a domain specialist;
a cloud model need not be better on every input.
- **Cooperation is not one algorithm.** Choosing a model, exchanging advice,
drafting tokens and splitting layers change different parts of the system.
- **Less cloud use is not less total work.** Count device computation,
communication, checking and failures as well as the API bill.
These are the organizing distinctions used here, not a universal taxonomy.
This is the overview of **Local & Cloud AI**. For the focused architecture
where the cloud agent stays in charge and local models provide perception,
grounding or generation, read
[Cloud Agents & Local Specialists](/local-cloud-ai/cloud-agents-local-specialists/).
For applications to glasses, phones and cameras, see
[Smart Devices & Cloud Agents](/local-cloud-ai/smart-devices-cloud-agents/).
For the surrounding agent and permission boundaries, see
[Agents and hybrid systems](/edge-ai/agents-hybrid-systems/).
## What actually cooperates?
The following comparison synthesizes the cited mechanisms. The unit of work
is often more informative than the label “hybrid AI.”
**Seven ways to divide the work**
| Mechanism | Unit and exchange | Best reason to investigate it | Main constraint |
| --- | --- | --- | --- |
| Request routing | Choose one model before generating | Avoid expensive inference on supported routine requests | Predict relative benefit on the actual workload.[^routing] |
| Answer cascade | Generate locally, check, then escalate if necessary | Inspect a real candidate before paying for more capability | Escalated requests pay for the earlier attempt too.[^frugal] |
| Task decomposition | Exchange instructions and subtask results | Process substantial local context through focused jobs | Coordination, evidence loss and sequential rounds.[^minions] |
| Advisory cooperation | Exchange tailored advice or a targeted question | Add domain adaptation or resolve a specific reasoning bottleneck | Train the communication policy; account for its overhead.[^advisor][^ask] |
| Collaborative decoding | Choose which model generates a token or span | Combine complementary model expertise during generation | Tight inference integration and error propagation.[^collm] |
| Speculative decoding | Draft locally; verify with the cloud target | Accelerate target generation without changing its intended distribution | Acceptance rate, verification access and network scheduling.[^speculative][^specedge] |
| Split inference | Send activations between parts of one network | Fit or schedule a model across hardware boundaries | Activation traffic, repeated synchronization and privacy exposure.[^neurosurgeon][^actinv] |
These can be combined. A router might keep simple requests local and select
a cooperative workflow for harder ones. That composition needs its own
evaluation; results for the individual parts do not establish the whole.
## Better than which baseline?
**Against local only**, a stronger remote model can supply reasoning or
knowledge the local model lacks. **Against cloud only**, the goal is often
similar task quality with less cloud expenditure, better availability or
less data movement. **Higher accuracy than either model alone** is a different
claim: complementary expertise and learned coordination can help, as studied
in Co-LLM, but arbitrary model mixing can also hurt.[^collm]
A fair quality claim must state what the cloud baseline received. Giving the
hybrid system better retrieval, more evidence, additional samples or domain
training can be useful engineering, but it does not isolate a gain from
placing computation on the device. Compare both the product and the mechanism.
The [evaluation plan](#how-to-evaluate-the-complete-system) below separates them.
## Choose before answering, or check an answer first
RouteLLM learns a query conditioned prediction of whether a stronger model
will win, using preference data. Its threshold trades strong model usage for
quality. This is a relative model selection problem, not a universal detector
of difficult questions.[^routing]
A cascade such as FrugalGPT instead examines generated answers and decides
whether another model is needed. The extra observation can improve the
decision, but requires paying for the first generation.[^frugal]
For a device deployment, our proposed policy first removes infeasible routes:
no network, prohibited disclosure, unsupported modality or a deadline the
route cannot meet. It then chooses among local inference, remote inference,
a bounded collaboration or abstention. A useful design objective is:
$$
\begin{aligned}
a^*(x,s)&=\underset{a\in\mathcal A_{\mathrm{allowed}}(x,s)}{\arg\max}\;U(a\mid x,s)\\
U(a\mid x,s)&=\widehat Q-\lambda_C\widehat C-\lambda_T\widehat T-\lambda_E\widehat E
\end{aligned}
\tag{1}
$$
Here $x$ is the request, $s$
includes device and network state, and $a$ is a route
or workflow. $U$ is utility; every estimated quantity
on its right is conditioned on that route, request and state. Those quantities
are task quality, total cost, elapsed
time and device energy. The nonnegative weights convert those quantities to
a common utility scale. Disclosure permission belongs in the allowed set,
not merely in a soft penalty. [Equation (1)](#equation-1) is our design formulation,
informed by budgeted inference, not RouteLLM’s published objective.[^routing][^frugal]
Useful routing signals include retrieval coverage, input type, schema
validation and measured historical success for the model pair. A sentence
such as “I am confident” is not a calibrated probability. Keep threshold
selection separate from final testing, and recheck it after a model or
workload change. RouteLLM’s own overhead experiments used cloud VMs, not
phones, and its authors identify application distribution shift as a limit.[^routing]
## Turn a large task into local work
MinionS has the cloud model prepare focused jobs over short context chunks,
the local model execute them in parallel, and the cloud aggregate selected
results or request another round. Unlike unconstrained model chat, this
deliberately simplifies local work.[^minions]
[Figure 2](#figure-2) shows the original protocol comparison. Its generated
job preparation code is a research mechanism, not permission to execute
untrusted cloud code in an application.
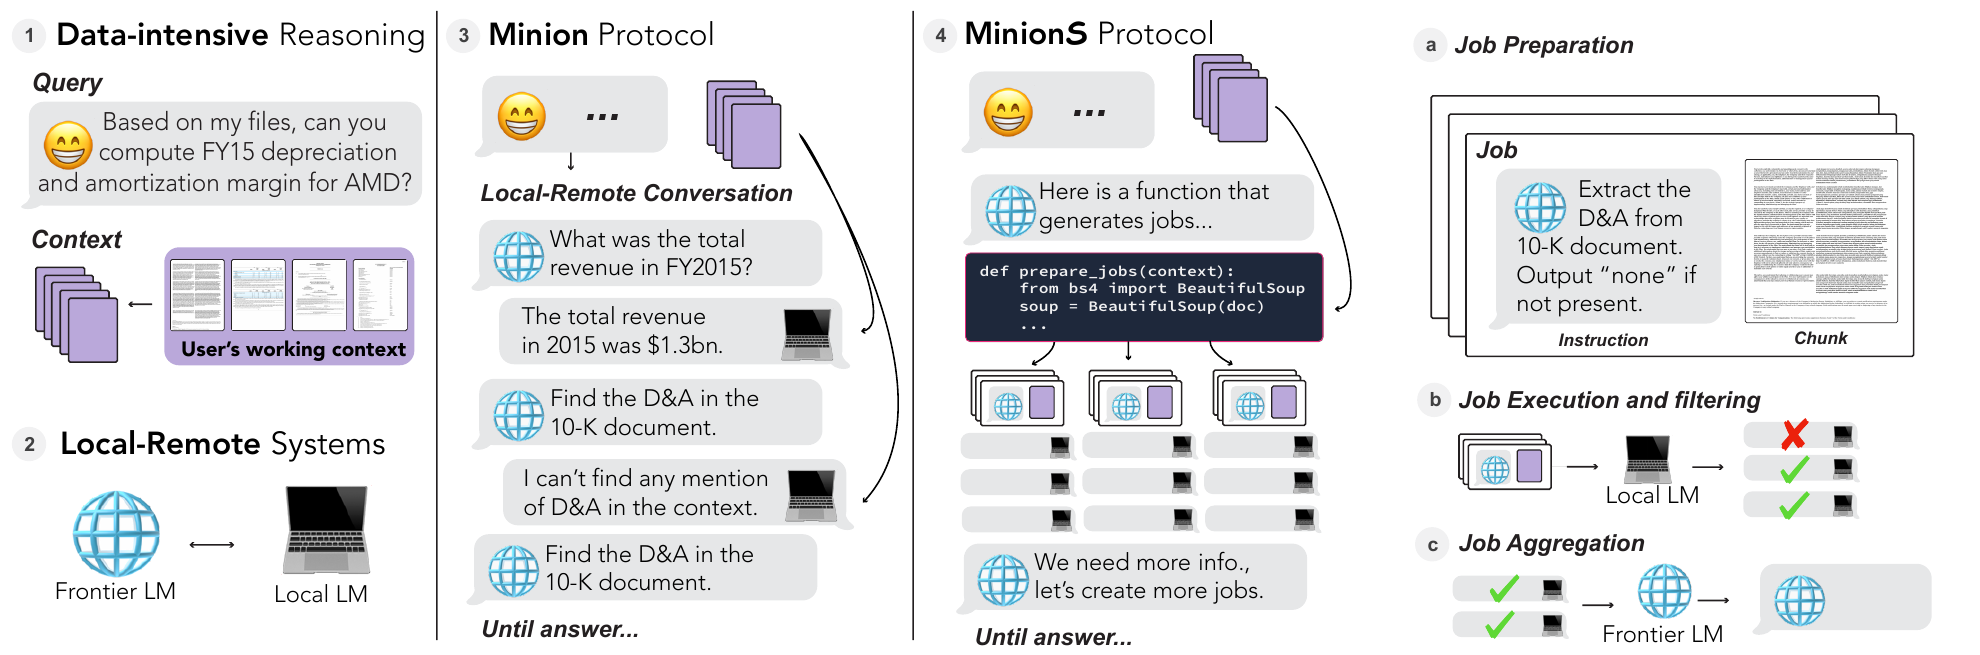
**Figure 2.** Conversation versus parallel jobs. Reproduced from Narayan et al., arXiv v1, Figure 1; caption cropped. CC BY 4.0.[^minions-figure]
**Image description:** Minion uses a local and remote conversation. MinionS prepares jobs, runs local instructions on context chunks, filters results and aggregates them remotely, repeating when needed.
The results have an important boundary: cloud token savings exclude local
hardware and energy, while the published latency experiment can be slower
than cloud only. See the [evidence snapshot](#what-the-measurements-establish).
For implementation, prefer an allowlisted task interface with fixed resource
limits over arbitrary generated programs. Track which source chunks each
result covers. A filtered result can contain an omission or a mistaken
extraction; aggregation does not independently restore missing evidence.
This is our proposed safeguard, not a demonstrated property of the protocol.
## Advice can flow in either direction
**A small model can help a strong one.** Advisor Models trains an open model
with reinforcement learning, using GRPO, to produce input specific advice for a frozen
black box model. The downstream outcome supplies the reward. [Figure 3](#figure-3)
separates that training loop from the inference path.[^advisor]
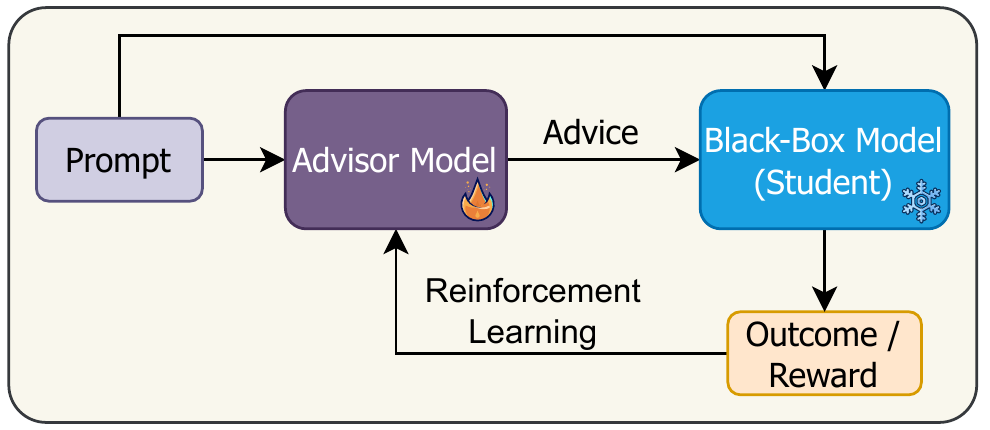
**Figure 3.** Train the advice, not the cloud model. Reproduced from Asawa et al., v2, Figure 1; caption cropped. CC BY 4.0.[^advisor]
**Image description:** The prompt reaches an advisor and a frozen black box model. Advice guides the black box output; outcome reward trains the advisor, not the black box model.
The paper reports gains on specialized tasks, but no significant improvement
in its MATH-500 limit study. It establishes an adaptation mechanism, not
measured phone efficiency. Frozen weights also do not guarantee that every
new advice prompt preserves output quality.[^advisor]
**A local model can instead ask a stronger one for help.** The October 2026
preprint *Learning to Ask* trains whether to consult, how to construct a
focused query, and how to use the answer. Its reasoning model and separate
Qmaker are both based on Qwen2.5-7B. Crucially, the evaluated design allows
at most one advisor interaction per trajectory; its budget experiments are
not a demonstrated general multi-round device agent.[^ask]
Conductor explores another direction: a trained 7B model chooses worker
instructions and communication structure. It is evidence about learned
orchestration, not proof that the conductor was benchmarked on a handset.
Its reported benchmark leadership is a dated paper result, not a current
universal ranking.[^conductor]
## Token cooperation is two different ideas
Co-LLM learns when a base model should defer token generation to an assistant.
The goal is to combine expertise and change generation quality. Its learned
deferral threshold needs task tuning; an assistant mistake can disrupt later
generation. Using a fine cooperation unit can also introduce a demanding
network synchronization problem when models are separated physically.[^collm]
**Exact speculative decoding has a different goal:** a cheap model proposes
tokens and the target verifies them with the appropriate acceptance and
correction procedure. Under the algorithm’s assumptions, the output has the
target distribution. That is not a guarantee that the target is correct, and
a cloud critique of a local answer is not this verification procedure.[^speculative]
SpecEdge places drafting on edge GPUs and verification on the server. It
overlaps drafting with verification and schedules multiple requests to keep
the server busy. This needs control of the serving path, not just a generic
chat endpoint. Its evaluated edge resources are consumer GPUs from edge
providers, which must not be confused with battery powered phones.[^specedge]
For the local inference mechanics, see
[Efficient inference](/edge-ai/efficient-inference/).
## Splitting a network is not splitting a task
Neurosurgeon predates current LLMs: its 2017 system chooses a layer boundary
between mobile and cloud computation across studied neural networks.
It sends an intermediate representation, not a subtask instruction to an
independent model.[^neurosurgeon]
In an autoregressive split, repeated activation exchange can become the
bottleneck. As an illustrative storage calculation, one tensor with 2,048
positions, width 4,096 and two bytes per value occupies **16 MiB**. Sending
that tensor over a 20 Mbit/s uplink takes about **6.71 seconds** for payload
alone. This is a hypothetical dense tensor, not a measured or necessary
handoff size; it excludes protocol overhead, compression and computation.
Fewer raw pixels or tokens leaving the device does not establish privacy.
ActInv studies reconstruction from split LLM activations under a passive
server threat model with full model knowledge. Its findings challenge the
assumption that hidden states inherently conceal the prompt; they do not
establish the same attack success against every split or protected service.[^actinv]
## What the measurements establish
This is an evidence comparison, not a leaderboard. Models, objectives,
hardware and accounting differ between rows. Numbers below are reported
findings, not experiments reproduced here.
**Promising results, different contracts**
| Study | Reported result | Boundary that changes interpretation |
| --- | --- | --- |
| RouteLLM, v4, 2025 | Table 6 reports a 3.66× cost saving ratio at 95% of GPT-4 quality on MT Bench | Historical model/pricing assumptions; not a device benchmark or 95% correctness.[^routing] |
| Minions, ICML 2025 | 97.9% of remote-only performance at 5.7× lower cloud cost; RTX 4090 MinionS latency 2.15–2.89× cloud only | Three-task headline; latency uses ten LongHealth samples; local hardware and energy excluded from monetary cost.[^minions] |
| Advisor Models, v2, 2026 | GPT-5 RuleArena Taxes accuracy rises from 31.2% to 53.6% | Specialized easiest-level subset with 25 held-out examples; not a broad or device result.[^advisor] |
| SpecEdge, v2, 2025 | 2.22× server throughput, 1.91× cost efficiency, 11.24% lower inter-token latency on average | A100 plus RTX 4090s, 14.07 ms RTT, primarily against server-only tree speculative decoding. Not whole-request latency or a phone result.[^specedge] |
The two Minions percentages answer different questions: relative task
performance is not absolute accuracy, and cloud expenditure is not system
cost. Likewise, server throughput, generation step count, answer correctness
and user waiting time are not interchangeable metrics.
## Is this a real deployment direction?
**Yes, with different maturity levels.** Apple’s June 2026 foundation model
disclosure, updated September 9, describes two device models and three server
models, with Cloud Pro assigned demanding reasoning and tool use. This
supports a concrete hybrid product architecture, not an independently
measured share of traffic using each route.[^apple]
The original 2025 Gemini Robotics report specifies a cloud VLA backbone and
a local action decoder. Google’s separate June 2025 On-Device announcement
describes a model operating without a data network. These are distinct,
dated designs, not interchangeable claims that all robotics uses cloud
planning or that every newer release has the same boundary.[^robotics][^robotics-local]
Hazy Research’s May 2026 retrospective describes collaboration and routing
patterns in OpenJarvis. It is a useful first-party ecosystem signal, not
independent evidence of market-wide adoption or general performance.[^ecosystem]
The practical conclusion is narrower than “everything will be hybrid”:
**the design space is established; the best partition remains workload specific.**
## Make the handoff an evidence contract
A local component can contribute something more useful than a shorter
paragraph: a source passage, a table with units, a chart crop, an observed
event or a domain constraint. Our proposed handoff retains:
- Source identity, version, page or timestamp, and exact region when relevant.
- Observations separately from model interpretations and unresolved alternatives.
- Units, relationships and missing values, rather than only a fluent summary.
- Permitted use, disclosure scope and a way to request additional evidence.
For a VLM system, compare text summaries, structured extraction, selected
image crops and original multimodal input. A caption may lose tiny labels,
spatial relations or negative evidence. Treat the representation as an
experimental choice, not a free compression step. The information bottleneck
also appears explicitly in *Learning to Ask*’s limitations.[^ask]
Private source processing does not make derived messages private: names,
preferences and document facts may survive in a summary. Apple’s PCC is an
explicit security architecture; “we only send embeddings” is not an
equivalent guarantee.[^pcc][^actinv]
## A worked document assistant design
Consider a hypothetical assistant answering questions across a user’s
documents, tables and figures. The following is a proposed design, not a
measured deployment.
Local parsing and retrieval preserve original evidence. A local specialist
can answer supported routine questions; a permitted cloud path reasons over
selected evidence or asks for a specific missing crop. Neither route may
silently send the whole collection. [Figure 4](#figure-4) separates evidence
preparation from bounded assistance and validation.
**Preserve evidence, request bounded help, verify the result**
**Local evidence preparation**
1. **Read approved sources**: Keep originals and access scope
2. **Parse and retrieve**: Text, tables, figures and exact locations
3. **Try a supported task**: Local specialist with measurable checks
4. **Choose the next route**: Return, clarify, abstain or permit cloud help
A retrieval miss can require a better source, not a larger model. Check missing units, conflicting pages and uncertain visual details.
**Permitted assistance and return**
1. **Package bounded evidence**: Locations, observations, alternatives and budget
2. **Request cloud reasoning**: Targeted question; no implicit full-library access
3. **Validate against originals**: Claims, calculations, schema and requested crops
4. **Return or seek review**: Cited answer, correction or explicit uncertainty
If the cloud asks for more evidence, return to local retrieval and the disclosure gate. Limit rounds, bytes and time. Only authorized code can execute effects.
**Figure 4.** A proposed specialist and generalist workflow. Independent synthesis of retrieval, bounded consultation and explicit control boundaries.[^minions][^ask][^pcc]
For “How did the margin change?”, the local handoff might retain both period
labels, numerator and denominator, units, table locations and a conflicting
footnote. The cloud contributes interpretation; deterministic code checks
the arithmetic. If a graph label is unreadable, request that crop rather
than turn a local guess into a cloud fact. This example claims no measured gain.
Related application hypotheses include a camera that escalates selected
ambiguous events, a wearable that asks for help interpreting a user selected
scene, or a robot with an independently specified local control and safety
path. Each requires its own data, deadline and failure analysis. A model’s
proposed explanation is not a safety controller.
## Account for the complete critical path
A cascade can improve mean latency while making escalated requests slower.
Under a simple serial model with constant local time
$t_L$, checking time $t_V$,
escalation fraction $p$, and complete cloud time
$t_C$:
$$
\mathbb E[T_{\mathrm{cascade}}]=t_L+t_V+p\,t_C
\tag{2}
$$
[Equation (2)](#equation-2) is our elementary accounting model, not a measured speedup.
With 0.35 seconds locally, 0.05 seconds checking, a 1.2 second cloud path and
20% escalation, the mean is **0.64 seconds**. But an escalated request takes
**1.60 seconds**, longer than cloud only. These hypothetical values omit
variance, loading, contention, caching and parallel work.
For a serial cooperative route, a more explicit approximation is:
$$
\begin{aligned}T_{\mathrm{serial}}\approx{}&T_{\mathrm{load}}+T_L+T_C+T_V\\&+\sum_{r=1}^{R}\mathrm{RTT}_r+\frac{B_{\uparrow}}{U}+\frac{B_{\downarrow}}{D}\end{aligned}
\tag{3}
$$
Here $T_C$ includes remote queueing and computation,
not network transfer; RTT accounts for exchange latency excluding the payload
serialization terms. $B$ is bytes transferred and
$U,D$ are effective bytes per second. Separate payload
and RTT this way to avoid counting the same transfer twice. Real pipelines
can overlap these terms, as SpecEdge demonstrates, so measure their critical
path instead of blindly adding them.[^specedge]
Track cloud billing separately from device energy, network energy and hardware
cost. A smaller model processing many chunks or staying resident continuously
can consume more resources than an occasional cloud request. That is a
possibility to measure, not a universal energy claim. See
[Evaluation and profiling](/edge-ai/evaluation-profiling/) and
[On device computing](/edge-ai/on-device-computing/).
## How to evaluate the complete system
Our proposed evaluation begins with a fixed task distribution, data access
policy, device class and service target. Define “better” before choosing a
router. Use held-out data by user, source or time as appropriate, not just
random neighboring chunks from the same documents.
**What each baseline rules out**
| Baseline | What it tests | What must remain comparable |
| --- | --- | --- |
| Local only | Does assistance add useful capability? | Local model, tools, data and task scope |
| Cloud with original permitted evidence | Does cooperation beat the strongest practical single model path? | Information access, samples, reasoning budget and disclosure policy |
| Cloud with the same local retrieval or extraction | Is the gain just better evidence preparation? | Identical evidence artifacts and retrieval budget |
| Simple rules and random routing | Is learning worth the training and serving overhead? | Cloud usage or total cost budget |
| Learned routing or proposed cooperation | Does the actual deployed policy deliver the claimed benefit? | Thresholds selected before testing; full runtime accounting |
| Offline routing oracle | How much room remains in choosing one model per request? | Same candidate outputs; no deployable access to test labels |
An oracle over whole-request choices is only an upper bound for that choice
set, not all forms of cooperation. A workflow that exchanges new information
can exceed it without a paradox; the action space is different.[^ask]
Report task correctness or completion, evidence completeness, unsupported
claims, abstention and error severity. Then measure **p50/p95 complete task
latency**, first useful response, bytes, actual cloud expenditure, device
joules and peak/resident memory. For continuous workloads, add energy over
time and missed events. Do not compare a server’s token rate to an
application’s completed task time.
Stratify the results by input length, layout, language, ambiguity, device
temperature, cold start and network state. Include disconnects, deadline
expiry, model updates and contradictory evidence. Test disclosure violations
and the path that requests additional data. If using a model judge, audit
its decisions on a human checked subset. Keep held-out prompts and evaluation
labels out of router and collaborator training.
Finally, plot the **quality versus total cost frontier** at a fixed latency
target, and the **quality versus latency frontier** at a fixed budget. Include
uncertainty and training/maintenance costs where they affect the decision.
One attractive average can hide the domain or network slice that fails.
## When not to add another model
Prefer a simpler route when direct cloud inference already satisfies the
privacy, cost and response requirements; when the local intermediate loses
essential evidence; or when repeated communication exceeds the deadline.
Prefer local only when connectivity or disclosure constraints rule out the
remote path. Better retrieval or a deterministic tool may fix the actual
problem without a second generative model.
Training is another alternative. [Knowledge Distillation](/knowledge-distillation/)
can move some capability into the local model before deployment. That is
different from consulting the teacher during each request. A useful research
question is whether recurring cloud assistance can become reviewed training
data for a future local release, with held-out regression and privacy checks.
It is not permission for uncontrolled online self-training.
The strongest opportunities appear to be **learning what help is worth asking
for, preserving evidence across the boundary, and adapting the cooperation
granularity to the hardware and network**. This is our synthesis, not a
claim that one protocol is universally best. Start with a measurable domain,
one clear handoff and strong single model baselines before adding more rounds.
Primary mechanisms and selected current disclosures inspected October 17,
2026. Recent preprints remain provisional. No model training, device
benchmark, independent reproduction or market-adoption measurement was run.
[^apple]: Apple. [Introducing the Third Generation of Apple’s Foundation Models](https://machinelearning.apple.com/research/introducing-third-generation-of-apple-foundation-models), June 8, 2026; updated September 9, 2026. Model family and execution targets inspected October 17, 2026.
[^minions]: Avanika Narayan et al. [Cost-efficient Collaboration between On-device and Cloud Language Models](https://proceedings.mlr.press/v267/narayan25a.html), ICML 2025, PMLR 267:45682–45719. Published PDF sections 3–6, Table 1 and Table 2. Latency experiment uses ten LongHealth samples; monetary cost excludes local hardware and energy.
[^routing]: Isaac Ong et al. [RouteLLM: Learning to Route LLMs with Preference Data](https://arxiv.org/html/2406.18665v4), ICLR 2025, arXiv v4, February 23, 2025. Sections 3–5, Table 6, routing overhead and distribution-shift limitations.
[^pcc]: Apple Security Engineering and Architecture et al. [Private Cloud Compute: A new frontier for AI privacy in the cloud](https://security.apple.com/blog/private-cloud-compute/), June 10, 2024. Security design, disclosure and trust boundaries; inspected October 17, 2026. Historical architecture, not a claim that every current deployment uses the original hardware.
[^frugal]: Lingjiao Chen, Matei Zaharia and James Zou. [FrugalGPT: How to Use Large Language Models While Reducing Cost and Improving Performance](https://arxiv.org/html/2305.05176v1), 2023, section 3, LLM cascade, and section 5, limitations.
[^advisor]: Parth Asawa, Alan Zhu, Abby O’Neill, Matei Zaharia, Alexandros G. Dimakis and Joseph E. Gonzalez. [How to Train Your Advisor: Steering Black-Box LLMs with Advisor Models](https://arxiv.org/html/2510.02453v2), v2, February 2, 2026. Sections 3, 4.1–4.2 and 4.4.4; Figure 1. Preprint; PDF cover dates the preprint February 3.
[^ask]: Yongjun Kim, Xiaoxiao Li and Jaeho Lee. [Learning to Ask: Information Acquisition for SLM-LLM Collaboration, under a budget](https://arxiv.org/html/2610.01236v1), October 1, 2026 preprint. Sections 5–6 and Appendix A: one consultation per trajectory, separate query model, weighted API cost and incomplete system accounting.
[^collm]: Shannon Zejiang Shen et al. [Learning to Decode Collaboratively with Multiple Language Models](https://arxiv.org/html/2403.03870v1), March 6, 2024 preprint; subsequently ACL 2024. Sections 3–5, especially deferral learning, threshold selection and error propagation. Mechanism discussion uses this inspected arXiv edition.
[^speculative]: Yaniv Leviathan, Matan Kalman and Yossi Matias. [Fast Inference from Transformers via Speculative Decoding](https://arxiv.org/html/2211.17192v2), 2023, sections 2–3 and Algorithm 1. Distribution preservation requires the specified verification, acceptance and correction procedure.
[^specedge]: Jinwoo Park, Seunggeun Cho and Dongsu Han. [SpecEdge: Scalable Edge-Assisted Serving Framework for Interactive LLMs](https://arxiv.org/html/2505.17052v2), NeurIPS 2025, arXiv v2, November 18, 2025. Sections 4–5 and Appendix A; main baseline is server-only tree speculative decoding, with A100 and edge RTX 4090 resources.
[^neurosurgeon]: Yiping Kang et al. [Neurosurgeon: Collaborative Intelligence Between the Cloud and Mobile Edge](https://ypkang.github.io/downloads/kang17neurosurgeon.pdf), ASPLOS 2017, pages 615–629. Abstract, introduction and layer partitioning design; historical neural-network mechanism, not an LLM benchmark.
[^actinv]: Mingyuan Fan, Yu Liu, Fuyi Wang and Cen Chen. [What Does the Server See? Understanding Privacy Leakage from Large Language Models in Split Inference](https://arxiv.org/html/2605.23158v1), May 22, 2026 preprint, sections 3–4. Passive server with full model knowledge; this review does not adopt unfinished publication-template metadata as venue evidence.
[^minions-figure]: Avanika Narayan et al. [Minions: Cost-efficient Collaboration Between On-device and Cloud Language Models](https://arxiv.org/html/2502.15964v1), February 21, 2025, Figure 1, PDF page 2. [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/); scientific diagram unchanged, surrounding caption/prose cropped. See [asset provenance](/figures/edge-ai/local-cloud-collaboration/SOURCES.md).
[^conductor]: Stefan Nielsen et al. [Learning to Orchestrate Agents in Natural Language with the Conductor](https://arxiv.org/html/2512.04388v1), December 4, 2025 preprint, abstract and introduction. Learned coordination over worker pools; no handset efficiency claim is inferred here.
[^robotics]: Gemini Robotics Team. [Gemini Robotics: Bringing AI into the Physical World](https://storage.googleapis.com/deepmind-media/gemini-robotics/gemini_robotics_report.pdf), 2025, section 3.1 and Figure 14. Original cloud backbone and onboard action decoder design.
[^robotics-local]: Carolina Parada, Google DeepMind. [Gemini Robotics On-Device brings AI to local robotic devices](https://deepmind.google/blog/gemini-robotics-on-device-brings-ai-to-local-robotic-devices/), June 24, 2025. Historical on-device model announcement, not the complete current robotics product catalog.
[^ecosystem]: Jon Saad-Falcon and Avanika Narayan, Hazy Research. [From Minions to OpenJarvis: A Retrospective on Two Years in Local AI](https://hazyresearch.stanford.edu/blog/2026-05-15-minions-to-openjarvis-retrospective), May 15, 2026, Hybrid capabilities. First-party project account, not independent adoption evidence.
Source: https://latentlit.com/edge-ai/local-cloud-collaboration/index.mdx