---
title: "Runtimes & Compilers"
description: "Follow a model from export to kernels, and understand shapes, memory planning, acceleration and device fallback."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Runtimes & Compilers
import FocusCanvas from '../../../components/FocusCanvas.astro';
import SourceFigure from '../../../components/architectures/SourceFigure.astro';
import ComparisonTable from '../../../components/ComparisonTable.astro';
A trained model describes a computation. An application needs a program that can
execute that computation on its target device, allocate memory, move inputs and
return results. The route between these two is where runtimes and compilers matter.
The same weights can perform differently when operator implementations, tensor
layouts, shapes or processor assignments change.
Treat a deployment as a specific combination of **model, runtime, backend,
device, precision and versions**. Support for an accelerator is not a promise
that every model will run entirely on it. ExecuTorch documents partial delegation
and CPU fallback; ONNX Runtime assigns supported graph regions to execution
providers.[^executorch-export][^ort-ep]
This page explains that execution route and compares useful software boundaries.
For chip roles, memory arrangements and current devices, read
[On device computing](/edge-ai/on-device-computing/). For workload budgets,
read [Edge AI foundations](/edge-ai/foundations/).
For weight representation, continue with [quantization and compression](/edge-ai/quantization-compression/).
## Separate the program from its execution
An **operator** is a computation such as matrix multiplication. A **kernel** is
a particular implementation of it. A **backend** connects execution to a target
processor or library. A **runtime** loads the program and manages its execution;
a compiler or conversion tool can prepare that program before the app runs.
ExecuTorch uses these distinctions in its concepts guide.[^executorch-concepts]
The boundary is not always one compiler followed by one runtime. Some work is
performed ahead of time; some optimization or device compilation occurs at
session initialization. An optimized artifact can depend on the intended
hardware and execution-provider settings.[^ort-graph]
[Figure 1](#figure-1) is ExecuTorch's own view of this boundary. The dashed box
contains ahead-of-time preparation: graph export, target compilation, memory
planning and kernel selection. The runtime sits outside it and executes operators
and delegates. This is one stack's organization, not a universal pipeline or a
claim that initialization has no work left to do.[^executorch-diagram]
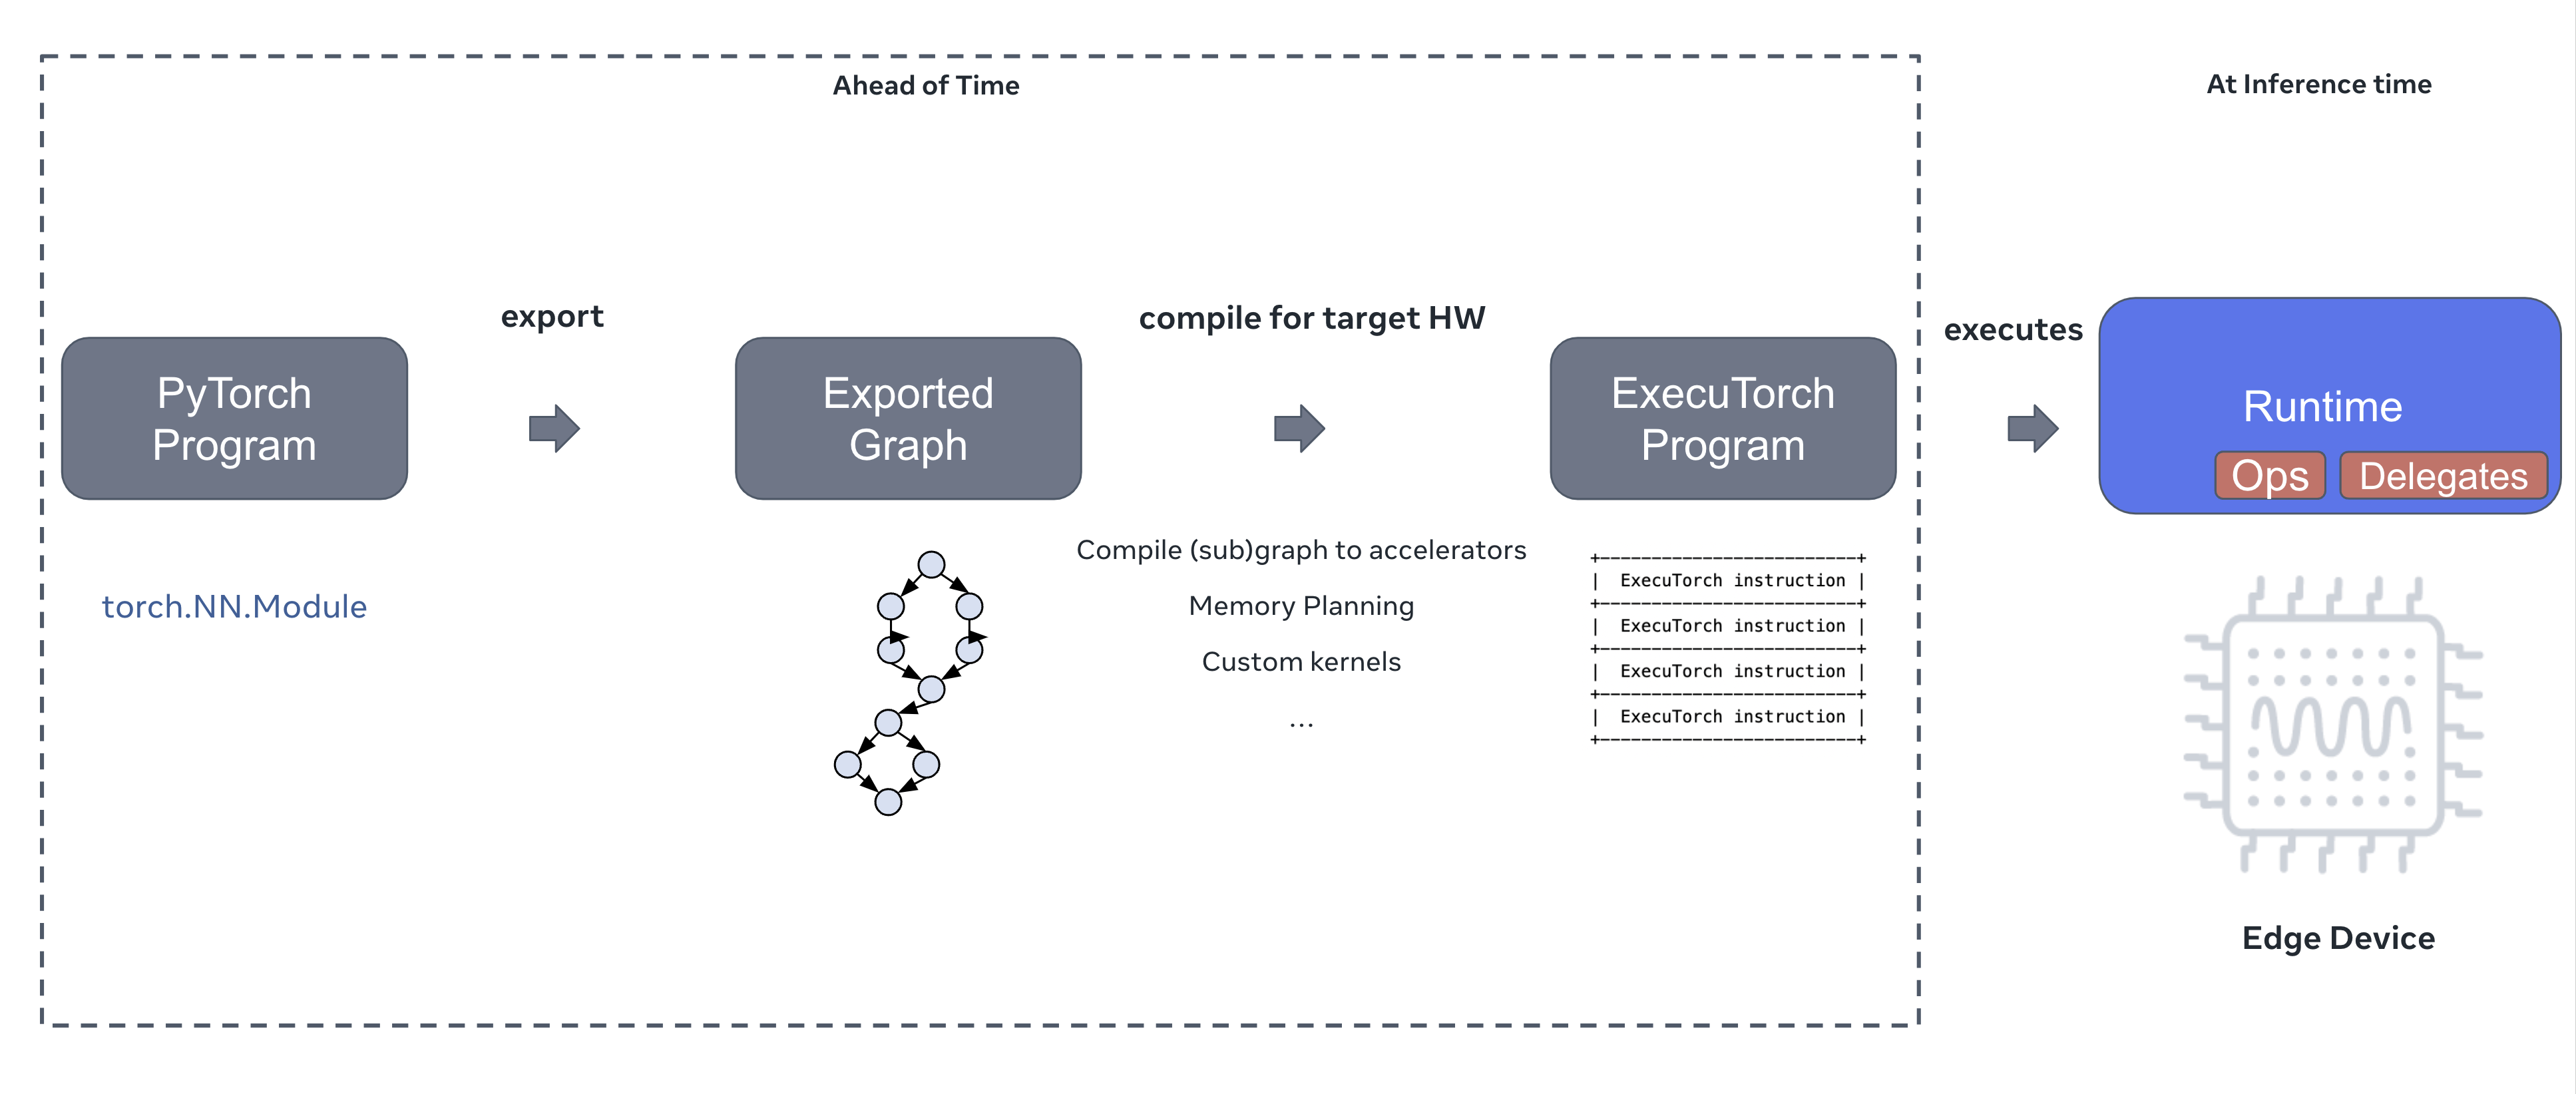
**Figure 1.** Ahead-of-time preparation and inference-time execution. Reproduced unchanged from the official ExecuTorch guide, asset revision September 25, 2023, retained in the inspected 1.5 documentation; BSD license.[^executorch-diagram]
**Image description:** Official ExecuTorch high-level pipeline: ahead of time, a PyTorch program becomes an exported graph and then a target-hardware ExecuTorch program, with accelerator subgraph compilation, memory planning and custom kernels. At inference time, the runtime executes operators and delegates on the edge device.
## Export makes assumptions explicit
**Export** turns the model into a graph with a specified input contract.
An **intermediate representation**, or IR, gives tools a form they can inspect
and transform. **Lowering** moves the graph toward operations and formats
supported by the selected backend. In the inspected ExecuTorch 1.5 guide,
PyTorch export is followed by backend transformation and lowering, then
serialization to a `.pte` program.[^executorch-export]
Check more than successful conversion. Preserve the tokenizer or input processor,
normalization, layout, masking, special tokens and output interpretation. Test
the exported model against the reference on representative inputs. A program
that produces a tensor of the expected shape can still produce the wrong answer.
The export contract should state the supported batch, prompt length, image size
or audio duration. A sample input used during export is not, by itself, evidence
that arbitrary sizes work.
## Shapes affect both optimization and memory
A **static shape** fixes tensor dimensions. A **dynamic shape** permits some to
vary, often within declared bounds. Predictable shapes give a compiler more
information; unrestricted variation can reduce optimization opportunities or
require more complex allocation. ExecuTorch's memory planner propagates tensor
sizes and lifetimes and evaluates dynamic dimensions using their bounds.[^executorch-memory]
Consider a proposed image encoder accepting 224 × 224 and 448 × 448 inputs. A
finite set of variants may fit the product better than accepting any resolution.
Padding every image to the largest shape has a cost; generating many variants
has package and maintenance costs. Core ML provides enumerated and ranged shapes,
and documents that the first prediction for a non-default enumerated shape may
be slower than subsequent predictions.[^coreml-shapes]
For a decoder, distinguish the prompt-processing shapes from the one-position
decode path and the growing cache. A runtime may use separate methods, buckets
or fixed-capacity state. Test the transition at each supported boundary, including
an empty or tiny input and the maximum permitted context.
### Plan lifetimes, not just tensor sizes
Two buffers that are never live together can share storage. A simple teaching
example has an 8 MiB intermediate that dies before a later 6 MiB temporary is
created. Reusing its region requires **8 MiB**, compared with **14 MiB** if both
receive separate storage. If the first tensor remains needed for a residual
connection, that reuse is invalid. This is a local example of lifetime planning,
not a measured saving for a model.[^executorch-memory]
Count persistent weights and attention state separately from the transient
arena. Include backend allocations, input/output buffers and initialization
peaks. A planner's arena size does not establish the process's total peak memory.
See [efficient inference](/edge-ai/efficient-inference/#the-context-is-a-growing-working-set)
for the KV-cache calculation.
## Fusion and kernels change the physical work
Graph transformations can remove redundant nodes, fold constant computation and
combine compatible operations. ONNX Runtime documents basic rewrites before
partitioning and further fusions after provider assignment; which fusion applies
depends on the graph and provider.[^ort-graph]
For intuition, a separate matrix multiplication, bias addition and activation
can require intermediate writes and separate dispatches. A fused implementation
may keep intermediate values closer to the processor and avoid some of those
costs. That is a candidate mechanism, not proof that a particular graph has been
fused. Inspect the lowered graph and execution trace.
The same operator name can have very different performance at batch one versus
a large batch, or for one token versus a long prompt. Check the actual precision,
layout and kernel implementation. A 4-bit weight file does not imply 4-bit
activation arithmetic throughout the program.
## Partial acceleration can be expensive
A model may have two large accelerated regions separated by one unsupported
operation. Executing that operation on the CPU can require synchronization,
transfers or layout conversion at both boundaries. ONNX Runtime's model usability
checker reports both supported nodes and partition counts, and explicitly warns
that switches between supported and unsupported regions can affect performance.[^ort-checker]
[Figure 2](#figure-2) isolates the costs that a supported-node percentage hides.
The accelerated regions are separated by a CPU operation, so each crossing must
be included in the complete path. The diagram and calculation use hypothetical
serial timings; overlapping execution requires its own trace.
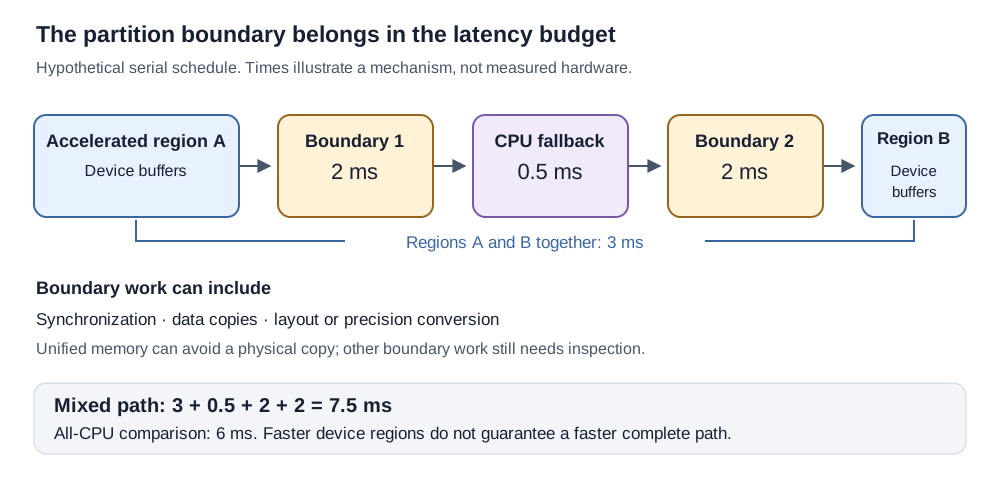
**Figure 2.** Faster regions, slower complete path. Latent Light illustrative derivation using the numbers below, informed by ONNX Runtime partition and I/O documentation; no device measurement.[^ort-checker][^ort-io]
**Image description:** Hypothetical serial mixed-processor path: accelerated regions A and B together take 3 ms, a CPU fallback takes 0.5 ms and two processor boundaries take 2 ms each. Total 7.5 ms loses to an illustrative all-CPU baseline of 6 ms. Boundaries can include synchronization, copies and format conversion.
Use an illustrative serial schedule with **3 ms** on an accelerator,
**0.5 ms** on the CPU and **2 ms** at each of two boundaries:
$$
t_{\mathrm{partitioned}}=3+0.5+2+2=7.5\ \mathrm{ms}
\tag{1}
$$
If the measured all-CPU path were **6 ms**, that partition would lose, despite
its fast accelerator regions. These values are hypothetical. On unified-memory
systems a boundary may not copy physical bytes, but synchronization, buffer
ownership and format conversion still need inspection. Do not assume the
example applies to every CPU/GPU/NPU combination.
ONNX Runtime's I/O Binding documentation explains another boundary: inputs or
outputs not resident on a non-CPU provider's target can be copied as part of
`Run()`. Keeping an appropriate buffer on the device can remove avoidable
round trips, provided the next consumer can use it there.[^ort-io]
## Compare the boundaries, not a universal winner
The following comparison is a Latent Light synthesis of official material
inspected **October 12, 2026**. Mutable guides describe supported paths, not an
execution test of any model or device. Pin exact tool, SDK, driver and OS versions
for a deployment.
**Where each stack enters the deployment**
| Path | Main boundary | Useful fit | What remains to verify |
| --- | --- | --- | --- |
| ExecuTorch | PyTorch export and lowering to a backend-specific `.pte`; unsupported portions may use CPU fallback.[^executorch-export] | A PyTorch-based model pipeline with explicit backend preparation | Export semantics, delegation coverage, shape bounds and runtime build |
| LiteRT | `.tflite` model format and the `CompiledModel` execution API for targeted accelerators.[^litert] | A device ML pipeline using supported conversion and buffer APIs | Model operators, platform distribution and the selected accelerator |
| LiteRT-LM | An orchestration layer for LLMs running with LiteRT; current documentation includes multimodal and tool-use paths.[^litert-lm] | An application needing language-model sessions and generation integration | Specific model packaging, modality/backend coverage and SDK release |
| Core ML | Apple model conversion, platform runtime and configurable input shapes; stateful models can retain mutable state.[^coreml-shapes][^coreml-state] | A deployment within supported Apple platforms | Deployment target, actual compute placement, supported shapes and state behavior |
| ONNX Runtime | ONNX graph execution through execution providers that claim supported nodes or subgraphs.[^ort-ep] | A pipeline using ONNX and provider-specific integration | Opset/kernel coverage, provider version, partition count and transfers |
| llama.cpp | C/C++ inference built on ggml, GGUF model artifacts and several CPU/accelerator backends.[^llama][^llama-models] | A supported local LLM/VLM with direct generation tooling | Model architecture and quantization support, backend build, offload choices and app lifecycle |
| Vendor backend or SDK | For example, ONNX Runtime's QNN provider targets Qualcomm tooling and documents operator/data-type restrictions.[^qnn] | A known device family whose specialized execution path is worth testing | SDK/runtime compatibility, supported precision, compiler settings and distribution terms |
These paths can overlap: an application-facing runtime may delegate to a vendor
backend or another platform's runtime. A general model runtime may also need a
separate generation loop, tokenizer and multimodal preprocessing. Compare the
same application boundary when deciding between them.
The LiteRT overview itself distinguishes platform packaging maturity: its
inspected Apple-platform guidance separates the LiteRT-LM Swift package from the
LiteRT runtime's nightly Swift distribution. A cross-platform headline therefore
does not establish identical packaging or feature maturity everywhere.[^litert]
## Precision and state belong in the contract
Check **storage precision**, **arithmetic precision** and **state precision**
separately. A backend may accept an operator only for selected data types or
attributes. The QNN provider's documented MatMul and Gather restrictions are
examples of why an operator name alone is insufficient.[^qnn]
State placement also matters. Core ML's stateful model interface lets the model
runtime update state without explicitly passing and copying it between every
prediction. Its guide describes a KV-cache example and platform requirements;
the interface is not proof that a particular conversion is optimal.[^coreml-state]
Retain a compact deployment manifest: model/checksum, input processing and
tokenizer revision, conversion command, runtime release, backend/SDK versions,
OS and device, shape limits, precision, cache policy and fallback behavior. Keep
the generated artifact tied to that manifest so a later compiler upgrade can be
evaluated as a real change.
## Debug from correctness to the execution trace
A useful proposed sequence is to confirm reference outputs, confirm converted
outputs, inspect accelerated partitions, then profile the complete application
path. When a regression appears, ask whether a graph rewrite, kernel, transfer,
allocation or initialization changed.
Measure both cold initialization and repeated execution. Compare a reasonable
CPU baseline to the candidate accelerator path. Test the maximum workload as
well as the typical one. Preserve a fallback that satisfies the application's
quality and latency requirements rather than merely accepting any output.
Continue with [evaluation and profiling](/edge-ai/evaluation-profiling/) to turn
those checks into reproducible evidence, and [production and product design](/edge-ai/production-product-design/)
for app lifecycle, release and recovery decisions.
[^executorch-export]: PyTorch, [Model Export and Lowering](https://docs.pytorch.org/executorch/stable/using-executorch-export.html), ExecuTorch 1.5 documentation inspected October 12, 2026. The Export and Lowering Process and Hardware Backends sections; the stable URL is mutable.
[^ort-ep]: ONNX Runtime, [Execution Providers](https://onnxruntime.ai/docs/execution-providers/), inspected October 12, 2026. `GetCapability()` and subgraph assignment; mutable documentation.
[^executorch-concepts]: PyTorch, [Concepts](https://docs.pytorch.org/executorch/stable/concepts), ExecuTorch 1.5 documentation inspected October 12, 2026. Kernel, lowering and memory-planning definitions.
[^ort-graph]: ONNX Runtime, [Graph Optimizations](https://onnxruntime.ai/docs/performance/model-optimizations/graph-optimizations.html), inspected October 12, 2026. Basic and Extended Graph Optimizations and Online/Offline Mode.
[^executorch-memory]: PyTorch, [Memory Planning](https://docs.pytorch.org/executorch/1.5/compiler-memory-planning.html), ExecuTorch 1.5. Overview: tensor sizes, lifetimes, fixed arenas and dynamic shape bounds. Inspected October 12, 2026.
[^coreml-shapes]: Apple, [Flexible Input Shapes](https://apple.github.io/coremltools/docs-guides/source/flexible-inputs.html), Core ML Tools guide inspected October 12, 2026. EnumeratedShapes, ranged dimensions and default-shape preallocation.
[^ort-checker]: ONNX Runtime, [Model Usability Checker](https://onnxruntime.ai/docs/tutorials/mobile/helpers/model-usability-checker.html), inspected October 12, 2026. Supported/unsupported operators, dynamic-shape caveats, partition counts and required performance testing.
[^ort-io]: ONNX Runtime, [I/O Binding](https://onnxruntime.ai/docs/performance/tune-performance/iobinding.html), inspected October 12, 2026. Target-device inputs and outputs and copies inside `Run()`.
[^litert]: Google, [Getting started with LiteRT](https://developers.google.com/edge/litert/overview), inspected October 12, 2026. Model format, CompiledModel examples and the platform-specific installation guidance; mutable documentation.
[^litert-lm]: Google, [LiteRT-LM Overview](https://developers.google.com/edge/litert-lm/overview), inspected October 12, 2026. Orchestration, supported platform families, modalities and tool use; specific release/model combinations still require verification.
[^coreml-state]: Apple, [Stateful Models](https://apple.github.io/coremltools/docs-guides/source/stateful-models.html), Core ML Tools guide inspected October 12, 2026. State inputs, conversion, platform availability and KV-cache example.
[^llama]: ggml-org, [llama.cpp README](https://github.com/ggml-org/llama.cpp/blob/master/README.md), master branch inspected October 12, 2026. Description and Supported backends; moving branch, not a pinned deployment build.
[^llama-models]: ggml-org, [Obtaining and quantizing models](https://github.com/ggml-org/llama.cpp/blob/master/docs/models.md), master branch inspected October 12, 2026. GGUF requirement and conversion tools.
[^qnn]: ONNX Runtime, [Qualcomm QNN Execution Provider](https://onnxruntime.ai/docs/execution-providers/QNN-ExecutionProvider.html), inspected October 12, 2026. Provider options and Supported ONNX operators, including per-operator data-type and attribute restrictions.
[^executorch-diagram]: PyTorch contributors, [How ExecuTorch Works](https://docs.pytorch.org/executorch/stable/intro-how-it-works.html), inspected 1.5 documentation on October 12, 2026. The high-level diagram is byte-identical to [`how-executorch-works-high-level.png` at its original asset revision](https://github.com/pytorch/executorch/blob/48e27b4ea0ba3443831eb4f9d78a4553ce36ae51/docs/source/_static/img/how-executorch-works-high-level.png), September 25, 2023; copyright Meta Platforms and Arm, [BSD license at that revision](https://github.com/pytorch/executorch/blob/48e27b4ea0ba3443831eb4f9d78a4553ce36ae51/LICENSE).
Source: https://latentlit.com/edge-ai/runtimes-compilers/index.mdx