---
title: "DeepInfer"
description: "Inside DeepSeek's inference engine: what is open, how its optimizations work, what the benchmarks show, and practical recipes with deepseek-recipe."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# DeepInfer
import FocusCanvas from '../../../components/FocusCanvas.astro';
import SourceFigure from '../../../components/architectures/SourceFigure.astro';
import ComparisonTable from '../../../components/ComparisonTable.astro';
## TL;DR
- **What it is.** DeepInfer is an open offline inference engine for
DeepSeek-V4.1-Flash. Its companion, **deepseek-recipe**, handles API conversion,
prompt encoding and response parsing.[^release][^recipe]
- **Why it matters.** The model and execution stack work together: reuse global
history, rebuild a short local tail, balance expert work, verify drafts
selectively and overlap CPU bookkeeping with device execution. The advance
is their coordination, not one faster kernel.[^deployment][^mtp][^worker]
- **What the evidence says.** The authors publish throughput/interactivity
curves and estimate dynamic-verification changes from **−1.5% to +11.0%**
versus fixed-five verification at different loads. Conditions matter:
this is not a claim that DeepInfer beats every other engine.
[Read the benchmark analysis](#how-impressive-are-the-results).[^deployment]
- **What you still need.** A complete serving platform. Production routing,
persistent KV storage and service orchestration are not bundled with the
released engine.[^release][^deployment]
## At a glance
[Figure 1](#figure-1) connects the request path, the main efficiency ideas and
the boundary of the public release.
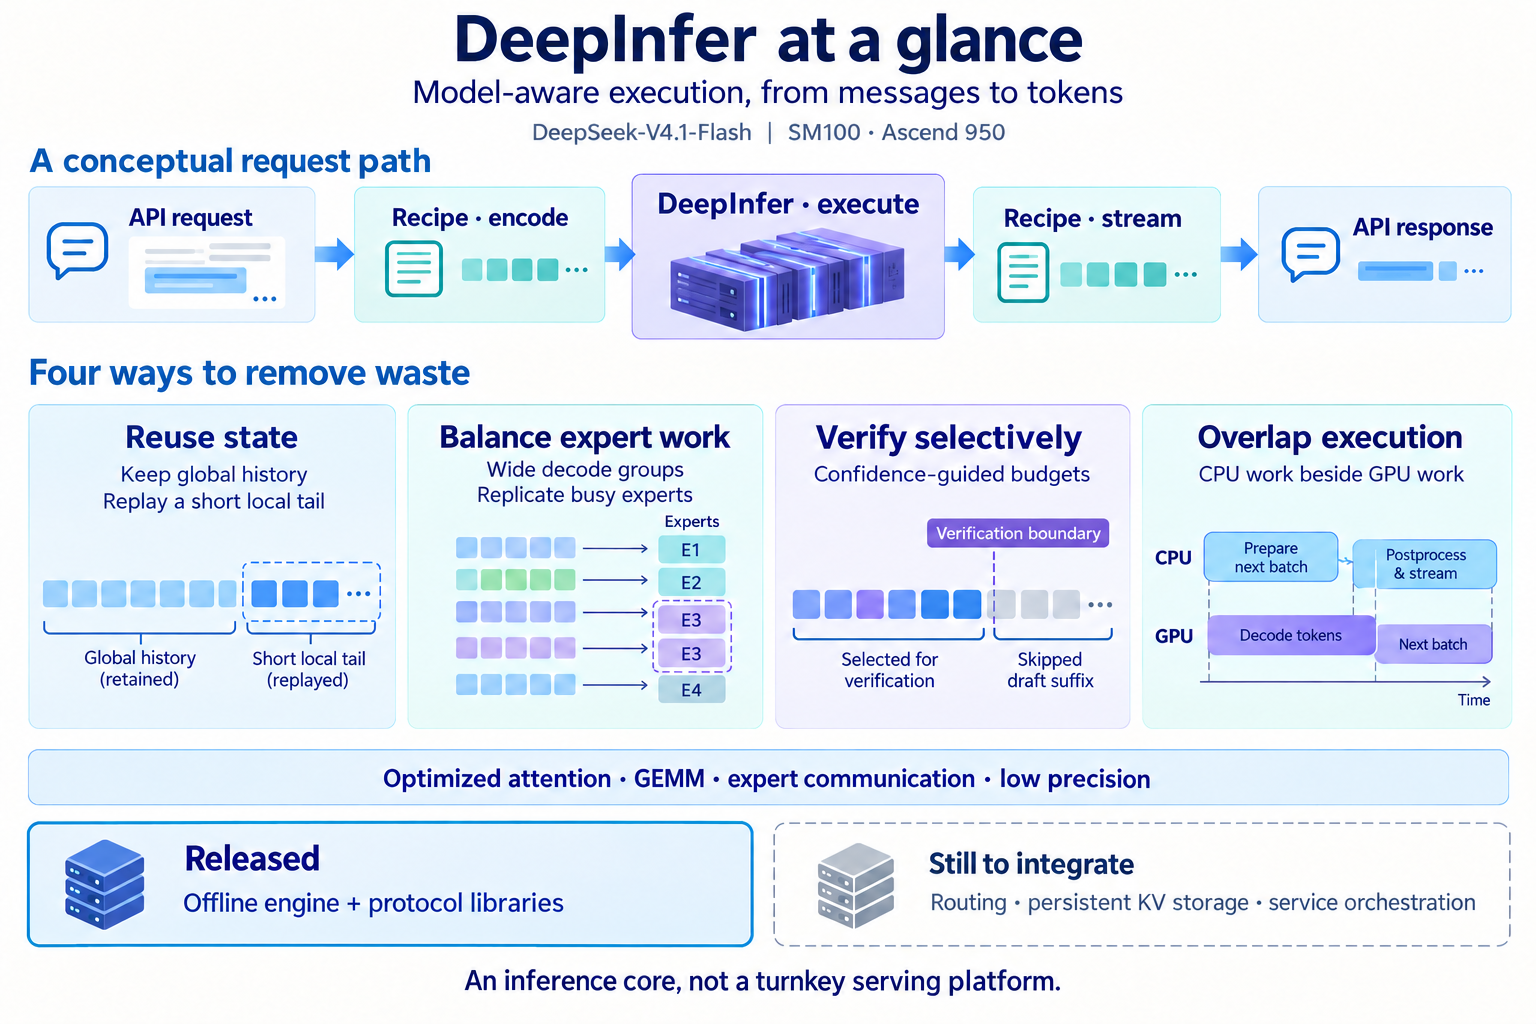
**Figure 1.** DeepInfer at a glance. AI-generated synthesis of the inspected release.[^release][^deployment][^recipe]
**Image description:** Conceptual path: an API request passes through Recipe encoding, DeepInfer execution and Recipe streaming to an API response. The runtime targets DeepSeek-V4.1-Flash on SM100 or Ascend 950. Four efficiency ideas are retained global history with short local replay, wide decode expert groups and busy-expert replicas, confidence-guided selection of a draft prefix for verification while skipping its suffix, and overlapping CPU bookkeeping with GPU work. Optimized attention, GEMM, expert communication and selected low precision support execution. The released offline engine and protocol libraries do not include complete production routing, persistent KV storage or service orchestration. Illustrative shapes and timelines are not measured performance.
Read the overview as text
1. **Request path:** API request → Recipe encoding → DeepInfer execution →
Recipe streaming → API response. This is a conceptual integration, not a
bundled API server.
2. **State reuse:** retain global history and replay a bounded local tail.
The local reconstruction is approximate; earlier global context remains.
3. **Expert work:** combine wider decode groups with redundant copies of busy
experts to balance physical work.
4. **Verification:** choose a draft prefix to verify using confidence and a
performance model. A skipped suffix is not a verified or accepted answer.
5. **Overlap:** prepare later work and process older outputs alongside device
execution, while preserving sample-dependent corrections.
6. **Foundation and boundary:** specialized kernels and selected low precision
support the engine. Routing, persistent KV storage and service orchestration
still need integration. Declared hardware support is not performance parity.
- **The inference engine** — [DeepInfer on GitHub](https://github.com/deepseek-ai/DeepInfer)
Model execution, scheduling and distributed inference. Apache 2.0.
- **The API and token bridge** — [deepseek-recipe on GitHub](https://github.com/deepseek-ai/deepseek-recipe)
Request conversion, prompt encoding and response parsing. MIT.
**Release snapshot: October 20, 2026.** Documentation, source code and benchmark
methodology inspected. No checkpoint, kernel or performance experiment was run
for this study. The [official deployment Q&A](https://github.com/deepseek-ai/DeepInfer/blob/main/doc/inference_deployment_qa.md)
provides the broader system context and builds on the
[Chinese deployment article](https://zhuanlan.zhihu.com/p/2095560295930508953).
## What the release includes
| Piece | Scope of the inspected release |
| --- | --- |
| **DeepInfer engine** | Offline inference for DeepSeek-V4.1-Flash; default examples target the **1017 checkpoint**. The engine contains local runtime cache machinery.[^release][^examples][^cache-engine] |
| **Hardware** | **NVIDIA SM100** and **Huawei Ascend 950**. This is not a declared compatibility list for Hopper, consumer GPUs or laptop NPUs.[^release] |
| **deepseek-recipe** | Rust libraries and Python bindings for multiple API formats, prompt/token conversion and output parsing. It does not supply model inference, tool execution or HTTP transport.[^recipe] |
| **Surrounding service** | Production KV storage/management, complete vision/prefill/decode disaggregation and replica load balancing are not delivered as a complete service.[^release][^deployment] |
“Not a complete KV cache system” does **not** mean the engine has no KV cache.
Its GPU cache implementation is present. The missing boundary is the broader
production storage and management system.[^cache-engine][^deployment]
DeepInfer also has a lineage: the repository credits vLLM as its original
foundation, with inspiration from SGLang and TensorRT-LLM. The release is
valuable systems engineering, not a claim that every ingredient was invented
here.[^release]
## Follow one request through the system
For a language model, **prefill** processes the prompt and prepares reusable
state; **decode** repeatedly extends the answer. With images, a **vision
encoder** first supplies visual representations. DeepSeek describes separate
services for these stages, allowing resources and latency targets to be
managed independently.[^deployment]
[Figure 2](#figure-2) is the authors' **full inference-system architecture**.
It includes components described in the deployment note that are not all
included in the public engine. Read it as a system map, not an installation
manifest.
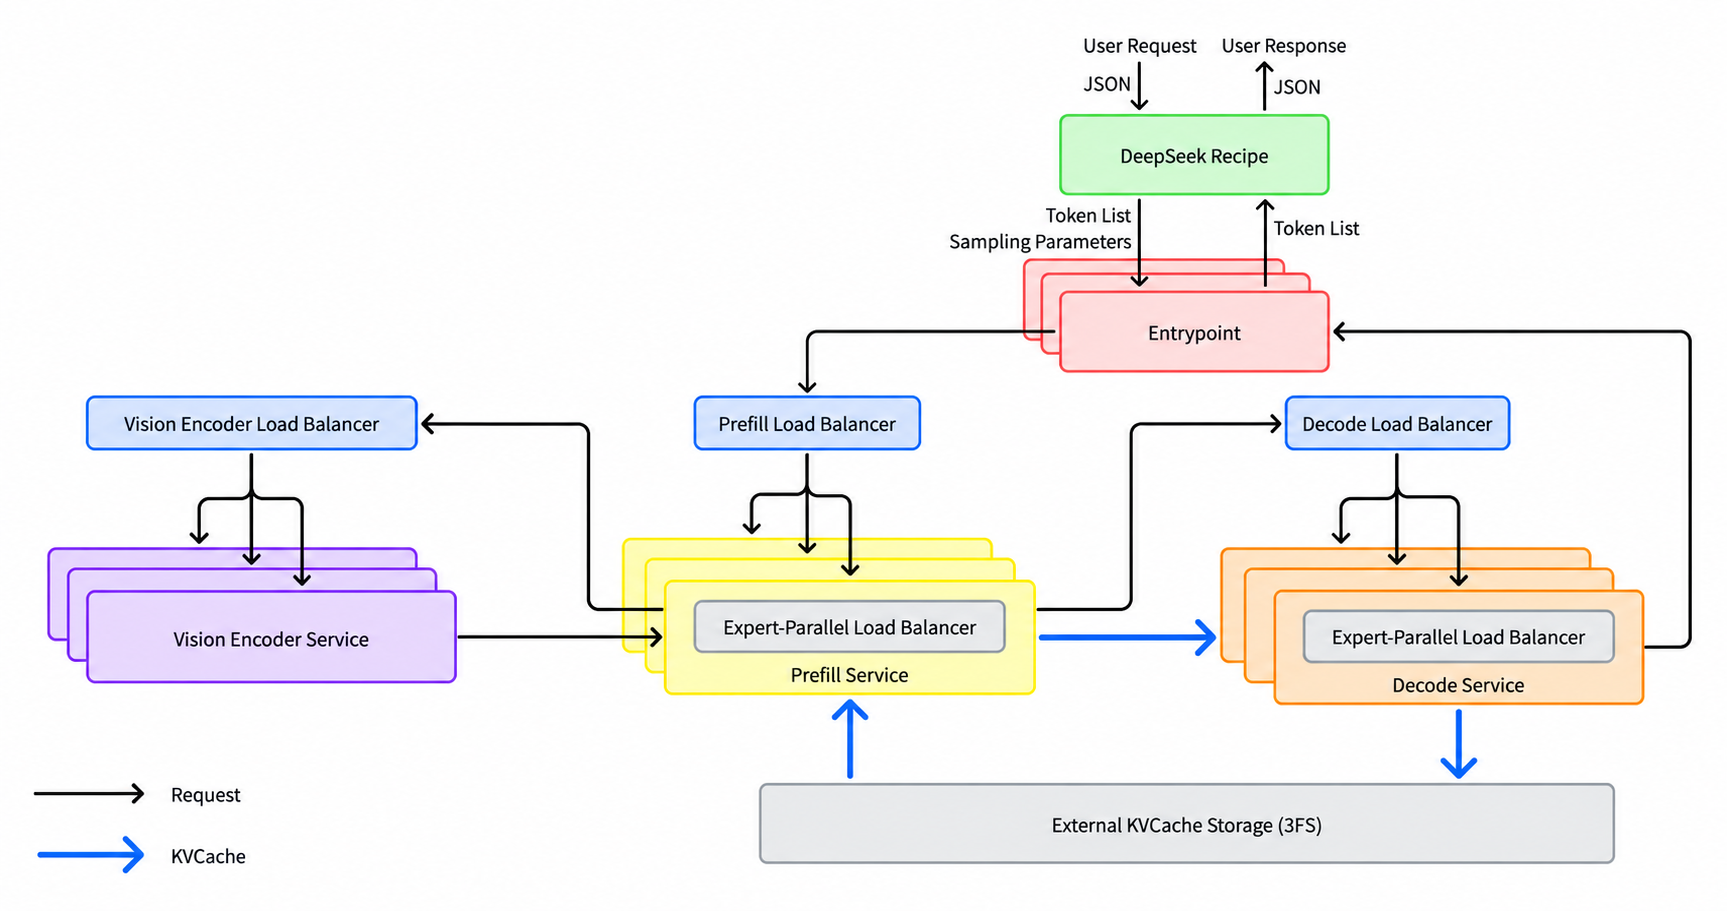
**Figure 2.** The full system, not just the released engine. Reproduced unchanged from DeepSeek's deployment Q&A; Apache 2.0.[^deployment][^artwork]
**Image description:** DeepSeek Recipe converts JSON requests and responses to and from tokens. Entrypoints route to separate vision encoder, prefill and decode services, each with load balancing. Prefill and decode exchange KV state and connect to external KVCache Storage on 3FS. The complete storage and service orchestration are not all included in the release.
The path is:
1. **Convert and encode.** Recipe turns an API request into the appropriate
model conversation, prompt and token sequence.
2. **Reuse and route.** The surrounding service finds reusable prefix state
and assigns remaining work to suitable instances.
3. **Encode images when needed.** Vision work supplies embeddings to prefill.
4. **Process the uncached prompt.** Prefill prepares the state required for
generation.
5. **Generate and stream.** Decode extends the answer; Recipe incrementally
converts output into the chosen response protocol.
The protocol and engine interfaces are released. The complete routing,
persistent storage and service operation shown here remain a separate
integration problem.[^recipe][^deployment]
## Why the execution model matters
### Different stages deserve different hardware groups
**Expert parallelism, or EP,** places different MoE experts across devices.
**Data parallelism, or DP,** distributes attention work across requests/ranks.
DeepSeek describes attention DP paired with expert parallelism: requests
remain distributed for attention, while expert computation exchanges tokens
within a larger group.[^deployment]
Its deployment Q&A recommends small prefill groups when memory permits,
typically **EP2 to EP8**, and much wider decode groups, **EP64 to EP128**.
Wider groups improve the opportunity to combine expert work across many
concurrent requests, but introduce communication, balancing and failure-domain
costs. The production description says it does not currently use TP or CP;
the public examples nevertheless expose CP configurations. **A supported
capability is not the same as a production choice.**[^deployment][^examples]
Expert placement also cannot remain static when some experts receive more
tokens. The released EPLB policy allocates redundant copies of busy logical
experts and distributes physical copies across ranks using recent workload
statistics. This changes placement, not the learned identity of the
experts.[^eplb]
The broader production service balances a different problem: requests with
different context lengths and concurrency. DeepSeek describes distinct
prefill, decode and vision load balancers. Do not confuse these service
components with expert balancing inside an engine.[^deployment]
### Preserve global history, rebuild a short local tail
DeepSeek-V4.1-Flash separates causal encoder and decoder work. Its decoder can
consume shared global history without replaying the entire prompt through all
decoder computation. **Sliding window attention, or SWA,** still needs recent
local state.[^deployment]
SWA bounded replay addresses that remaining work. Rather than reconstruct
every layer's local state from a long history, the deployment description
rebuilds a short tail with a truncated local attention boundary.
This is an **approximation**, not an exact identity to full historical
recomputation.[^deployment]
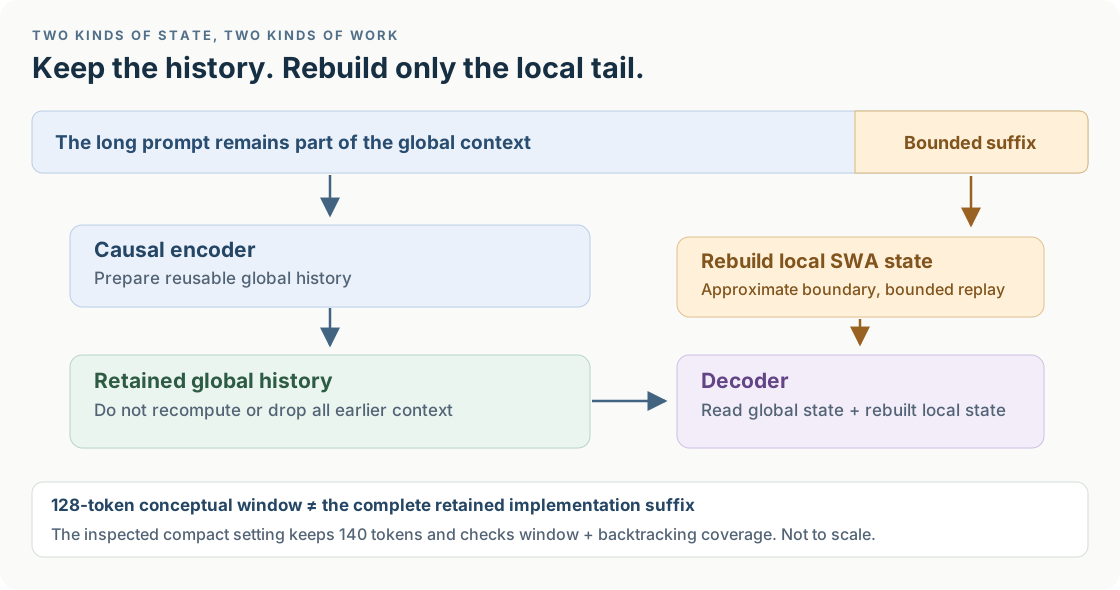
**Figure 3.** Full global evidence, bounded local replay. Independent explanation of the released state boundary.[^deployment][^replay]
**Image description:** The encoder prepares reusable global history over the prompt. The decoder reads that history but rebuilds its local sliding-window state from only a bounded suffix. Earlier prompt information is not discarded globally. The local replay boundary is approximate, and retained implementation tokens also cover speculative backtracking.
The distinction in [Figure 3](#figure-3) is important: **a short local replay
does not mean the model sees only a short prompt**. Global state still carries
longer history; the optimization changes how local decoder state is rebuilt.
There are also two different numbers. The deployment explanation uses a
**128-token SWA window**. The public compact-mode configuration retains
**140 tokens**, including implementation safety margin. The code checks that
the retained suffix covers the window **plus the maximum backtracking
allowance**. Do not replace 140 with 128 simply because the conceptual window
is 128.[^release][^replay]
The repository's mask/compact test compares two implementations of the
truncated policy. Passing it would establish their equivalence under the test,
not equivalence between bounded replay and exact full-history recovery.
We did not run those tests.[^replay-tests]
Where the surrounding service keeps state
The deployment Q&A distinguishes three working sets: live state in GPU memory,
SWA state retained in host memory, and paged global block KV on a dedicated 3FS
storage cluster. It describes different retention policies for agent and
chatbot traffic. These are production design disclosures, not a distributed
cache service supplied by this repository.[^deployment]
The transferable idea is to choose storage by reuse value and recovery cost.
It does not follow that copying the same retention duration or storage
capacity is appropriate for another workload.
### DSpark: spend verification where it pays
Speculative decoding proposes draft tokens and lets the target model verify
a prefix. Verifying every request at the same draft length can waste work
when later proposals are unlikely to survive.
DeepInfer's **DSpark confidence scheduling** estimates how likely draft
prefixes are to be accepted, combines that with a device performance curve,
and chooses a verification budget. The implementation turns per-token
confidence estimates into cumulative prefix estimates before allocating
verification work.[^mtp]
For request $i$, let
$c_{i,t}$ be the head's per-position acceptance estimate
of draft position $t$. The prefix estimate is:
$$
\widehat{p}_{i,j}=\prod_{t=1}^{j}c_{i,t}
\tag{1}
$$
This explains why a later token cannot be selected independently of the
prefix it depends on. These are predictions used by a scheduler, not
guarantees of acceptance or calibrated correctness.[^mtp]
The scheduler seeks useful accepted tokens per predicted execution time,
rather than the largest number of verified tokens. Under asynchronous
execution, the CPU first fixes a budget using lagged information; GPU work
then corrects per-request lengths using the available confidence data.
The dependency management is part of the optimization.[^mtp][^worker]
### Overlap bookkeeping with device execution
CPU scheduling, GPU forward computation, sampling and output processing all
belong to the token loop. If the CPU waits for each device result before
preparing the next batch, the device can sit idle.
The released worker defers a decode step's output processing so it can overlap
with a later forward pass. It tracks previous step state and corrects sequence
metadata instead of pretending future samples are already known.[^worker]
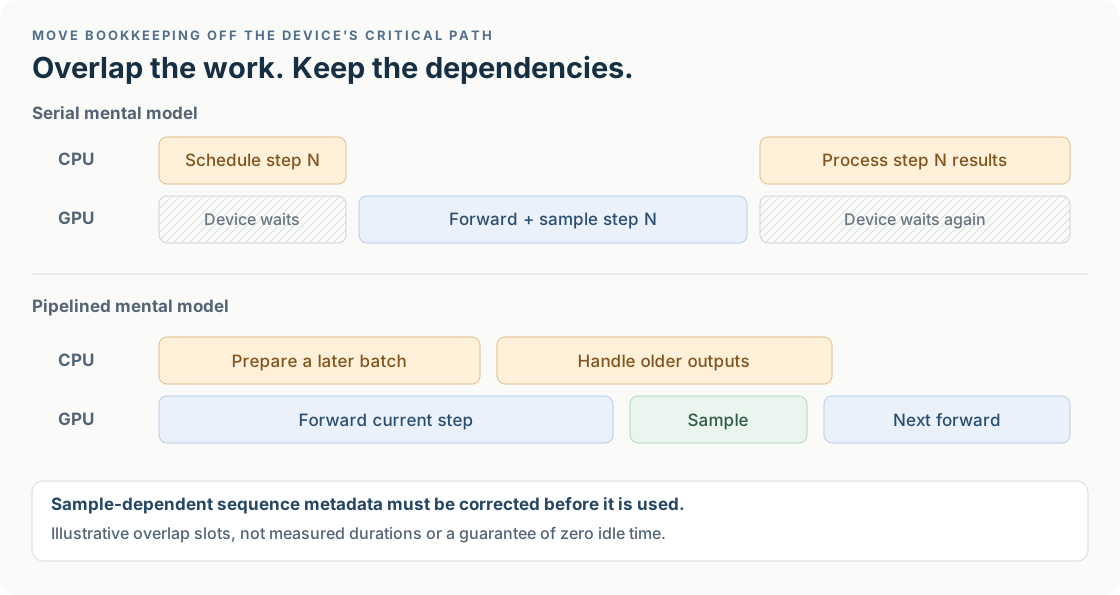
**Figure 4.** Hide avoidable gaps, not necessary dependencies. Schematic of the worker pipeline, not measured timings.[^worker]
**Image description:** A schematic compares serial scheduling, device execution and output processing with pipelined CPU and GPU work. In the overlap view, the CPU prepares another batch and handles older outputs while the device executes. Sample-dependent metadata is corrected before use. Bar lengths are not measurements.
As [Figure 4](#figure-4) illustrates, “zero-overhead scheduling” names the goal
of hiding scheduling on the critical path. It does not mean the CPU does no
work, every synchronization disappears, or every workload benefits equally.
### Kernels and low precision complete the stack
The runtime connects specialized components rather than relying on a single
universal kernel.
| Component | Role in the stack |
| --- | --- |
| FlashMLA | Optimized attention kernels used by the attention backend.[^attention] |
| DeepGEMM | Low precision matrix multiplication and grouped expert computation.[^deepgemm] |
| DeepEP | Expert token dispatch/combine communication.[^deepep] |
| DeepSelect | Top-k kernels for sparse attention and sampling.[^deepselect] |
| TileLang and custom kernels | Express specialized operations, including scheduling metadata and masks.[^worker][^release] |
DeepSeek describes FP4 use for routed expert weights and parts of the KV state,
with different scaling formats. “FP4” is not a statement that every operation,
activation or cache entry uses four bits.[^deployment]
This is why a model's small active-parameter count is not a complete deployment
budget. Retained weights, attention state, expert replicas, communication and
temporary buffers still have to fit and move.
## How impressive are the results?
The strongest evidence is **specific**: published operating curves, one
variable-verification comparison and a documented deployment strategy.
It is not a controlled leaderboard against every serving framework.
### Prefill: throughput has a latency price
The original prefill curve uses **four SM100 devices**, a **131,072-token
context**, EP4/DP4 and **140-token decoder replay**. Point labels are the
prefill token budget per rank. Larger chunks increase throughput, but
also increase time per prefill step.[^release][^benchmark]
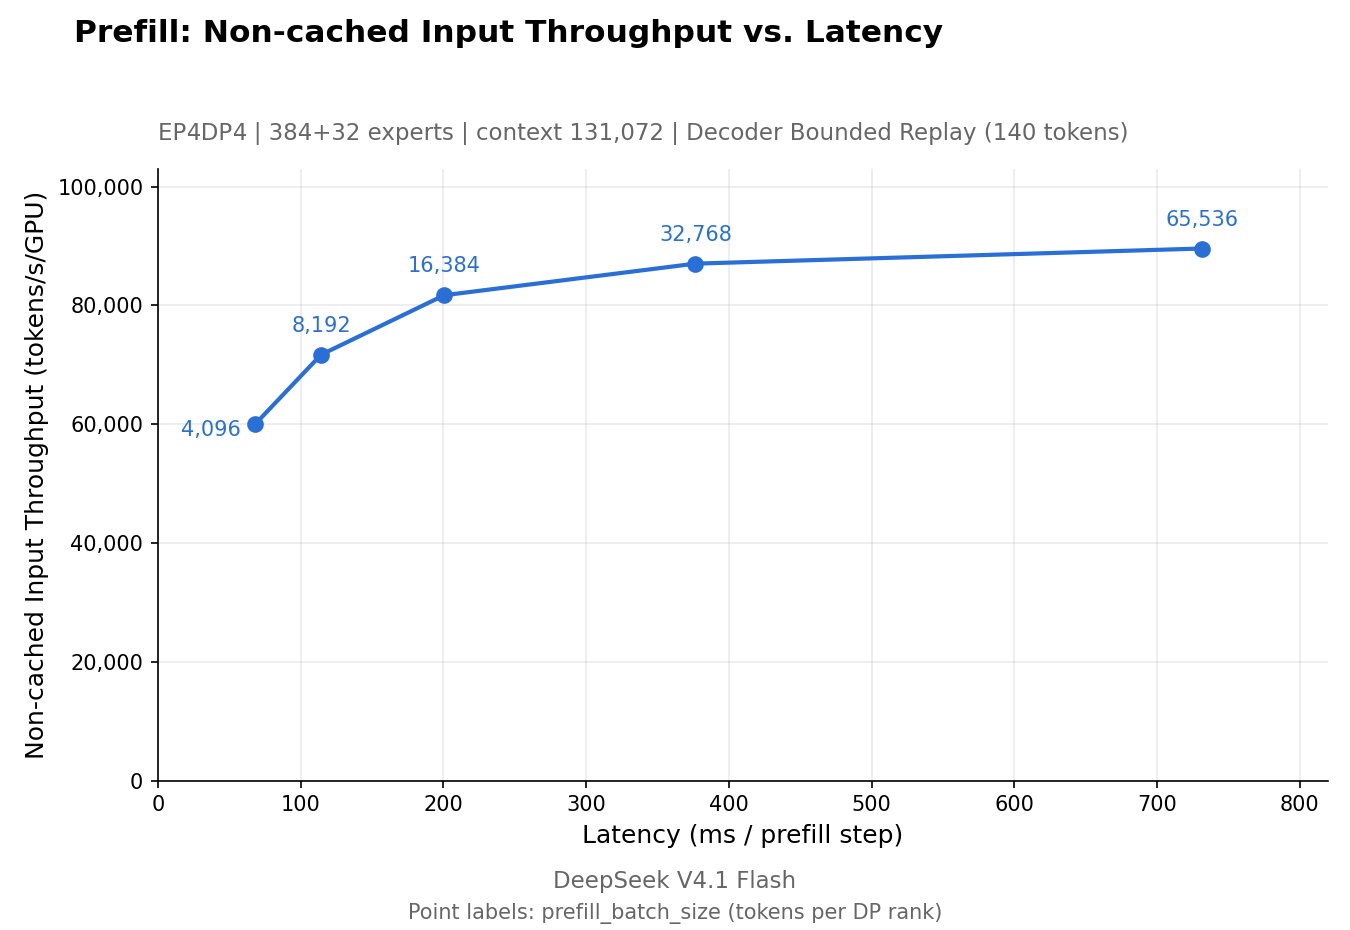
**Figure 5.** More prefill work per step, more throughput and delay. Original DeepSeek release figure; Apache 2.0.[^benchmark][^artwork]
**Image description:** DeepSeek's prefill curve plots non-cached input tokens per second per GPU against milliseconds per prefill step. Context is 131072, EP4DP4 with 384 plus 32 experts and 140-token decoder replay. Larger per-rank token budgets raise throughput while increasing step time.
The horizontal axis in [Figure 5](#figure-5) is **not full request TTFT**.
The curve approaches **90,000 non-cached input tokens/s/GPU** at its larger
chunk settings, an approximate reading of the original plot rather than a
new measurement.
Time to first token also includes queueing, preparation, all required chunks,
transfers and response delivery. The plotted input throughput is for
**non-cached tokens**, not all prompt tokens including cache hits.
### Decode: throughput and interactivity are different axes
The authors also compare EP8/DP8 with EP64/DP64. At the stated operating
points, the wider group offers a better combination of output throughput and
per-user speed. This is an expert-parallel scaling comparison, not a
DeepInfer versus vLLM benchmark.[^deployment]
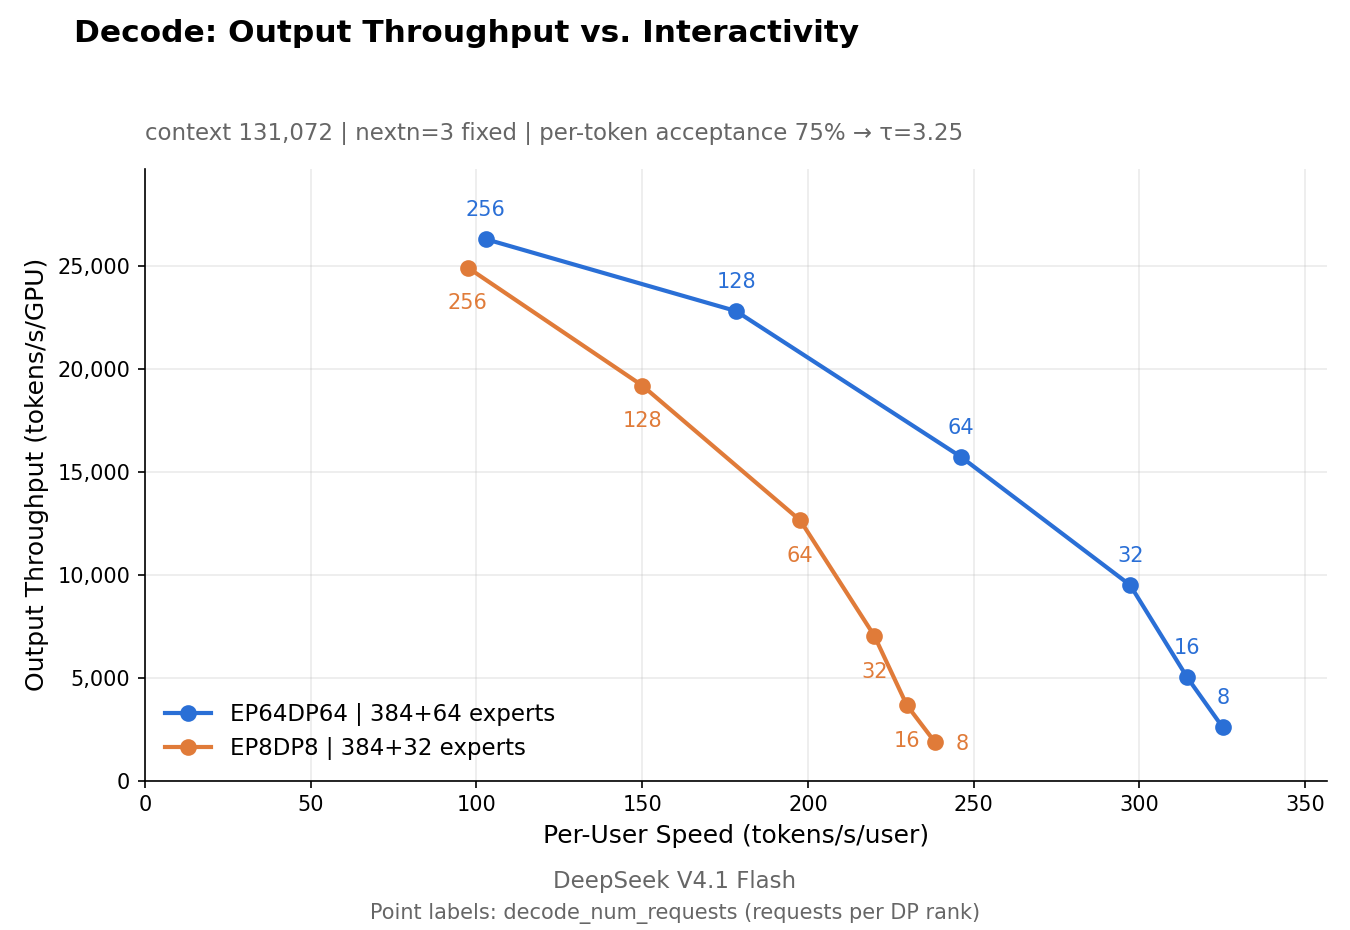
**Figure 6.** Wider expert parallelism under one stated workload. Original DeepSeek comparison; both axes use the declared acceptance accounting.[^deployment][^plotting][^artwork]
**Image description:** Original decode comparison of EP64DP64 and EP8DP8 at context 131072, fixed nextn 3 and assumed per-token acceptance 75 percent. The horizontal axis is per-user token speed and the vertical axis is token throughput per GPU. Labels are requests per DP rank, not total cluster concurrency.
Read three details before quoting [Figure 6](#figure-6):
- The context is **131,072 tokens**. Draft length is **fixed at three**.
- The plot assumes **75% per-token acceptance**, giving the plotting factor
**3.25 tokens per step**. This is the plotter's accounting assumption, not
a measured universal acceptance rate.
- Labels are concurrent requests **per DP rank**. At DP64, a label of 64
corresponds to 4,096 requests across ranks, not 64 requests in total.
For orientation, the EP64 point labelled 64 is around **250 tokens/s/user**
and **16,000 output tokens/s/GPU** under this accounting. These rounded values
are read from the source plot, not raw measurements or a promised API speed.
Let $s$ be measured steps/s,
$n$ draft length,
$a$ the supplied average acceptance factor,
$r$ requests per rank and
$C$ context-parallel size. The plotter uses:
$$
\begin{aligned}\tau&=1+na\\ v_{\mathrm{user}}&=s\tau\\ T_{\mathrm{GPU}}&=\frac{sr\tau}{C}\end{aligned}
\tag{2}
$$
This reproduces the script's convention, not a general theorem about
speculative decoding. The raw benchmark's fixed-length throughput initially
uses **full acceptance**. Do not mix that number with the adjusted curve or
apply the same multiplier again to a different variable-length measurement.
The plotter explicitly rejects that incompatible case.[^benchmark][^plotting]
### Variable verification helps at some loads, not all
The deployment Q&A reports the following **estimated throughput changes**
from benchmark data for dynamic verification versus fixed-five verification
with EP64/DP64. This is a separate experiment from the fixed-three curve above.
**Dynamic verification versus fixed five**
| Concurrent sequences per rank | Reported estimated throughput change |
| --- | ---: |
| 16 | **−1.5%** |
| 60 | **+5.4%** |
| 96 | **+11.0%** |
The low-concurrency regression is part of the result. Confidence scheduling
has its own overhead and operating point; it is not a blanket speedup.
These are author-reported estimates, not our measurements.[^deployment]
### Production scale and quality need separate interpretation
DeepSeek reports **155 trillion tokens/day for one cluster** and **US\$38 of
revenue per GPU-hour at valley pricing**. The note does not provide the token
mix needed to interpret 155T as generated output throughput. Revenue is not
profit, hardware payback or a transferable business forecast.[^deployment]
The released evaluation harness separately reports reference Pass@1 results
of **99.9% on AIME 2026, 93.4% on GPQA Diamond and 42.6% on HLE-Full** under its
documented protocol. AIME uses 32 samples per task and GPQA uses eight to
estimate single-sample accuracy; these are not best-of-32 or best-of-eight
success rates. Use the documented scorers and require complete task coverage
when comparing runs. Treat these as deployment sanity checks, not proof of
identical outputs under every optimization.[^evaluation]
No benchmark here independently establishes a cross-engine speedup, equal
NVIDIA/Ascend performance or a measured reduction in energy per task.
## Recipe is more than a chat template
A correct model can still behave incorrectly behind a poorly implemented
interface. Recipe converts **Chat Completions, Responses and Messages**
requests into a common conversation representation, then applies the correct
model encoding. Output parsing reconstructs reasoning, visible text and tool
calls for the selected protocol.[^recipe]
### Preserve the difference between content and control
Recipe records the exact ranges of intentionally inserted special tokens.
Ordinary text is encoded without the added special-token vocabulary.
A user who types the spelling of a role token does not thereby create a real
role boundary. Ordinary regions can also be encoded in parallel and joined in
the original order.[^tokenizer]
On output, token-ID-aware parsing can distinguish actual control tokens from
the same spelling expressed as ordinary text. A plain text stream loses that
token-identity information. Use a matching tokenizer when processing token-ID
chunks, and do not assume the text-only example preserves that distinction.[^recipe-tokenizer]
This reduces a specific control-token injection risk. It does **not** solve
semantic prompt injection, authorize tool execution or establish that a
model's answer is true.
### Stream valid pieces without waiting for the whole answer
An emitted chunk can end inside a UTF-8 character, a delimiter or a tool
argument. Recipe's parser retains unfinished state and emits determined
content incrementally. Its implementation uses incremental delimiter matching;
it does not repeatedly parse the entire accumulated response.[^parser][^decoder]
The practical lesson is that fast generation and fast delivery are different
problems. A server that buffers all tool arguments before returning them can
erase some of the responsiveness gained by the inference engine.
### A schema needs an enforcing backend
Recipe can translate a requested format into an output constraint.
The inference backend still has to enforce it. DeepInfer separately compiles
grammars and masks illegal tokens while sampling.[^recipe][^grammar]
For an already initialized DeepInfer runtime, the inspected interface accepts
a constraint such as:
~~~python
from deepinfer.sampling_params import SamplingParams
params = SamplingParams(
max_tokens=128,
so_args={"schema_type": "regex", "schema": r"[A-Z]{2}-[0-9]{3}"},
)
~~~
This is a configuration fragment, not a complete inference program.
The public engine uses the names **regex, json and ebnf** here.
A valid format does not establish factual correctness, and a generation stopped
by a length limit may still be incomplete. Check termination and validate the
result.[^structured]
## Practical recipes
Choose an entry point that matches your hardware and purpose. The examples
below are adapted from the inspected release and have not been executed here.
### 1. Explore the protocol layer without model weights
In a separate Python environment, install the library with
`python3 -m pip install deepseek-recipe`, following the project's package
requirements. Then inspect a rendered prompt:
~~~python
from deepseek_recipe import (
ChatCompletionRequest,
ConversionOptions,
DeepseekV41Encoding,
)
request = ChatCompletionRequest({
"model": "DeepSeek-V4.1-Flash",
"messages": [{"role": "user", "content": "Explain prefix caching."}],
})
converted = request.convert(ConversionOptions())
rendered = DeepseekV41Encoding().render_conversation(converted.conversation)
print(rendered.prompt)
~~~
**What this does:** converts and renders a conversation. It does not run a
model or produce an answer. For actual token IDs, attach the matching tokenizer;
do not feed the rendered string through an arbitrary tokenizer and discard its
special-token ranges.[^recipe][^recipe-tokenizer]
The repository also provides a visual encoding/decoding demo and mock API
servers. Their sample responses are **mock inference**, not evidence that an
LLM is running.[^mock-server]
### 2. Run the official offline path on compatible hardware
The engine requires Linux, GCC 13 or newer, Python 3.12, and CUDA 13 for the
declared NVIDIA platform or CANN 9.2 for Ascend. Confirm device memory,
interconnect and model compatibility before building. This is a large-model
systems stack, not a laptop quick start.[^release]
The following illustrates the NVIDIA path from a reviewed checkout. Replace
the model path with an **existing compatible local checkpoint directory**.
~~~bash
python3.12 -m venv .venv
. .venv/bin/activate
export DEEPINFER_ACCELERATOR=nvidia
./build.sh
python examples/offline_inference.py \
--model_name /models/DeepSeek-V4.1-Flash-1017 \
--ep 8 \
--check_structured_output
~~~
The build script installs dependencies and builds the vendored operators.
The examples can otherwise download their default checkpoint automatically.
Using a real local directory makes the weight source explicit. Review the
checkpoint's code and terms before executing it; the example loader enables
`trust_remote_code`.[^build][^example-config]
Eight-device offline examples are not the same as the efficient production
unit recommended in the Q&A. The latter recommends wide decode groups and
roughly balanced prefill/decode capacity. Do not present that recommendation
as the engine's absolute minimum supported device count.[^examples][^deployment]
### 3. Measure a controlled operating curve
Start from the official sweep script rather than a screenshot of one peak.
For an already configured compatible allocation:
~~~bash
# Fixed-length accounting, matching the plotter's supported convention.
export DEEPINFER_ENABLE_MTP_VARLEN=0
bash examples/sweep/run_sweep.sh decode my-decode-128k 131072 3 0.75
~~~
The parallel scale comes from the job environment and visible devices, not
from this command's tag. Record those settings, checkpoint, CP size, expert
replicas, context, uncached suffix, precision and draft policy. The script
writes raw JSONL points; retain them with the plot.[^sweep][^benchmark]
Measure without the profiler, then collect traces separately to inspect
kernels. The benchmark documentation warns that profiling perturbs timings
and that its throughput deliberately excludes certain logging/flush intervals.
These are steady-state engine measurements, not an online SLA.[^benchmark]
Useful configurations to compare, not blindly combine
| Goal | Inspected setting or check |
| --- | --- |
| Confidence scheduling | `DEEPINFER_ENABLE_MTP_VARLEN=1`; the draft maximum is controlled by `DEEPINFER_USE_NEXTN_DECODE`, default five.[^release] |
| Compact decoder replay | `DEEPINFER_YOCO_PREFILL_TRUNCATION_MODE=compact` and `DEEPINFER_YOCO_PREFILL_KEEP_TOKENS=140`; respect window plus backtracking requirements.[^replay] |
| A conservative reproducibility profile | On NVIDIA, enable `DEEPINFER_BATCH_INVARIANT=1`, disable variable verification, disable speculative drafts and pass a fixed `seq_seed` to `SamplingParams`. This is a debugging profile, not the throughput profile.[^release][^structured] |
| Replay implementation regression | Compare mask and compact modes with the supplied YoCo test. Do not call it a test of exact recovery.[^replay-tests] |
| Output correctness | Run structured-output checks and inspect normal termination, schema validity and task semantics separately.[^structured] |
### 4. Build the missing service boundary deliberately
Connecting Recipe to an engine is an integration project. In addition to
inference and tokenization, decide how to handle authentication, admission,
cancellation, queues, timeouts, storage, routing, observability and failures.
The sample FastAPI server has **no authentication**, uses mock inference by
default, and does not filter private image-fetch destinations by default.
Keep it on loopback for exploration. Before exposure, supply a real backend
and enforce network destination checks, including redirects, along with
request and resource limits.[^mock-server][^recipe-development]
The engine's grammar compiler also warns against an unlimited distinct-schema
cache. Format constraints are another resource budget, not free input.[^grammar]
## What to take away
DeepInfer is significant because **it exposes how a particular model and
inference system are made efficient together**. Reusable global state, short
local replay, wider expert batches, selective verification, overlapped
scheduling and protocol correctness each address a different source of waste.
For engineers operating compatible clusters, it is code and a design reference
to evaluate. For readers without that hardware, Recipe and the source traces
still offer useful lessons. For a general production deployment, compare
capabilities and complete service needs before replacing an established stack;
the release alone does not establish a universal winner.
Continue with the [DeepSeek-V4.1-Flash model study](/architectures/models/deepseek-v4-1-flash/)
for the backbone, [Efficient Inference](/edge-ai/efficient-inference/) for shared
mechanisms, and [Local & Cloud AI](/edge-ai/local-cloud-collaboration/) for
cooperation across deployment boundaries.
[^release]: DeepSeek-AI. [DeepInfer release README](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/README.md), release snapshot inspected October 20, 2026. Features, hardware, prerequisites, missing service components and Apache 2.0 license.
[^recipe]: DeepSeek-AI. [deepseek-recipe README](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/README.md), release snapshot inspected October 20, 2026. Supported scope, API interfaces and MIT terms.
[^deployment]: DeepSeek-AI. [DeepSeek V4.1 Flash Inference Deployment Q&A](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/doc/inference_deployment_qa.md), release snapshot inspected October 20, 2026. System architecture, storage, balancing, speculation and author-reported deployment results.
[^examples]: DeepSeek-AI. [DeepInfer examples and benchmark methodology](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/README.md), release snapshot inspected October 20, 2026. Offline arguments, workloads, full-acceptance counters and profiler boundaries.
[^cache-engine]: DeepSeek-AI. [Runtime cache implementation](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/deepinfer/worker/cache_engine.py), release snapshot inspected October 20, 2026. CacheEngine and state/cache layout helpers.
[^artwork]: DeepSeek-AI. [Original documentation figures](https://github.com/deepseek-ai/DeepInfer/tree/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/doc/images), release snapshot inspected October 20, 2026. Reproduced unchanged under [Apache 2.0](/licenses/deepinfer-Apache-2.0.txt), not this site's MIT grant. The two SVG explanations are original work.
[^eplb]: DeepSeek-AI. [Expert placement policy](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/deepinfer/model_executor/eplb/policy.py), release snapshot inspected October 20, 2026. Redundant expert allocation and physical placement.
[^replay]: DeepSeek-AI. [YoCo prompt metadata and replay bounds](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/csrc/engine/input_metadata/prepare_tensor_input_v4.cpp), release snapshot inspected October 20, 2026. yoco_swa_visibility and update_yoco_prompt_v4.
[^replay-tests]: DeepSeek-AI. [YoCo mask/compact equivalence verification](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/yoco/README.md), release snapshot inspected October 20, 2026. Test scope, configuration and limitations.
[^mtp]: DeepSeek-AI. [Variable verification scheduler](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/csrc/engine/mtp_varlen.hpp), release snapshot inspected October 20, 2026. MTPVarlen::schedule; cumulative confidence update in the adjacent scheduler.hpp process_MTPInfo.
[^worker]: DeepSeek-AI. [Per-step worker pipeline](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/deepinfer/worker/worker.py), release snapshot inspected October 20, 2026. execute_model_step and sequence-length correction.
[^attention]: DeepSeek-AI. [Attention backend](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/deepinfer/model_executor/layers/attention_backend.py), release snapshot inspected October 20, 2026. Sparse prefill and decode kernel calls.
[^deepgemm]: DeepSeek-AI. [DeepGEMM](https://github.com/deepseek-ai/DeepGEMM), release snapshot inspected October 20, 2026. Low precision and grouped matrix multiplication.
[^deepep]: DeepSeek-AI. [DeepEP](https://github.com/deepseek-ai/DeepEP), release snapshot inspected October 20, 2026. Expert-parallel dispatch/combine communication.
[^deepselect]: DeepSeek-AI. [DeepSelect](https://github.com/deepseek-ai/DeepSelect), release snapshot inspected October 20, 2026. Top-k kernels for sparse attention and sampling.
[^benchmark]: DeepSeek-AI. [Benchmark implementation](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/benchmark.py), release snapshot inspected October 20, 2026. measure_prefill, measure_decode and result records.
[^plotting]: DeepSeek-AI. [Pareto plotting implementation](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/sweep/plot_pareto.py), release snapshot inspected October 20, 2026. decode_tau, decode_axes, prefill_axes and configuration checks.
[^evaluation]: DeepSeek-AI. [Evaluation protocol and reference results](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/eval/README.md), release snapshot inspected October 20, 2026. Sample counts, Pass@1, scoring and complete-coverage requirement.
[^tokenizer]: DeepSeek-AI. [PromptTokenizer implementation](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/deepseek-recipe-encoding/src/tokenizer.rs), release snapshot inspected October 20, 2026. Explicit control ranges, base-vocabulary text and parallel region encoding.
[^recipe-tokenizer]: DeepSeek-AI. [Recipe tokenizer guide](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/docs/tokenizer.md), release snapshot inspected October 20, 2026. Matching tokenizers, special ranges and text/token chunk distinctions.
[^parser]: DeepSeek-AI. [Streaming output parser](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/deepseek-recipe/src/stream/output_parser.rs), release snapshot inspected October 20, 2026. State and incremental marker matching.
[^decoder]: DeepSeek-AI. [Streaming token decoder](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/deepseek-recipe/src/stream/decoder.rs), release snapshot inspected October 20, 2026. Token identity and incomplete text handling.
[^grammar]: DeepSeek-AI. [Grammar compiler](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/deepinfer/structure_output/compiler.py), release snapshot inspected October 20, 2026. Compilation, grammar cache limits and the adjacent mask.py runtime interface.
[^structured]: DeepSeek-AI. [Structured-output regression example](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/_structured_output.py), release snapshot inspected October 20, 2026. Schema names, normal termination and SamplingParams in deepinfer/sampling_params.py; adapted code, Apache 2.0.
[^mock-server]: DeepSeek-AI. [Recipe FastAPI example](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/server-py/README.md), release snapshot inspected October 20, 2026. Mock inference, custom backend and deployment scope.
[^build]: DeepSeek-AI. [DeepInfer build script](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/build.sh), release snapshot inspected October 20, 2026. Dependency installation and vendor/engine builds.
[^example-config]: DeepSeek-AI. [Offline example configuration](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/_config.py), release snapshot inspected October 20, 2026. resolve_model_path and create_llm, including trust_remote_code.
[^sweep]: DeepSeek-AI. [Sweep runner](https://github.com/deepseek-ai/DeepInfer/blob/774ce244b87cc0eb8d4b94ab9f5de2ab22049f01/examples/sweep/run_sweep.sh), release snapshot inspected October 20, 2026. Configuration tags, raw JSONL and plot invocation.
[^recipe-development]: DeepSeek-AI. [Recipe development and deployment guide](https://github.com/deepseek-ai/deepseek-recipe/blob/935817c66f5d6e64838f419692545f06787e485f/docs/development.md), release snapshot inspected October 20, 2026. Native dependencies, example servers and image destination filtering.
Source: https://latentlit.com/inference/deepinfer/index.mdx