---
title: "Distillation in LLMs and VLMs"
description: "What Gemma, DeepSeek and Qwen disclose about distillation, and what changes when visual evidence must transfer."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Distillation in LLMs and VLMs
import FocusCanvas from '../../../components/FocusCanvas.astro';
import SourceFigure from '../../../components/architectures/SourceFigure.astro';
import ComparisonTable from '../../../components/ComparisonTable.astro';
Distillation is not one final compression step shared by every model. It can
supply pretraining targets, teach reasoning through curated responses, or
consolidate several specialist policies. These recipes differ in both the
supervision and the capability they try to transfer.[^gemma2][^r1][^v41]
This page inspects **distillation disclosures**, not every aspect of each
model's full training system. Sources were checked October 14, 2026. Results
are author-reported; no checkpoint was trained or benchmarked here.
## Six recipes, six different contracts
**Read the training contract**
| Model and study | Stage and student | Disclosed signal | Do not infer |
| --- | --- | --- | --- |
| [Gemma 2](/architectures/models/gemma-2/) | Pretraining of 2B and 9B models | Teacher next-token probabilities.[^gemma2] | The 27B model uses the same distilled-pretraining recipe. |
| [Gemma 3](/architectures/models/gemma-3/) | Pretraining across the reported family | 256 probability-weighted sampled logits per position; restricted targets are renormalized.[^gemma3] | These are simply the teacher's top 256 logits. |
| [DeepSeek-R1](/architectures/models/deepseek-r1/) | SFT of six dense Qwen/Llama students, 1.5B to 70B | Approximately 800K curated examples; no student RL in this reported experiment.[^r1] | The students inherit the teacher's MoE architecture. |
| [Qwen3](/architectures/models/qwen3/) | Lightweight-model post-training | Teacher responses first, then teacher logits on student rollouts.[^qwen3] | A named KL direction when Section 4.5 only says KL. |
| [Qwen3-VL](/architectures/models/qwen3-vl/) | Strong-to-weak post-training | Text-only distillation of the language backbone, within a larger multimodal recipe.[^qwen3vl] | This stage directly distills visual perception. |
| [DeepSeek-V4.1-Flash](/architectures/models/deepseek-v4-1-flash/) | Final post-training consolidation | Full-vocabulary on-policy distillation using over 40 teachers and asynchronous generation.[^v41] | Teacher count is the number of MoE experts. |
The comparison is a synthesis of the cited reports, not a quality ranking.
Follow the study links for the wider architecture; use the original reports in
the references for the training disclosures.
## Gemma: distillation can be part of pretraining
Gemma 2 trains the 2B and 9B students against teacher probabilities rather than
only observed next tokens. That changes the supervision during large-scale
pretraining, not just the final instruction stage. Its controlled 7B-to-2B
ablation uses 500B tokens; that experiment is not the complete released-model
recipe or a measurement of the final 9B model's distillation gain.[^gemma2]
Gemma 3 reduces target handling by sampling 256 logits, weighted by teacher
probabilities, then assigning zero target probability outside the samples and
renormalizing. The report also keeps its vision encoder frozen during language
model training and precomputes image embeddings. Distillation here is not
evidence that all visual layers are being updated.[^gemma3]
The engineering question is which information survives this target
approximation. The target mass outside a retained set, how the set was chosen,
and the normalization rule matter. The [practice chapter](/knowledge-distillation/practice-evaluation/#full-vocabulary-targets-have-a-real-cost)
works through the storage implications without presenting its calculation as
Gemma's measured storage cost.
## DeepSeek-R1: a reasoning teacher, dense students
The expanded R1 report documents roughly 800K supervised examples: reasoning
data curated through sampling and checks, plus general tasks. Six students
start from Qwen or Llama checkpoints. Appendix B.4.3 describes 2–3 SFT epochs;
Appendix F explicitly separates these students from the teacher's RL training.
These are response targets, not a disclosed soft-logit objective.[^r1]
The transferable lesson is the stage separation: expensive teacher learning
can produce a reusable training corpus. The student remains its own
architecture and is evaluated as its own model. It does not inherit the
teacher's internal computation merely by learning its responses.
## Qwen: demonstrations, then student experience
Qwen3's lightweight path first learns teacher responses, then matches teacher
logits on student-generated sequences. In the original report, the named
teachers are Qwen3-32B or Qwen3-235B-A22B.[^qwen3]
In [Figure 1](#figure-1), follow the separate lightweight-model branch.
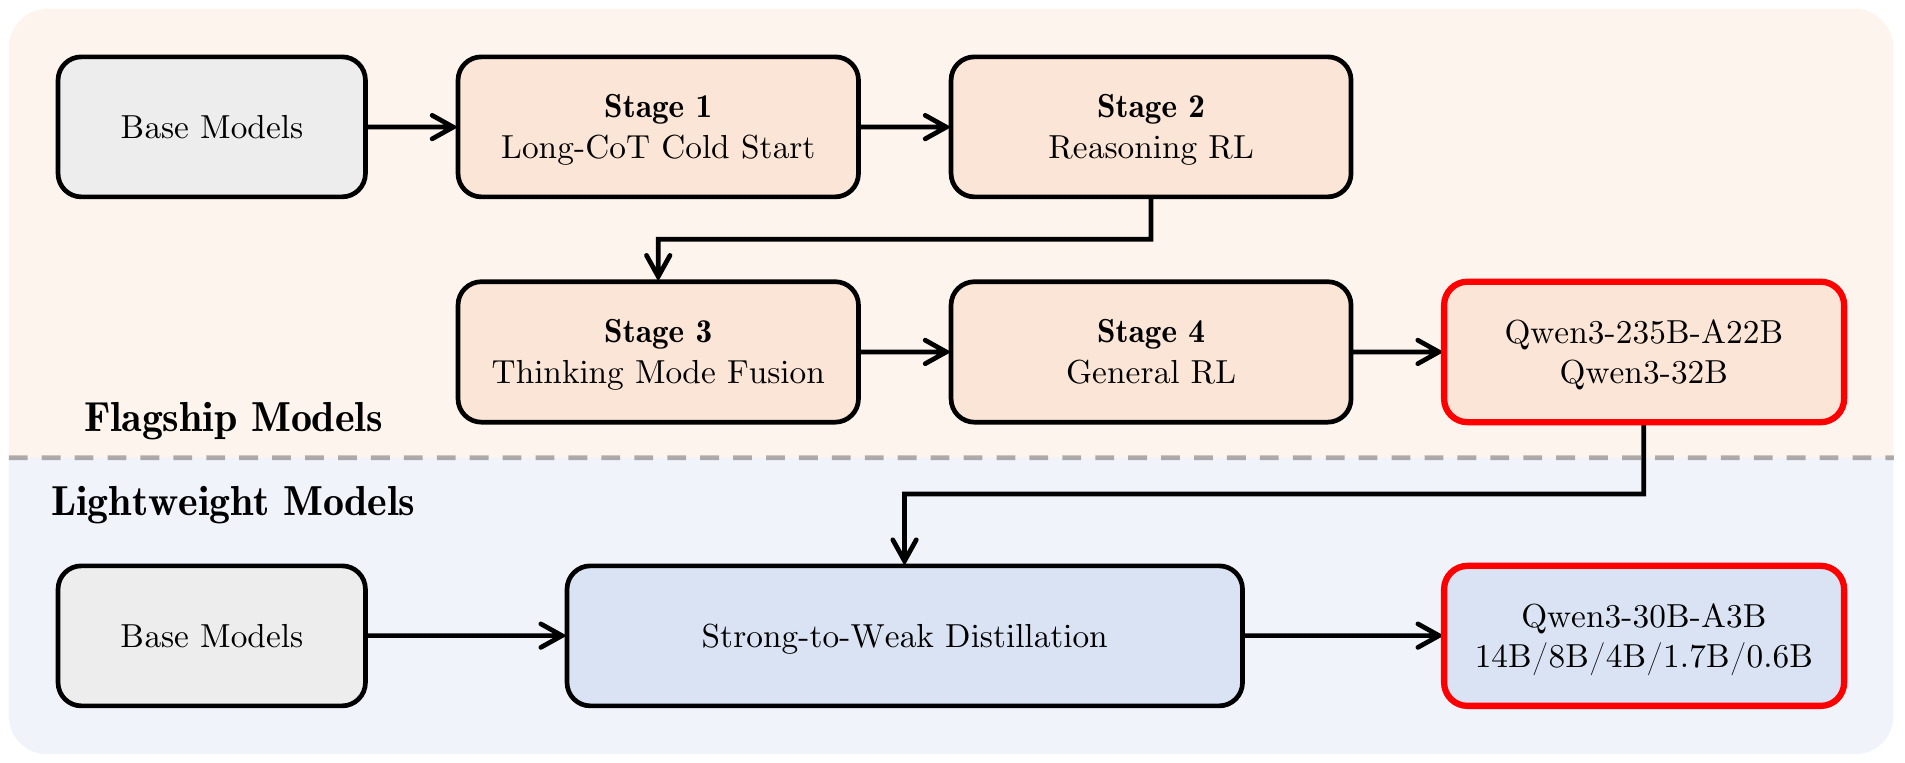
**Figure 1.** Teacher training and student training are distinct paths. Qwen Team, original report Figure 1; attributed figure-region excerpt for analysis.[^qwen3][^qwen-figure]
**Image description:** The Qwen3 report separates a four-stage large-model path, including cold start, reasoning RL, thinking-mode fusion and general RL, from a lightweight-model distillation branch. Teacher capability is transferred through off-policy responses and on-policy feedback rather than requiring every student to repeat the large-model path.
The report's controlled comparison starts from the same off-policy-distilled
8B checkpoint. On-policy distillation uses **1,800 GPU hours**, versus
**17,920** for the compared RL run, with higher reported scores. These are
incremental experiment costs, excluding teacher creation and earlier training.
The finding does not establish a universal tenfold saving.[^qwen3]
## A VLM can improve without direct visual distillation
Qwen3-VL explicitly describes its strong-to-weak stage as **text-only training
of the language backbone**. It reports reasoning benefits on text and
multimodal tasks. That is compatible with an already visually grounded model
using improved reasoning; it is not evidence that text alone teaches a model
to read previously unreadable pixels. The surrounding recipe also contains
multimodal pretraining, SFT and RL.[^qwen3vl]
For a VLM, ask which bottleneck changed: seeing the evidence, connecting it to
language, or reasoning over evidence already represented. A score alone does
not identify that mechanism.
### Visual transfer has several possible targets
| Target | Representative method | What it teaches |
| --- | --- | --- |
| Image–text relationships | TinyCLIP | Mimic cross-modal affinity, with teacher-weight inheritance in the studied compression recipe.[^tinyclip] |
| Visual relations plus outputs | LLaVA-KD | Combine visual–textual distribution matching with relationships between visual features.[^llava-kd] |
| Visual evidence through teacher language computation | Switch-KD | Feed student visual features into the frozen teacher pathway and supervise the resulting probability relationships.[^switch-kd] |
These are related but different settings. CLIP-style embedding alignment is
not the same objective as training a generative visual assistant.
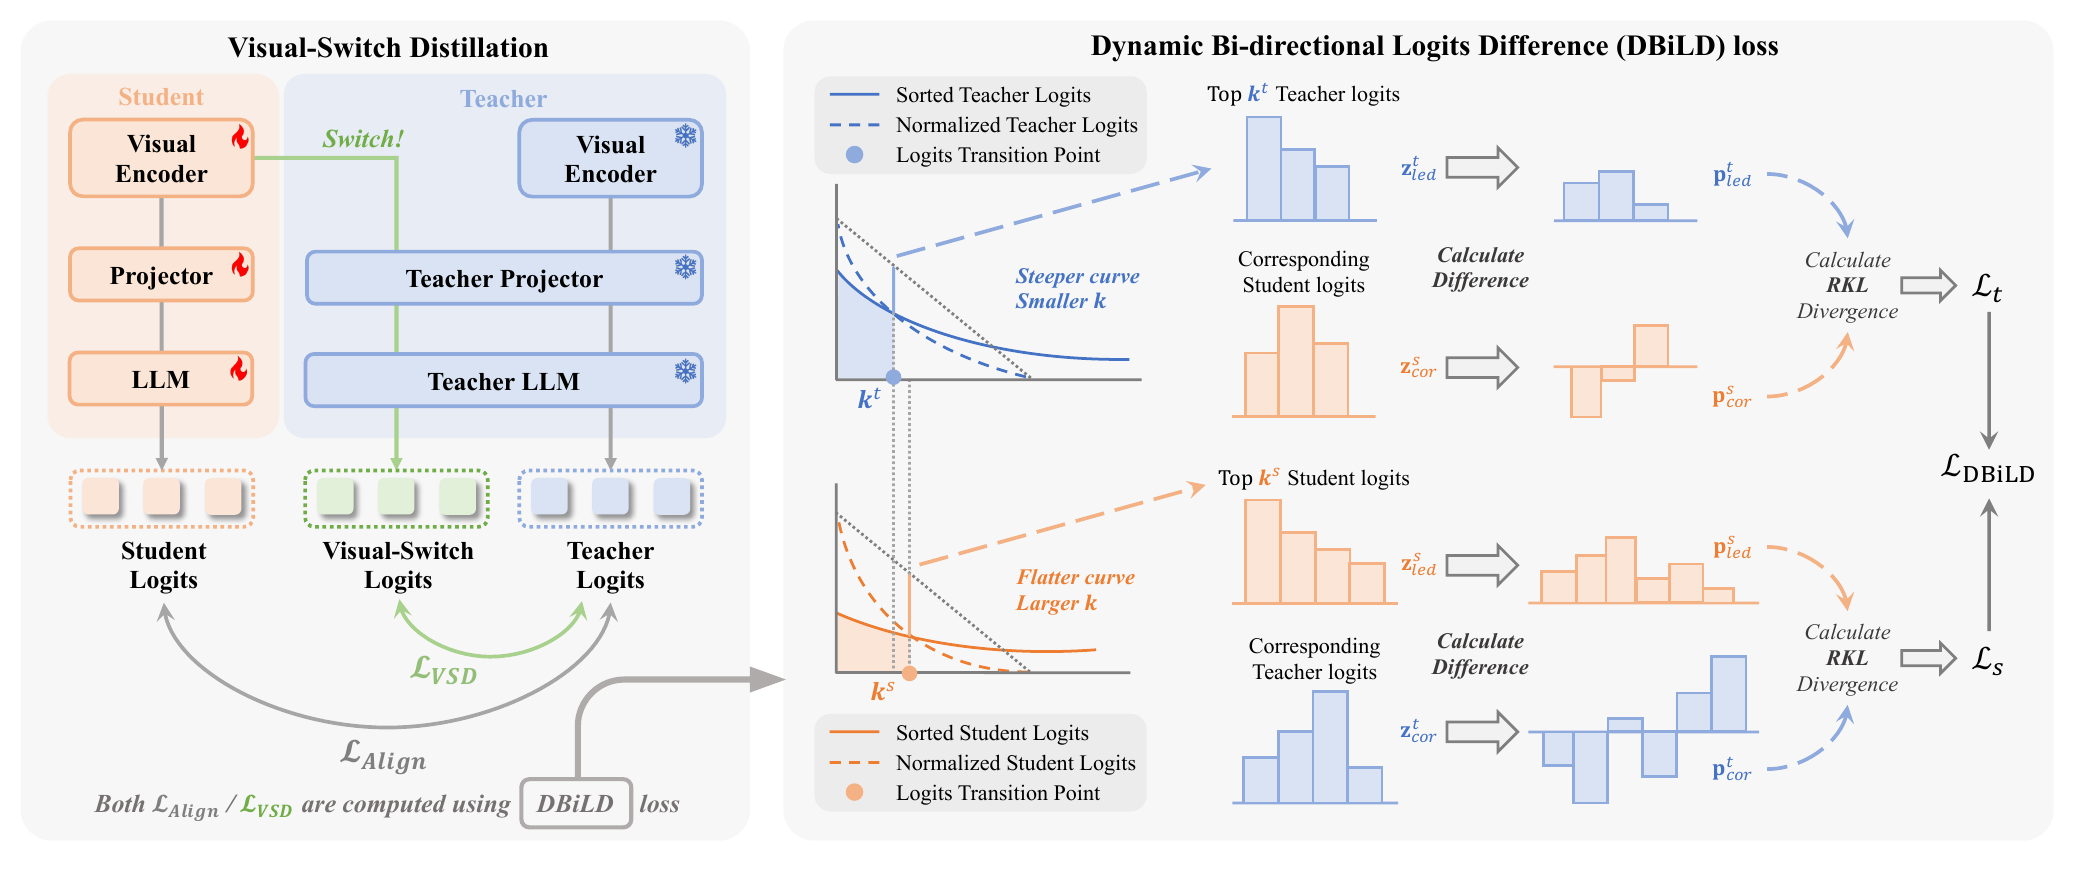
**Figure 2.** Visual features are tested through language predictions. Sun et al., Switch-KD v1, original Figure 2; complete figure-region excerpt for analysis.[^switch-kd][^figures]
**Image description:** Switch-KD has a standard student-versus-teacher output path and a hybrid path from the student visual encoder through the frozen teacher projector and language model. Its DBiLD loss selects informative regions of teacher and student logit curves using adaptive knee points, then compares pairwise logit differences in both directions.
For image $I$ and text $x$,
the hybrid route in [Figure 2](#figure-2) is:
$$
z_{\mathrm{switch}}=L_T\!\left(P_T\!\left(V_S(I)\right),x\right)
\tag{1}
$$
Here, $V_S$ is the student vision encoder;
$P_T$ and $L_T$ are the frozen
teacher projector and language model. The route requires compatible feature
interfaces, not arbitrary model pairs. Switch-KD adds Dynamic Bi-directional
Logits Difference loss, selecting informative regions adaptively.[^switch-kd]
One implementation consequence: frozen teacher weights do not imply detaching
the student features. A gradient used to train those features must still pass
through the frozen teacher computation. The detached teacher-target branch in
the [basic KL example](/knowledge-distillation/practice-evaluation/#check-the-loss-at-a-tiny-scale)
has a different role.
The reported 3B-to-0.5B experiment improves the average over ten
multimodal benchmarks by 3.6 points. That aggregate does not establish gains on
every visual category or on different model pairs.[^switch-kd]
## Recent consolidation: many teachers, one student
DeepSeek-V4.1-Flash describes a final full-vocabulary OPD stage across domains,
using **over 40 teachers**, including architecturally heterogeneous teachers.
Asynchronous generation improves rollout efficiency. The system can change
teachers and mixtures while samples remain in flight.[^v41]
This is policy consolidation, not the MoE router choosing 40 experts at
inference. The report does not disclose a complete reproducible schedule or
isolate the full model's gain to OPD alone. Operational flexibility also makes
version tracking important: a sample needs its generating policy and teacher
configuration, not merely a prompt and response.
## Beyond autoregressive response transfer
DiffusionGemma's August 2026 report uses a joint sampler-distillation and RL
stage after SFT. Its online teacher produces higher-step denoising trajectories
to improve generation quality while teaching useful output in fewer steps.
Here, the compressed resource is the **sampling trajectory**, not necessarily
the parameter count.[^diffusiongemma]
DistillSpec offers another boundary case: the student is a **draft model** that
helps a larger target model decode faster. The target remains in the inference
loop. This differs from replacing the teacher with a standalone student; the
relevant metric includes draft acceptance and verification cost.[^distillspec]
Two other domains broaden the lesson. **Speech:** Distil-Whisper uses selected
teacher pseudo-labels to train a smaller speech recognizer. **Retrieval:**
RocketQAv2 uses dynamic listwise distillation between a retriever and re-ranker.
There, the shared events are candidate passages rather than next vocabulary
tokens. These are brief connections, not complete studies of either
system.[^distil-whisper][^rocketqa]
## Read any future recipe with the same questions
Identify the teacher, its information access, the student initialization,
training stage, target, prefix source and objective. Then ask what was measured
under controlled conditions. Mark absent quantities as undisclosed rather than
filling them in from a neighboring paper or a model's predecessor.
Continue with [Practice and Evaluation](/knowledge-distillation/practice-evaluation/)
to turn those questions into a concrete experiment.
[^gemma2]: Gemma Team. [Gemma 2: Improving Open Language Models at a Practical Size](https://arxiv.org/html/2408.00118v3), 2024, Sections 3.2 and 5; separate distilled 2B/9B pretraining from the 27B recipe.
[^gemma3]: Gemma Team. [Gemma 3 Technical Report](https://arxiv.org/html/2503.19786v1), March 25, 2025, Sections 1.3, 2.1 and 2.4; sampled teacher targets, frozen vision encoder and image embeddings.
[^r1]: DeepSeek-AI. [DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning](https://arxiv.org/pdf/2501.12948v2), expanded January 4, 2026 edition, Appendices B.3.3, B.4.3 and F. The original January 2025 report has different section and table numbers.
[^qwen3]: An Yang et al. [Qwen3 Technical Report](https://arxiv.org/html/2505.09388v1), May 14, 2025, Figure 1, Section 4.5 and Section 4.7, Table 21. GPU hours are the compared additional stages, not total model costs.
[^qwen3vl]: Shuai Bai et al. [Qwen3-VL Technical Report](https://arxiv.org/html/2511.21631v2), November 27, 2025, Sections 4.1 and 4.3; text-only strong-to-weak distillation within multimodal post-training.
[^v41]: DeepSeek-AI. [DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression](https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/2cba9e42aa026125f3ed06c6d98c1db82f7ca027/DeepSeek_V41_Tech_Report.pdf), inspected release report, Section 5.2.4, PDF pages 31–32. Distillation disclosure inspected October 14, 2026.
[^tinyclip]: Kan Wu et al. [TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance](https://arxiv.org/html/2309.12314v1), ICCV 2023, Section 3.
[^llava-kd]: Yuxuan Cai et al. [LLaVA-KD: A Framework of Distilling Multimodal Large Language Models](https://arxiv.org/html/2410.16236v2), ICCV 2025, multimodal/relationship supervision and three-stage recipe.
[^switch-kd]: Haoyi Sun et al. [Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models](https://arxiv.org/html/2604.14629v1), April 16, 2026 edition, Sections 3–4 and original Figure 2. Reported results are not a local reproduction.
[^diffusiongemma]: Gemma Team. [DiffusionGemma Technical Report](https://arxiv.org/html/2608.00146v1), August 2026, Section 5, sampler distillation and reinforcement learning.
[^distillspec]: Yongchao Zhou et al. [DistillSpec: Improving Speculative Decoding via Knowledge Distillation](https://arxiv.org/html/2310.08461v2), ICLR 2024, draft alignment and task/decoding-dependent divergence choices.
[^distil-whisper]: Sanchit Gandhi, Patrick von Platen and Alexander M. Rush. [Distil-Whisper: Robust Knowledge Distillation via Large-Scale Pseudo Labelling](https://arxiv.org/abs/2311.00430), November 2023, abstract's pseudo-label construction and selection. Only this broad connection is covered here.
[^rocketqa]: Ruiyang Ren et al. [RocketQAv2: A Joint Training Method for Dense Passage Retrieval and Passage Re-ranking](https://arxiv.org/abs/2110.07367v2), EMNLP 2021, revised 2023, abstract's dynamic listwise distillation. Only this broad connection is covered here.
[^qwen-figure]: [Qwen3 figure extraction and attribution record](/figures/model-studies/qwen3/SOURCES.md), original Figure 1; bounded critical/research reuse, not an MIT artwork license. Additional use assessed in this collection's [figure record](/figures/knowledge-distillation/SOURCES.md).
[^figures]: [Figure sources and reuse records](/figures/knowledge-distillation/SOURCES.md), Switch-KD extraction, analysis purpose and documented reuse boundary.
Source: https://latentlit.com/knowledge-distillation/llm-vlm-recipes/index.mdx