---
title: "Cloud Agents & Local Specialists"
description: "Keep a powerful cloud agent in charge while local models supply screen understanding, document parsing, video perception and generative tools."
---
> Documentation Index
> Fetch the complete documentation index at: https://latentlit.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Cloud Agents & Local Specialists
import FocusCanvas from '../../../components/FocusCanvas.astro';
import SourceFigure from '../../../components/architectures/SourceFigure.astro';
import ModelFlow from '../../../components/architectures/ModelFlow.astro';
import ComparisonTable from '../../../components/ComparisonTable.astro';
A local model does not need to become a smaller version of the whole agent.
It can give a powerful cloud agent a precise ability: read a screen, extract a
table, identify an event in a video, or generate an asset. The cloud model
continues to reason about the goal and decide what to do next.
**The useful division is general reasoning plus specialized computation.**
OmniTool and Agent S demonstrate this separation for computer use. Whether the
specialist runs on the user's device, a nearby workstation or another server
is a separate deployment decision.[^omni][^agents2][^omnitool]
This page explains that architecture, the research behind it and how to test
its value. For routing, cascades, decoding cooperation and split inference,
start with the [Local & Cloud AI overview](/edge-ai/local-cloud-collaboration/).
For glasses, phones and cameras, continue with
[Smart Devices & Cloud Agents](/local-cloud-ai/smart-devices-cloud-agents/).
It compares concrete research and products, distinguishes actual device inference
from simulated deployment, and examines device, phone or hub, and cloud placement.
## The architecture at a glance
[Figure 1](#figure-1) is a proposed system design, not the internals of one
product. The cloud agent requests bounded work. A local host mediates tool
access, decides what evidence may leave the device and checks actions before
execution. Specialists return observations or artifacts, not permission to act.
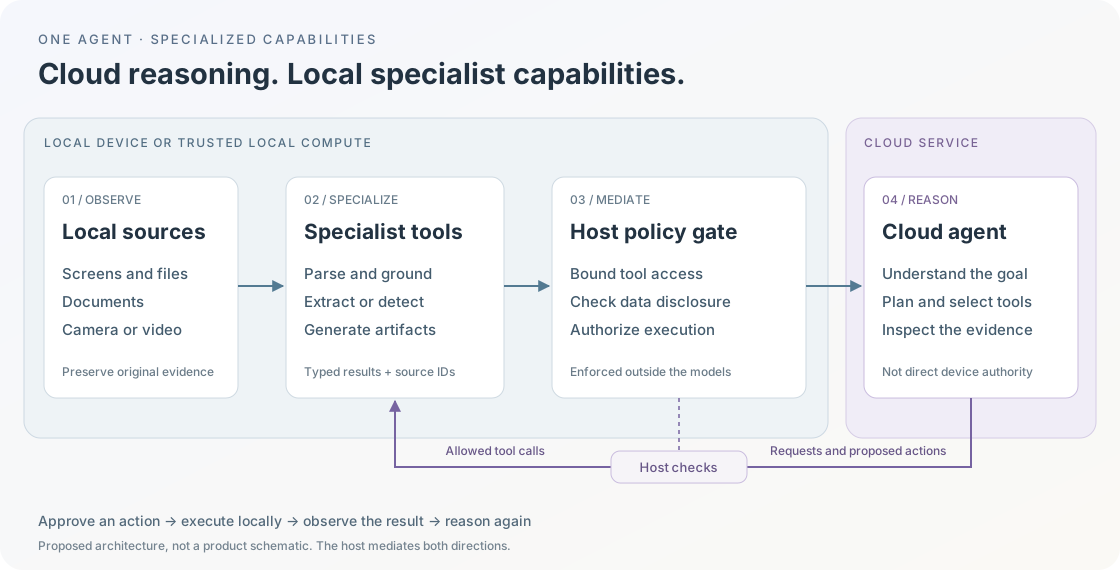
**Figure 1.** A cloud planner with local capabilities and an explicit policy boundary. Independent synthesis informed by modular agents and tool interfaces.[^agents2][^tools]
**Image description:** Observe local screens, documents and video. Specialist models produce structured evidence. A host policy gate mediates disclosure to the cloud agent, which plans and requests further work. Requests return through the same gate; approved actions execute locally and produce a new observation.
Three responsibilities should remain distinct:
- **The agent chooses work:** understand the goal, maintain task state and
request the next useful observation or operation.
- **The specialist supplies a capability:** parse, ground, transcribe,
detect or generate within a defined interface.
- **The host enforces authority:** restrict files, tools, network disclosure
and consequential actions. A model's suggestion is not authorization.
This differs from routing a complete question to either a small or large
model. It also differs from splitting one neural network across devices.
Here, independently deployable models exchange task descriptions and results.
## What the current evidence establishes
**Evidence reviewed October 17, 2026.** The comparison separates demonstrated
agent composition, specialist research and documented local deployment. It is
not a ranking, a complete release list or a claim of handset readiness.
**Systems, specialists and deployment boundaries**
| Work and date | Specialist contribution | What is established | What is not established |
| --- | --- | --- | --- |
| [OmniParser V2 / OmniTool](https://github.com/microsoft/OmniParser), February 2025 | Parse screen elements for a general agent | A working parser, planner and execution stack; CPU support and a separately deployable GPU parser service.[^omni][^omnitool] | Not a latency or energy result for a phone or laptop NPU. |
| [Agent S2 / S3](https://github.com/simular-ai/Agent-S), 2025 research and implementation reviewed in 2026 | Separate planning from visual, textual and structural grounding | S2 studies specialist composition; current S3 exposes separate main and grounding model endpoints.[^agents2][^agents3] | A separate endpoint is not necessarily local; the recommended grounding service can be hosted. |
| [ScreenVLM](https://huggingface.co/docling-project/ScreenVLM), February 2026 | A 316M model returns screen elements, types, boxes and text | Compact dense screen parsing with published evaluations.[^screenvlm] | Its timing study uses an H100, not an edge device; parsing quality is not agent task success. |
| [Phi-Ground](https://www.microsoft.com/en-us/research/articles/phi-ground-improving-how-ai-agents-navigate-screen-interface/), January 2026 disclosure | Locate a requested UI element | Microsoft reports grounding research and integration of its technology into Copilot Vision Highlighting.[^phi] | That disclosure does not establish where inference runs. |
| [Granite Docling](https://huggingface.co/ibm-granite/granite-docling-258M) / [Docling MCP](https://github.com/docling-project/docling-mcp), current implementations | Document conversion as an agent tool | A 258M specialist and an MCP server with explicit local conversion mode.[^granite][^docling] | The model, library and tool server are different components; no universal complete-agent improvement is established. |
| [PaddleOCR-VL-1.6](https://arxiv.org/abs/2606.03264), June 2026 | Layout detection plus a 0.9B document VLM | A specialist parsing system and documented training recipe.[^paddle] | The report does not establish a cloud agent plus mobile deployment. |
| [Cosmos Reason2 / IntBot](https://nvidia-cosmos.github.io/cosmos-cookbook/recipes/inference/reason2/intbot_edge_vlm/inference.html), March 2026 recipe | Camera input to structured perception events | A 2B VLM deployed on Jetson AGX Thor for downstream robot reasoning.[^cosmos] | The demonstrated stack is local, not proof of a cloud controller. |
| [LTX Desktop](https://github.com/Lightricks/LTX-Desktop), current implementation | Local video generation | Supported hardware and separate local and API generation paths.[^ltx] | This is generation, not perception, and not a documented cloud-agent orchestration benchmark. |
The strongest direct agent evidence is computer use. Document and video
systems provide useful capabilities to connect, but connecting them into this
particular architecture is an engineering proposal until the complete system
is evaluated.
## Screens: parsing is not grounding
**Parsing** asks what is visible. **Grounding** asks where a particular
instruction refers. A screen inventory can support planning, while a targeted
grounder resolves the next click. OmniParser supplies structured UI elements;
Agent S2 explicitly delegates action descriptions to grounding experts. Both
can still leave the cloud model inspecting screenshots.[^omni][^agents2]
For example, “open the export menu” is an agent decision. Locating that menu's
pixel coordinates is grounding. Confirming that the expected menu appeared
requires a new observation. A correct coordinate in an old screenshot can
still be the wrong action after the interface changes.
ScreenVLM converts screenshots into **ScreenTag** markup using a visual
encoder and Granite 165M decoder. Its training gives extra weight to element
types and locations. [Figure 2](#figure-2) shows the architecture.[^screenvlm]
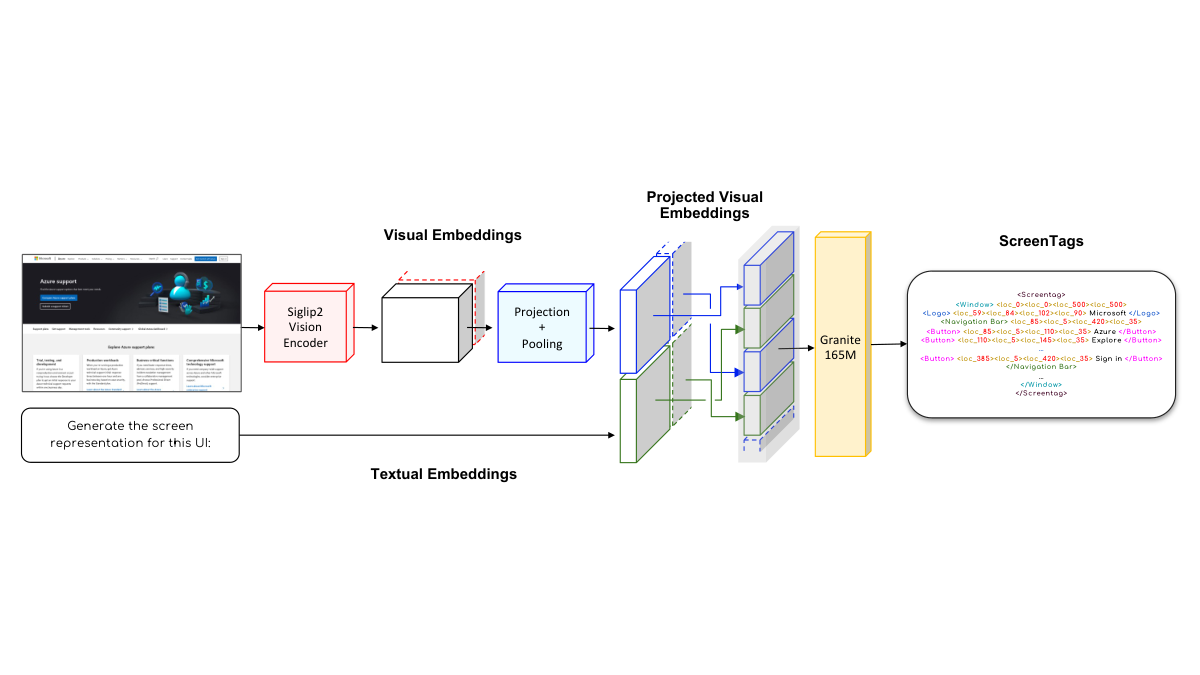
**Figure 2.** From screen pixels to structured markup. Reproduced from Gurbuz et al., arXiv v1, Figure 4. CC BY 4.0.[^screenvlm]
**Image description:** A screenshot enters a SigLIP2 vision encoder. Projected visual embeddings and text embeddings condition a Granite 165M decoder that emits structured ScreenTag markup.
The limitation matters: the dataset is predominantly web based, and the
paper identifies a gap to native desktop and mobile interfaces. Its reported
mean latency of **276.4 ms** is for 128 samples on a single H100 under vLLM,
not an on-device prediction.[^screenvlm]
## Documents: preserve evidence, not just a summary
Granite Docling is designed for document conversion, not general image
understanding. Its model card provides local inference paths and integration
with Docling's document representation. Docling MCP separately supplies a tool
interface and local conversion mode.[^granite][^docling]
PaddleOCR-VL-1.6 illustrates a different specialist design: a layout detector
locates regions and a compact VLM recognizes their contents. The system
organizes text, tables, formulas and other elements into structured outputs.
The upgrade focuses on targeted data refinement and staged continued
pretraining, supervised fine-tuning and reinforcement learning rather than
increasing model size.[^paddle]
For a cloud agent, the important design question is what survives conversion.
Our proposed evidence contract retains page references, reading order, table
headers, units, bounding boxes and access to a permitted source crop. A short
caption alone can discard exactly the detail a later question needs.
This does not require sending every artifact to the cloud. Keep originals
local, expose a bounded result and let the agent request a specific permitted
region when needed. A local file handle is not automatically resolvable by a
remote model. The host must mediate retrieval and any upload.
See [Document AI](/document-ai/) for the surrounding parsing and evaluation landscape.
## Video: an observation stream, not an unlimited upload
The IntBot recipe processes sampled camera frames through Cosmos-Reason2-2B
on Jetson AGX Thor and publishes structured events for downstream reasoning.
It reports a median **510 ms** perception pipeline latency with FP8, compared
with 762 ms at FP16 for its tested workload. These are first-party recipe
measurements, not our reproduction or a result for a whole cloud agent.[^cosmos]
A possible cloud integration would send selected events and allow targeted
clip inspection. That is our proposed extension, not the demonstrated IntBot
configuration. Preserve capture times, intervals actually inspected, dropped
frames and uncertainty. Sparse sampling can miss short events; an unobserved
interval is not evidence that nothing happened.
**Video generation fits the tool architecture, but is not perception.**
LTX Desktop documents local generation on supported NVIDIA GPUs and Apple
Silicon hardware. It also has API paths and optional cloud text encoding;
fully local operation requires a local text encoder. A cloud agent could
request a generated clip through a wrapper, but that integration and its
benefit would need separate validation.[^ltx]
For long generation jobs, our proposed interface returns a job ID, progress,
an output artifact and cancellation status rather than keeping a reasoning
call open. “Local” can mean a capable workstation, not a wearable or camera.
## Make the interface useful to the agent
The key interface is not merely `image → text`. It is a bounded request and
an attributable result. MCP supports named tools, input schemas, structured
results and optional output schemas. It does not itself choose model
placement or guarantee that a tool's claims are correct.[^tools]
For this architecture, we propose retaining:
- **Identity and freshness:** source, revision, page or frame, capture time
and the region actually inspected.
- **Task content:** elements, values, relations or generated artifacts in
a typed representation, plus explicit missing fields and failures.
- **Verification paths:** permitted crops or clips and links back to the
original evidence. Schema validity is not factual correctness.
- **Disclosure and authority:** which fields may leave the device and which
actions still require approval. Enforce this in the host, not a model label.
A small proposed result contract
This illustrative JSON is not a published model output or a standard MCP
schema. It avoids inventing a calibrated confidence score.
```json
{
"tool": "read_document_region",
"source_id": "invoice-42",
"revision": 3,
"page": 2,
"region_px": [100, 200, 600, 300],
"page_size_px": [2048, 1536],
"content": {
"type": "table_row",
"fields": {"quantity": "12", "unit": "boxes"}
},
"coverage": "requested region only",
"warnings": ["faint text in unit column"],
"source_crop_handle": "crop-17",
"disclosure": "host approval required"
}
```
Here coordinates use the original page image, with the origin at its top left.
The host resolves `crop-17` locally and decides whether a cloud request may
receive its bytes. The result does not give the agent permission to read other
files, change the disclosure policy or execute an action.
## Let the agent ask for better evidence
A fixed parser runs once and hopes it retained everything. An interactive
perception tool lets the agent ask a narrower question after seeing a result.
This is the design opportunity illustrated by [Figure 3](#figure-3).
The example is hypothetical: compare an invoice with a purchase order and
prepare an update. It is not a measured system or an account of private work.
**Read broadly, inspect selectively, act with approval**
**1 · Establish the evidence**
1. **Parse locally**: Recover invoice and order fields with page and region IDs.
2. **Disclose permitted fields**: The host checks access and sends only the approved evidence.
3. **Reason in the cloud**: The agent compares records and identifies an unclear quantity.
Parsing is an observation, not permission to update a business record.
**2 · Close the information gap**
1. **Request a closer read**: Ask for the quantity and unit in one identified region.
2. **Inspect locally**: Use a higher resolution crop or another specialist if allowed.
3. **Return attributable evidence**: Provide the value, units, source revision and unresolved ambiguity.
This is the feedback loop: the cloud chooses what to inspect next; the host bounds that request.
**3 · Complete the authorized action**
1. **Prepare the update**: The cloud agent drafts the change and cites its evidence.
2. **Approve and execute**: The host validates the proposed change and obtains required consent.
3. **Observe the result**: Check the actual saved record before reporting completion.
A changed source revision, failed tool call or unresolved mismatch returns the task to inspection or stops it.
Proposed constraints: bounded retries, resource limits, explicit disclosure policy and no write without the required authorization.
**Figure 3.** A targeted inspection loop with a separate action boundary. Proposed workflow informed by specialist grounding and tool contracts.[^agents2][^tools]
More observations cost time. Stop when the evidence is sufficient, the budget
is exhausted or the task requires a human. Do not turn uncertainty into an
unbounded conversation between models.
## Keep the cloud connection deliberate
A practical host would expose allowlisted operations such as parsing an
authorized file, locating a described control or inspecting a bounded clip.
The model service can sit behind an in-process adapter, local service or MCP
server. The cloud agent does not need a publicly reachable port on the device:
the local agent host can call the cloud API and dispatch returned tool requests
locally. This is a proposed deployment pattern, not a requirement of MCP.
Separate read access, disclosure and write authority. OCR text, screenshots
and tool results should be treated as untrusted task data, not instructions
that can override host policy. Limit file access, execution privileges,
timeouts, output size and concurrency. MCP's tool specification calls for
access controls and result validation; its security guidance also identifies
risks from local server compromise.[^tools][^mcp-security]
Local parsing does not make the overall system private if all recognized text
is uploaded afterward. Test actual outbound payloads, including logs and
optional model services. Without connectivity, a cloud-led agent can lose
planning capability even while its local tools remain available. Define that
failure mode rather than promising offline autonomy.
## Train for the capability, evaluate the whole task
For a specialist, begin with the contract it must satisfy. A parser needs
faithful structure and coverage; a grounder needs location precision; a video
tool needs event and temporal accuracy. Test those capabilities independently
before using agent success as a reward signal.
The next research step is to measure whether those outputs help a fixed
cloud planner. Our proposed study would vary output structure, evidence
budget and targeted reinspection while keeping the planner and task set
constant. If adding reinforcement learning, start with verifiable subtask
outcomes and audit reward shortcuts; do not assume that a fluent cloud judge
provides a reliable objective.
The following is a proposed evaluation plan, not a set of published results.
**Measure the system, not just the parser**
| Question | Measure | Control or failure case |
| --- | --- | --- |
| Does specialization help? | Task completion, extraction or grounding errors, human correction rate | Same cloud planner, task set and comparable evidence access; compare direct multimodal input, specialist input, and a combination. |
| Does local placement help? | Total task time at p50 and p95, cloud expenditure, device energy, bytes transferred | Compare local and remote versions of the same specialist; include cold starts, queueing, retries and network changes. |
| Does the interface lose evidence? | Omissions, incorrect relations, unsupported answers, answerability from retained artifacts | Compare plain summaries with structured results and permitted source crops; inspect failure slices. |
| Does interactive inspection pay off? | Success gained per extra request, elapsed time, number of rounds | Fixed initial parse versus targeted reinspection under the same total budget. |
| Does deployment remain safe? | Unauthorized reads, writes or disclosures; stale actions; behavior during outages | Adversarial document content, changed screenshots, denied tool access, unavailable specialists and dropped connectivity. |
Use separate training, threshold selection and final test sets. Report results
by screen density, layout type, language, video event duration, hardware and
network condition. Gains on a parser benchmark cannot substitute for this
complete-system comparison.
## Where the opportunity lies
The promising idea is not “a small model is cheaper.” It is **a specialist can
give a general agent better access to a particular environment**. The benefit
may come from precision, retained structure, domain adaptation or reduced data
movement. It must survive the integration and hardware costs.
My synthesis of this evidence is to prioritize three research questions:
1. **What evidence should cross the boundary?** Compare summaries, structured
representations and selective raw observations without hiding omissions.
2. **When should the agent look again?** Learn useful inspection requests
under a time, disclosure and computation budget.
3. **What should the specialist learn?** Connect perceptual fidelity with
downstream task value without sacrificing attribution or reliable abstention.
For a concrete starting point, build a document or computer-use task with one
cloud planner and one local specialist, then add targeted reinspection only
after establishing a fair baseline. See [On Device Computing](/edge-ai/on-device-computing/)
for hardware constraints and [Agent Evaluation](/agents/evaluation-reliability/)
for the wider testing discipline.
[^omni]: Yadong Lu et al., Microsoft Research. [OmniParser V2: Turning Any LLM into a Computer Use Agent](https://www.microsoft.com/en-us/research/articles/omniparser-v2-turning-any-llm-into-a-computer-use-agent/), February 12, 2025. Screen parsing and OmniTool composition.
[^omnitool]: Microsoft. [OmniTool README](https://github.com/microsoft/OmniParser/blob/master/omnitool/readme.md), Overview and Notes, inspected October 17, 2026. CPU support and optional separate GPU parser service.
[^agents2]: Saaket Agashe et al. [Agent S2: A Compositional Generalist-Specialist Framework for Computer Use Agents](https://arxiv.org/html/2504.00906v1), April 2025, Sections 3 and 4.3. Composition, grounding experts and controlled ablations.
[^agents3]: Simular. [Agent S repository](https://github.com/simular-ai/Agent-S), Grounding Models and Usage, inspected October 17, 2026. S3 main and grounding endpoints; documented recommended model pairing.
[^screenvlm]: A. Said Gurbuz et al. [Moving Beyond Sparse Grounding with Complete Screen Parsing Supervision](https://arxiv.org/html/2602.14276v1), February 15, 2026, Sections 4–6, Figure 4 and Table 7. [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/).
[^phi]: Microsoft Research Asia. [Phi-Ground: Improving how AI agents navigate screen interfaces](https://www.microsoft.com/en-us/research/articles/phi-ground-improving-how-ai-agents-navigate-screen-interface/), January 18, 2026. Grounding and the reported Copilot integration; no placement claim inferred.
[^granite]: IBM Research. [Granite Docling 258M](https://huggingface.co/ibm-granite/granite-docling-258M), model card, September 17, 2025 release, inspected October 17, 2026. Getting Started, Intended Use and Model Architecture.
[^docling]: Docling project. [Docling MCP](https://github.com/docling-project/docling-mcp), Local Mode, Features and Configuration, inspected October 17, 2026. Model, library and tool server are distinct.
[^paddle]: Zelun Zhang et al. [PaddleOCR-VL-1.6: Expanding the Frontier of Document Parsing with Under-Optimized Region Refinement and Progressive Post-Training](https://arxiv.org/html/2606.03264v1), June 2, 2026, Sections 2–4. Architecture and post-training recipe, not an agent placement study.
[^cosmos]: IntBot.AI. [Real-Time Vision-Language Models on Edge Hardware: Deploying Cosmos-Reason2 on Jetson Thor for Social Robot Perception](https://nvidia-cosmos.github.io/cosmos-cookbook/recipes/inference/reason2/intbot_edge_vlm/inference.html), NVIDIA Cosmos Cookbook, March 2026. Deployment architecture and Performance Evaluation; first-party measurements.
[^ltx]: Lightricks. [LTX Desktop](https://github.com/Lightricks/LTX-Desktop), Local Models, System Requirements and Text Encoding, inspected October 17, 2026. Local generation and optional external services, not a cloud agent study.
[^tools]: Model Context Protocol. [Tools](https://modelcontextprotocol.io/specification/2025-06-18/server/tools), June 18, 2025 specification, inspected October 17, 2026. Tool results, output schemas and security considerations.
[^mcp-security]: Model Context Protocol. [Security Best Practices](https://modelcontextprotocol.io/docs/2025-11-25/tutorials/security/security_best_practices), Local MCP Server Compromise, inspected October 17, 2026. Trust boundaries, consent and restricted execution.
Source: https://latentlit.com/local-cloud-ai/cloud-agents-local-specialists/index.mdx