Attention moves information between positions. A feed forward network, or FFN, transforms the features at each position. A feature gate changes that transformation; an expert router chooses which transformations run. The two can coexist, but they are not the same mechanism.123
A feature gate modulates, rather than selects
SwiGLU makes two projections of the same input and multiplies their outputs before a final projection. Omitting biases:2
x is a row vector of width D. Wg and Wu map D to hidden width F; Wd maps F back to D. The symbol ⊙ means elementwise multiplication, and σ is the logistic sigmoid.
SwiGLU
The same input x enters Wg and Wu. SiLU transforms the gate branch; elementwise multiplication combines both branches; Wd returns the result to width D.
Every branch is computed. The gate is not a probability and does not choose an expert.
Figure 1. Two computed branches, one multiplicative transformation. Independent schematic of the bias omitted SwiGLU FFN.2
Both branches in Figure 1 run for every token. SiLU is smooth, can be negative, and is unbounded above. The branch is therefore not a probability in the range zero to one. Its learned multiplication can modulate features without being an expert selection rule.2
Compare gates at a comparable budget
A conventional two projection FFN has about 2DFdense weights; a gated FFN has about 3DFgate. Ignoring biases, equalizing those counts gives a local calculation:
The GLU paper uses this width adjustment. Its controlled T5 results support gated variants in that setting, not a guarantee that the same activation always wins at arbitrary width or training budget.2
A router chooses separate FFNs
An MoE sublayer holds several experts, each with separate weights. A router scores the current token representation and dispatches it to selected experts. The weighted result returns to the usual residual width. Routing can change with token and layer; an expert ID is not automatically a fixed subject label.3
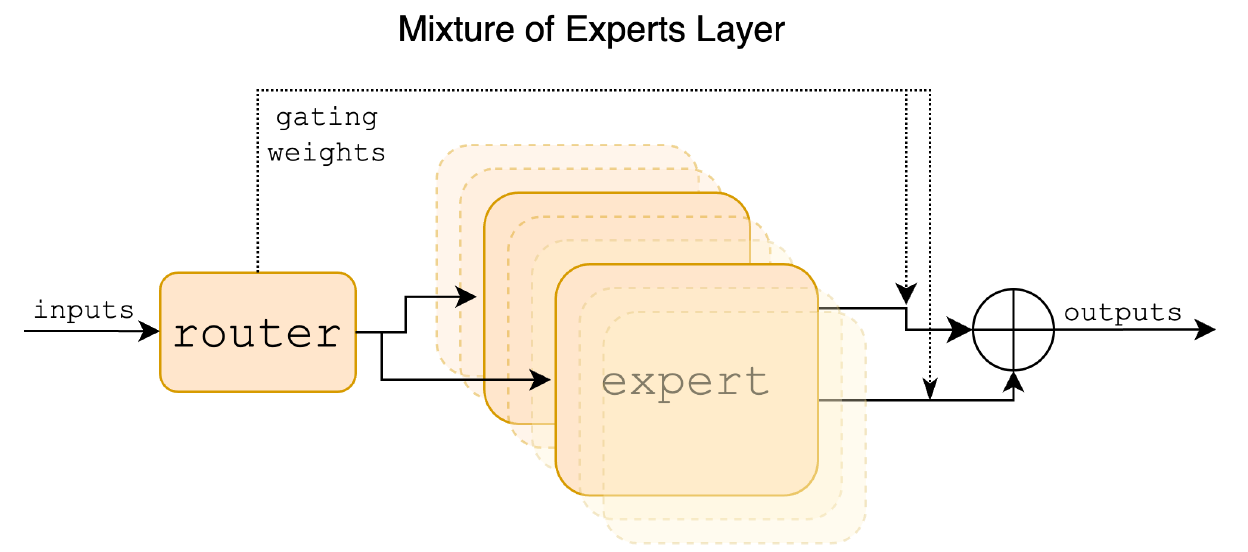
Figure 2. Selected experts run in parallel, not in a chain. Reproduced from Jiang et al., Mixtral Figure 1; unchanged figure crop, CC BY 4.0.3
In Mixtral, each expert is itself a SwiGLU FFN. Thus the router in Figure 2 selects entire transformations, while the gate in Figure 1 operates inside each selected transformation.3
For token x, let S(x) be the selected set and g its router logits. A compact form of Mixtral’s top two normalized mixture is:3
Ei is expert i. The weights in this equation sum to one over the selected set. Do not assume every other MoE normalizes or selects identically.
Routing designs differ in meaningful ways
| Design | What changes | Concrete study |
|---|---|---|
| Top two from eight experts | A simple sparse replacement for the dense FFN | Mixtral3 |
| Shared plus routed experts | Shared computation runs alongside a selected subset | DeepSeek-V24 |
| Bias controlled selection | Balancing biases affect selection, not the output mixing weights | DeepSeek-V35 |
| Routed experts without shared experts | Different family members have dense or sparse capacity | Qwen36 |
This is a mechanism comparison, not a quality ranking. V3’s “auxiliary loss free” balancing refers to its main batch balancing method; a small sequence balancing loss remains.5 Likewise, GLM-4.5’s separately trained reasoning, agentic and chat specialists are policies, not its routed FFN experts.7
For additional released designs, compare gpt-oss and the MiniMax family. Keep each study’s exact version and counting convention.
Sparse computation still needs a system
Selected expert weights reduce active computation relative to evaluating every expert. Total weights still need storage somewhere. Dispatch, gathering, communication, load imbalance, precision, and batch size affect whether the design is efficient in practice.
Compare total parameters, active parameters, actual FLOPs, weight residency, communication, and latency separately. “Active parameters” is a useful summary, not a complete FLOP or VRAM measurement. Nor is a sparse FFN the same thing as sparse attention.
Selected mechanisms rechecked October 10, 2026. No routing or serving experiments were run here. For the surrounding residual block, continue with Depth and residual paths.
References
-
Ashish Vaswani et al. Attention Is All You Need, 2017, section 3.3. ↩
-
Noam Shazeer. GLU Variants Improve Transformer, 2020, equations 5 and 6 and the matched width experiments. Equation (2) is a local parameter count. ↩ ↩2 ↩3 ↩4 ↩5
-
Albert Q. Jiang et al. Mixtral of Experts, 2024, section 2, Figure 1 and routing analysis. Equation (3) restates its selected softmax mixture. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
DeepSeek-AI. DeepSeek-V2, 2024, section 2.2. ↩
-
DeepSeek-AI. DeepSeek-V3 Technical Report, 2024, section 2.1.2. ↩ ↩2
-
Qwen Team. Qwen3 Technical Report, 2025, architecture: dense and expert variants. ↩
-
Zhipu AI. GLM-4.5, 2025, post training specialists and unified ARC policy. ↩