Document AI turns pages into usable, auditable information. Reading the text is one step. The larger system must preserve structure, extract or reason over evidence, and decide which results can enter a downstream workflow.
At a glance: preserve structure, allocate visual compute deliberately, and evaluate the task rather than the fluency of the output.
Choose a route: Understand the field · Compare models · Evaluate a system · Compare products · Choose for a workload.
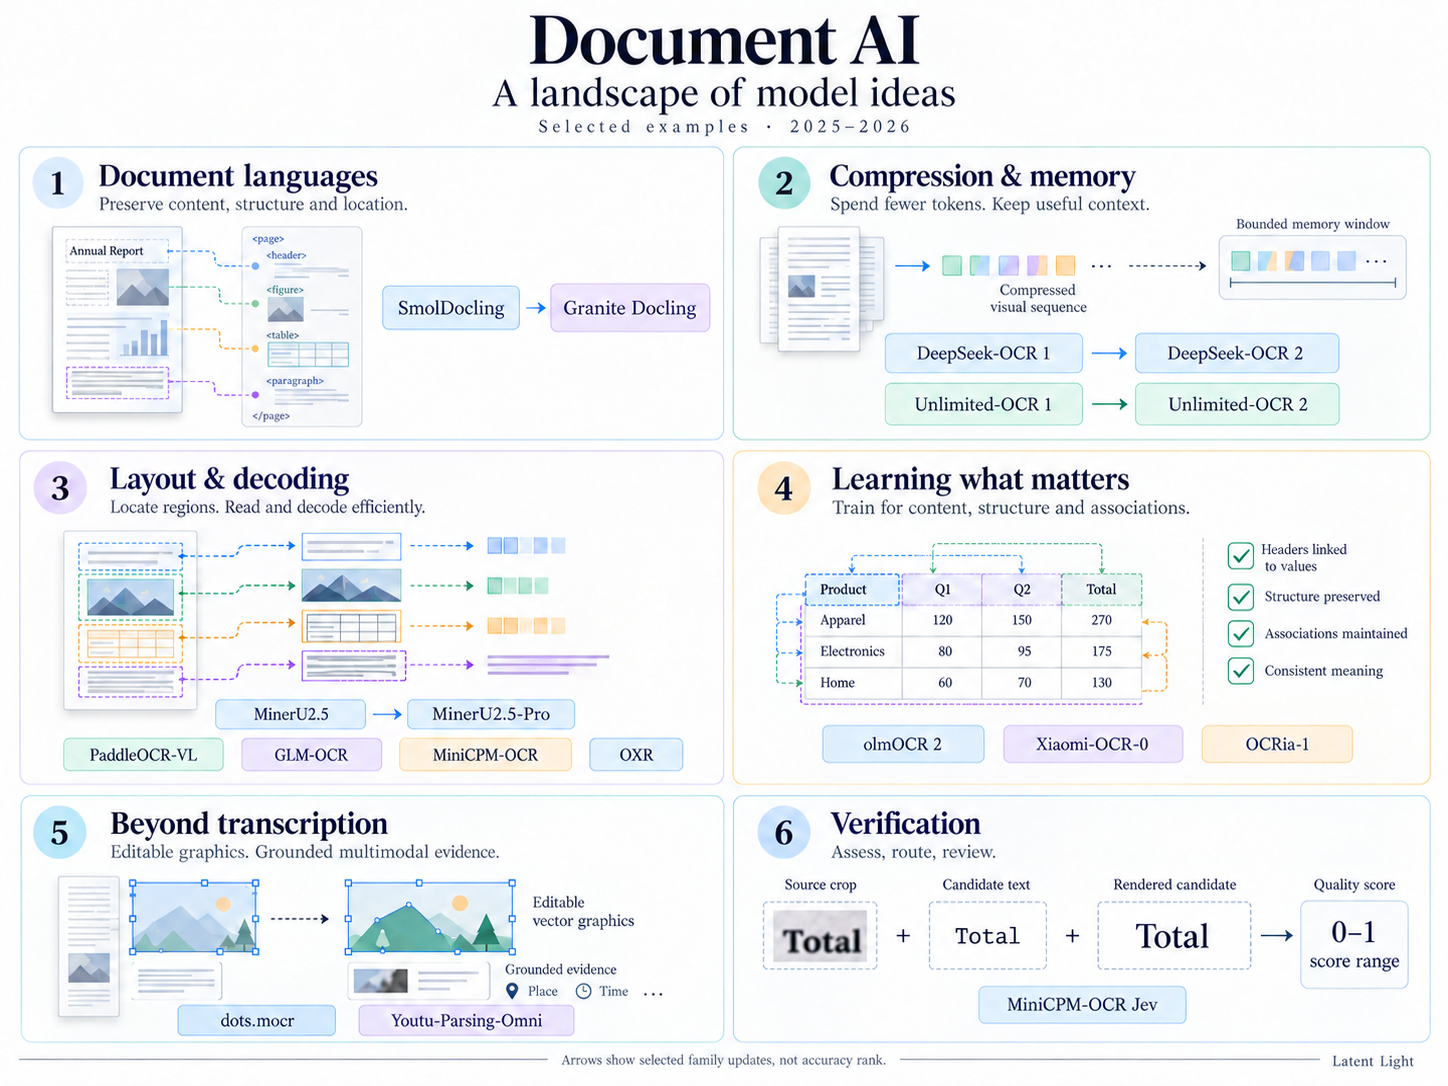
Figure 1. A landscape of model ideas. Original AI-generated synthesis of selected models reviewed here. Arrows show family updates; the pages and table are illustrative, and the 0–1 tile is Jev’s score range.12
Figure 1 offers a quick orientation. Explore the interactive family atlas for dated milestones, verified connections and links to each study.
Read the infographic in text
- Document languages: SmolDocling → Granite Docling. Typed document representations preserve content, structure and location.34
- Compression and memory: DeepSeek-OCR 1 → 2 improves compressed visual reading; Unlimited-OCR 1 → 2 develops bounded output history, sparse visual access and page-chunk memory control. These are separate family paths, not an initialization arrow from DeepSeek-OCR 2 to Unlimited-OCR.5678
- Layout and decoding: MinerU2.5 → MinerU2.5-Pro retains the architecture while improving data and training. PaddleOCR-VL, GLM-OCR, MiniCPM-OCR and OXR are additional examples of locating regions and allocating recognition or decoding work; they are not shown as one ancestral chain.910111213
- Learning what matters: olmOCR 2, Xiaomi-OCR-0 and OCRia-1 illustrate training for document content, structure and associations through curated data, task objectives and verifiable rewards.141516
- Beyond transcription: dots.mocr represents eligible graphics as editable SVG; Youtu-Parsing-Omni provides grounded records across images, documents, audio and video.1718
- Verification: MiniCPM-OCR Jev compares a source crop, candidate text and rendered candidate to return a score in the range 0–1. It assesses existing OCR; the range is not a measured accuracy or proof of probability calibration.2
The short answer
A complete application can recover reading order and layout, recognize tables and formulas, split document packets, extract a typed schema, retrieve evidence, answer questions and summarize. Business rules, uncertainty routing and human review determine which results can move into a downstream system.
The field has moved from engineered OCR pipelines, through learned perception and layout-aware pretraining, to OCR-free document models and modern vision-language models (VLMs). These are overlapping eras rather than a clean replacement sequence. Modular pipelines remain strong where coordinates, determinism, latency, or local execution matter. VLMs adapt better to novel layouts and flexible questions, but can omit, invent, or reorder content.
A useful production starting point is adaptive and hybrid: use native text or compact specialists for easy content, spend high-resolution or general-VLM compute on difficult regions, and add source grounding, validation, abstention, and risk-based review where errors are costly. This is a design recommendation, not a universal benchmark finding.1920
Review boundary · October 31, 2026. The recent release studies, selected retrieval models, benchmark updates and product boundaries below were checked against primary sources. Historical report results keep their named versions and dates; retained model mechanisms are not all new inspections. No model or commercial service benchmark was run for this guide.
What must be understood beyond the text
Two kinds of structure matter: geometric structure identifies regions on a page, while logical structure assigns meaning such as heading, paragraph, table, field, or footnote.21 Modern Document AI extends the logical layer into retrieval, reasoning, and workflow action.
Task layers
8 layers| Layer | Representative tasks | Typical output | Failure that OCR accuracy misses |
|---|---|---|---|
| Capture | decode, deskew, denoise, orient, dewarp | normalized pages | correct text from a wrongly oriented page |
| Text perception | OCR, handwriting, text spotting | words, lines, boxes, confidence | one wrong digit in an account number |
| Layout and structure | regions, reading order, tables, formulas, charts | blocks, tree/graph, Markdown, HTML, JSON | two columns interleaved into plausible nonsense |
| Organization | classification, splitting, page grouping | type labels and page ranges | one packet sent to the wrong extractor |
| Extraction | fields, entities, line items, clauses, relations | typed schema with evidence | correct value assigned to the wrong field |
| Retrieval and QA | page/region retrieval, single- and multi-document QA | answer with page or box citations | plausible answer unsupported by the document |
| Generation | summary, comparison, report, translation | grounded narrative or synthesis | an exception clause silently omitted |
| Workflow | rules, validation, approval, review, export | accepted result and audit trail | uncertain output enters a system of record |
No matching layers. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
The evaluation unit changes at every layer. Character error rate does not measure table structure; bounding-box accuracy does not measure reading order; exact match does not fully measure semantic answers; and fluency does not measure summary faithfulness. There is no meaningful “document accuracy” until the task, corpus, metric, and cost of each error are specified.
Three input regimes also need different routing:
- Born-digital documents may contain cheap text and font information, but PDF object order need not match human reading order.
- Scans and photographs add skew, blur, shadows, warping, compression, and handwriting.
- Mixed, visually rich documents combine prose with tables, formulas, charts, stamps, signatures, and figures whose relationships carry meaning.
Document AI is a system.
From a page to a trustworthy result, with its evidence intact.
- 01Receive
- 02Read
- 03Preserve
- 04Understand
- 05Act
Documents
- Digital PDFs and Office files
- Scans, photos and handwriting
- Tables, charts and mixed packets
Read the page
- Recognize text and regions
- Recover reading order
- Parse tables, formulas and figures
Preserve meaning
- Keep hierarchy and typed blocks
- Retain coordinates and table structure
- Link chunks to source evidence
Use the content
- Classify and extract a schema
- Retrieve evidence and answer
- Summarize or reason across documents
Operate safely
- Validate fields and business rules
- Accept, abstain or request review
- Export with an audit trail
- Corpus and slice evaluation
- Field, structure and grounding checks
- Risk-based human review
- Cost, latency and drift monitoring
Reviewed corrections → regression tests → deliberate updates to prompts, schemas, rules and routing.
Functional layers, not five required model calls. Classification and routing can happen earlier; difficult pages can take a specialist or VLM path. Corrections do not automatically become training data.
Figure 2. Five layers, one evidence trail, and a human review loop.
Figure 2 separates reading the page from preserving its meaning, using its content and accepting a result. Reliability is a cross-cutting loop, not a final check. This is a proposed system map, not a fixed execution order.
How the technical stack evolved
1. OCR and engineered pipelines
Classical systems separated preprocessing, page segmentation, OCR, reading-order heuristics, logical labeling, and export. Forms and invoices were often handled with templates, anchors, coordinates, regular expressions, and dictionaries. The pipeline was inspectable, but brittle when layouts, languages, or capture conditions changed.
2. Learned perception and task-specific extraction
CNNs, sequence models, and object detectors improved recognition, classification, region detection, and key-information extraction. Larger datasets expanded layout diversity: DocLayNet provides 80,863 manually annotated pages across 11 layout classes, and its baseline models remained below inter-annotator agreement in the paper’s baseline experiments.21
3. Layout-aware multimodal pretraining
LayoutLM jointly encoded text, 2-D coordinates, and visual appearance instead of treating OCR output as a one-dimensional sentence. LayoutLMv3 later unified text and image masking and added word–patch alignment.2223 This encoder family remains useful for classification and token-level extraction when OCR and boxes already exist, though it inherits upstream OCR errors and often needs task-specific fine-tuning.
4. OCR-free generation
Donut reframed document understanding as image-to-sequence generation and argued that an external OCR engine adds cost, rigidity, and error propagation. Its synthetic document generator also anticipated the present importance of controllable synthetic supervision.24
“OCR-free” does not mean that reading disappears—the model learns visual text recognition internally. It changes the error boundary: instead of inspecting OCR tokens and boxes, a decoder can omit, hallucinate, or structurally misgenerate content. Later systems expanded image-to-sequence and instruction formats across screenshots, documents, tables, charts, and QA.2526
5. Specialists, general VLMs, and hybrids
The current categories are complementary:
Four complementary approaches
4 approaches| Approach | Main advantage | Main weakness | Strong fit |
|---|---|---|---|
| Modular pipeline | explicit artifacts, control, cheap native-text paths | brittle boundaries and error propagation | stable schemas, coordinates, local or low-latency systems |
| Document specialist | dense text and structure per unit of compute | narrower general reasoning | page conversion, tables, formulas, private serving |
| General VLM | flexible questions and broad language/visual knowledge | cost, hallucination, weaker diagnostics | unusual pages, ad hoc QA, cross-page reasoning |
| Adaptive hybrid | route each page or region to the right path | orchestration and evaluation complexity | heterogeneous production corpora |
No matching approaches. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
No universal SOTA. OCR, layout detection, page conversion, information extraction, document QA, and summarization use different datasets and metrics. Even for parsing, rankings can change between clean digital pages and degraded scans. “Best” only has meaning for a pinned task, corpus, model version, prompt, evaluator, and operating constraint.
The 2026 technical frontier
Page parsing is becoming structured generation
Modern parsers increasingly output Markdown, HTML-like tokens, bounding boxes, or typed document languages rather than plain text. SmolDocling is an especially useful result: its 256M-parameter VLM emits DocTags encoding content, structure, and location, showing how domain specialization can compensate for raw model scale.3
The recent releases change the system in four connected ways:
- Allocate compute at inference. Region parsers spend pixels on selected crops; Nemotron 3.5 Parse offers additional table/chart refinement passes; Unlimited-OCR 2 separately controls attended tokens and resident page memory. These are different accuracy, latency and context tradeoffs.27288
- Train for usable structure. olmOCR 2 supplies executable tests, Xiaomi-OCR-0 connects parsing with understanding tasks, and OCRia-1 rewards header–value associations and formatting. A better string match alone does not establish a usable table or field.141516
- Assess a candidate separately. Jev adds a released region verifier; its score still needs workload calibration, and it cannot recover a region that the parser never detected.2
- Preserve more than a transcript. DocTags, editable graphics and spatial or temporal records make representation part of the model contract. Retrieval can also search the page image directly, rather than relying on one flattened text view.3171829
The persistent hard cases are reading order across columns and sidebars, hierarchical or multi-page tables, chart geometry, small and multi-line formulas, meaning-bearing formatting, and associations among captions, footnotes, units, and objects.
In its May 2026 study, PureDocBench evaluated 40 systems on source-traceable clean, digitally degraded, and physically degraded variants. Its best overall score was only about 74/100; specialists no larger than 4B parameters could rival or exceed general VLMs 5–100 times larger, while general VLMs sometimes degraded more gracefully. No evaluated model exceeded 67% on the formula metric averaged across the three tracks. These are results for that study’s tested models, not a ceiling on later releases.19
The maintained PureDocBench repository is a later artifact: its September 26 update covers 58 models, and an October 27 PaddleOCR-VL-1.6 pipeline rescore uses explicitly recorded ground-truth and evaluator revisions. A current leaderboard row and the original paper table must not be treated as the same experiment. Pin the predictions, reference labels, rendering and scorer before comparing a new result with an older one.30
How to read the current model frontier
There is no useful single ordering of “the best OCR models.” The current frontier mixes one-shot VLMs, layout-first systems, document converters, reward-optimized parsers, and models that also answer questions or reconstruct graphics. The more durable question is: where does each design allocate pixels, tokens, decoding time, and supervision?
- Page detailSmall text versus image cost
- Compact visual tokensSmolDocling, DeepSeek-OCR and HunyuanOCR
- Two dimensional evidenceColumns, sidebars and connected regions
- Organize before decodingLayout-first parsing or DeepSeek causal-flow queries
- Locate globallyLow resolution layout
- Read locallyMinerU and PaddleOCR region recognition
- Long structured outputsEach autoregressive step costs time
- Predict or verify blocksGLM MTP, Hunyuan DFlash, HPD branches or diffusion
- Keep the sourceRetain all references, or select a working subset
- Bound output historyUnlimited-OCR R-SWA; version 2 adds SR-SWA and page chunks
- Define usable informationStructure, semantic tests or editable graphics
- Train for that contractDocTags, olmOCR unit tests and dots.mocr SVG
Figure 3. A mechanism map synthesized from the model reports discussed below. It is not a ranking.
Figure 3 organizes the studies by their bottleneck, not their release date or parameter count.
Architecture primer
As an interface sketch, a document VLM can be written as
where vision encoder turns page into visual tokens, connector compresses or projects them into the language-model space, prompt selects the task, and decoder generates structured output . This sketch does not specify attention wiring: visual-prefix decoders and cross-attending encoder–decoders implement the interface differently. Models differ along four practical axes:
- Visual input: fixed square, native-resolution page, dynamic tiles, or layout-selected crops.
- Token organization: raster order, explicit layout order, or a learned semantic sequence.
- Generation: ordinary autoregression, multiple tokens per step, or a draft-and-verify path.
- Output and supervision: plain text, document markup, JSON, executable tests, or renderable graphics code.
Recurring building blocks include:
- Native-resolution or NaViT encoding: patch images at their natural aspect ratios instead of stretching every page into a fixed square.
- 2-D or multimodal RoPE: encode row, column, and sometimes modality coordinates rather than only one text position.
- Pixel shuffle, patch merger, or convolutional compressor: merge nearby visual tokens so the decoder sees a shorter sequence.
- Connector or projector: map vision features into the decoder’s embedding width, commonly with a small MLP.
- MTP or speculative decoding: advance several output tokens per expensive target-model step.
- RL with verifiable rewards (RLVR): optimize outputs using executable checks or task metrics rather than only next-token likelihood.
Model families and evolution
Figure 4 places the models in time and groups their main design themes. It complements the budget map: the lanes orient you across models, while the budget map explains where their mechanisms spend resources. Select a model for its dated milestone, contribution, scale, access and study.
A landscape of ideas · 2025—2026
Document AI family atlas29 milestones. Five approaches. A separate verification rail.
DeepSeek-OCR 1 → DeepSeek-OCR 2 · DeepSeek-OCR 1 ⇢ Unlimited-OCR · Unlimited-OCR ⇢ Unlimited-OCR 2
Nemotron Parse 2.0 → Nemotron 3.5 Parse · LightOnOCR-2 → LightOnOCR-3
Sparse visual access and overlapping page chunks separately control attention and resident KV.
Lanes are overlapping design themes, not ancestry. Solid arrows show family/design updates; dashed arrows show explicit checkpoint initialization. Dates identify the cited report revision, release log, announcement or benchmark snapshot, not necessarily first weight availability. Time columns are unequal periods, not a proportional scale.
Figure 4. A family atlas of the models covered here. Solid arrows mark family or design updates; dashed arrows mark documented checkpoint initialization. Lanes overlap, and dates identify the cited milestones rather than first weight availability.1
Model map at a glance
This is a selected map of mechanisms, not an exhaustive release inventory.
Compare the same four fields across the models below. Rows follow the detailed
studies; select a model name to jump to its explanation. Search by name, design
or access—for example, region, verifier or hosted.
Sizes describe the named network, not the full serving pipeline. Weights means an official checkpoint was identified in the dated reviews above; unverified means checkpoint availability was not established. Hosted access and custom license terms are marked separately. These models were not run for this review, and the table is not an accuracy ranking. Parameter counts retain the source’s scope: decoder-only, core-model and inference counts are not a normalized full-pipeline comparison.
Document models at a glance
27 models| Model | Scale and access | Design | Output |
|---|---|---|---|
| SmolDocling3 | 256M; weights | Converter: compact visual tokens and a document-native vocabulary | DocTags → Markdown/HTML/JSON |
| Granite Docling4 | 258M; weights | Converter: SigLIP2, pixel shuffle and a Granite decoder | DocTags → structured document |
| DeepSeek-OCR 15 | 3B MoE decoder; weights | End-to-end: local→global vision encoding with optical context compression | Text and structured parse |
| DeepSeek-OCR 26 | 3B MoE decoder; weights | End-to-end: causal-flow queries reorganize compressed visual evidence | Text and structured parse |
| Unlimited-OCR 1 / 278 | 3B MoE decoder; weights | Multi-page: R-SWA bounds output history; version 2 adds sparse visual access and page chunks | Layout-tagged text and structured parse |
| HunyuanOCR-1.531 | 0.5B decoder + vision; weights | End-to-end: 4K images, 128K context and DFlash decoding | Markdown, HTML, LaTeX, QA and extraction |
| LightOnOCR-2 / 33233 | v2: 1B; v3: 0.8B/1B/4B; weights | End-to-end: distilled data, localization RL and variant-specific grounding | Transcription; boxes and chart data in supported variants |
| Nemotron Parse 2.034 | Under 1B; weights | Encoder–decoder: C-RADIO vision features with cross-attending mBART | Text, element classes, reading order and locations |
| Nemotron 3.5 Parse28 | ≈0.631B including MTP; weights, OpenMDW-1.1 | Visual-prefix parser: C-RADIOv4, mBART and optional crop-refinement passes | Text, element classes, reading order and normalized boxes |
| Chandra OCR 23536 | 4.5B in publisher’s inference count; weights with custom terms | End-to-end: Qwen3.5-style released configuration and layout-aware conversion | Markdown, HTML and JSON with layout |
| MinerU2.527 | 1.2B; weights | Region parser: thumbnail layout, then native-resolution crop recognition | Boxes and ordered element transcriptions |
| MinerU2.5-Pro9 | 1.2B; weights | Region parser: retain 2.5 architecture, improve data curation and training | Boxes and ordered element transcriptions |
| PaddleOCR-VL 1.610 | 0.9B recognizer; weights | Region parser: detector→parallel crops, weak-region refinement and staged training | Markdown/JSON and text spotting |
| GLM-OCR11 | 0.9B; weights | Region parser or direct KIE: shared multi-token prediction heads | Markdown/JSON or field JSON |
| MiniCPM-OCR 1.012 | 1.3B recognizer; weights | Region parser or direct KIE: optional DSpark draft decoding | Markdown, HTML tables, LaTeX or field JSON |
| OXR-1.01337 | Advertised 1.3B; weights with custom terms | Region parser: replaceable layout, learned visual vocabulary, recognition and order branches | Markdown/JSON with coordinates |
| Surya OCR 238 | ≈650M VLM plus separate line detector; weights with custom terms | Prompt-selected recognition/layout/table tasks with a shared VLM | Text, layout/reading order, HTML and table structure |
| HPD-Parsing39 | Main model + P-MTP weights | Branching parser: layout coordinates parallel content decoding; custom runtime | Structured parse |
| MinerU-Diffusion40 | Report; weights unverified | Diffusion parser: parallel block decoding, curriculum and inverse-rendered data | Document transcription |
| olmOCR 214 | 7B; weights | End-to-end: executable document tests as GRPO rewards | Metadata and ordered document text |
| dots.mocr17 | 3B; weights | Task-conditioned multi-pass: reconstruct eligible graphics as renderable programs | Ordered text, markup, LaTeX and SVG |
| TeleOCR41 | Report; weights unverified | Parser: deformation-aware learning and content/structure decoupling | Structured parse |
| Xiaomi-OCR-01542 | 0.8B base; weights | Region parsing or direct page/KIE/VQA: Q-Mask, curated data and mixed-task RL | Structured parse, field JSON or answers |
| WeVisDoc43 | 2B/4B; weights | End-to-end: broad coverage, then held-out error diagnosis and targeted training | Ordered Markdown, HTML tables and LaTeX |
| OCRia-11644 | 4B; hosted in LlamaParse; public weights unverified | Parser: structured rewards for table associations, chart values and formatting | Markdown/HTML and LaTeX; no boxes |
| Youtu-Parsing-Omni18 | 5B; weights with custom Youtu terms | Multimodal parser: shared perception encoder and reference-conditioned distillation | Structured records with spatial/temporal evidence |
| MiniCPM-OCR Jev2 | 2B; weights, Apache-2.0 | Verifier: compare the source crop, candidate text and rendered candidate | Quality score for text/table/formula candidates; no OCR generation |
No matching models. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
A. End-to-end compression and visual reading flow
These models feed the page directly into one VLM. Their central problem is how to retain small text and two-dimensional structure without flooding the decoder with thousands of visual tokens.
SmolDocling: make the document language compact
SmolDocling uses a 93M SigLIP patch-16/512 visual backbone, aggressive pixel shuffle and projection, and a 135M SmolLM2 decoder. Each 512×512 image becomes 64 visual tokens—4,096 pixels per token—bringing the total model to 256M parameters.3
It emits DocTags, an intermediate language with typed elements, nested relationships, location tokens, and a table vocabulary. Docling later converts that representation into Markdown, HTML, or JSON. Its design bet is that a small model can perform conversion well when both its visual sequence and its output language are carefully compressed. The tradeoff is specialization: it is a converter, not a broad document-reasoning model.
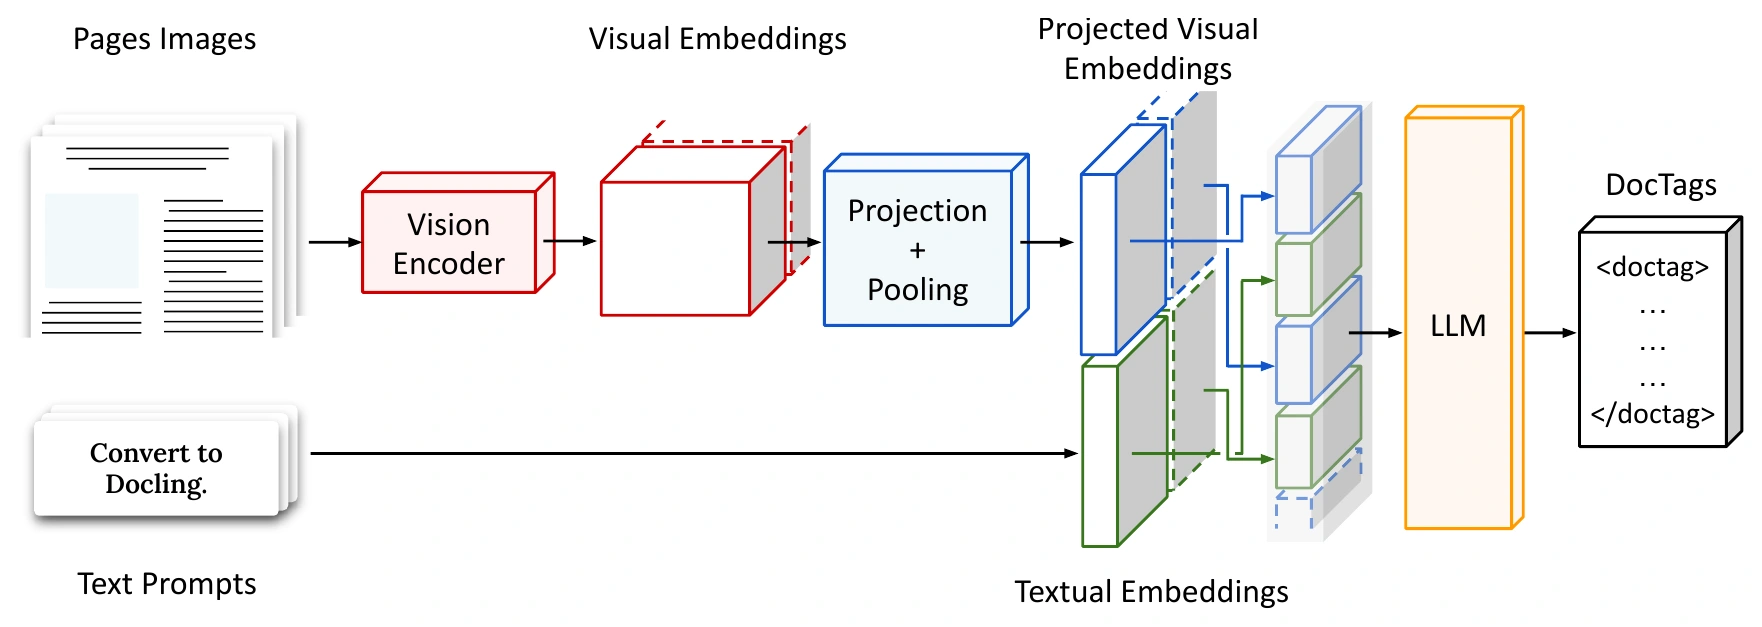
Figure 5. Document conversion into DocTags. Nassar et al., SmolDocling, Figure 1, arXiv v1, page 2; figure excerpt, CC BY 4.0.345
Figure 5 shows both visual and prompt embeddings entering one document-language decoder.
Granite Docling: the next compact document-native converter
Granite Docling combines a SigLIP2 base patch-16/512 encoder, pixel-shuffle projection and a Granite 165M text decoder for 258M parameters. Its training first familiarizes the language model with DocTags, then teaches the full VLM conversion using public and synthetic document data. It supports full-page conversion, bounding-box-guided regions and structural questions. It is not intended as a general image-understanding model.4
Model and usage · Docling integration
The architectural continuity matters more than a size contest: the output language makes location, type and structure explicit. Experimental language coverage is not equivalent to validated quality on each language.4
DeepSeek-OCR 1: treat the page as optical context compression
DeepSeek-OCR asks how many visual tokens are needed to reconstruct much longer text. Its 380M DeepEncoder first applies an 80M SAM-based window-attention stage to many local patches, reduces their count 16× with two convolutional layers, then applies a 300M CLIP-based global-attention stage. A 3B DeepSeek MoE decoder activates roughly 570M parameters per token.5
Resolution modes trade fidelity for tokens: 512² and 640² inputs emit 64 and 100 tokens, while larger native or tiled modes emit hundreds to more than one thousand. This is not lossless compression; the paper’s own results degrade as the text-to-vision-token ratio becomes extreme. Its contribution is a concrete local-attention → compression → global-attention recipe for controlling visual activation memory.
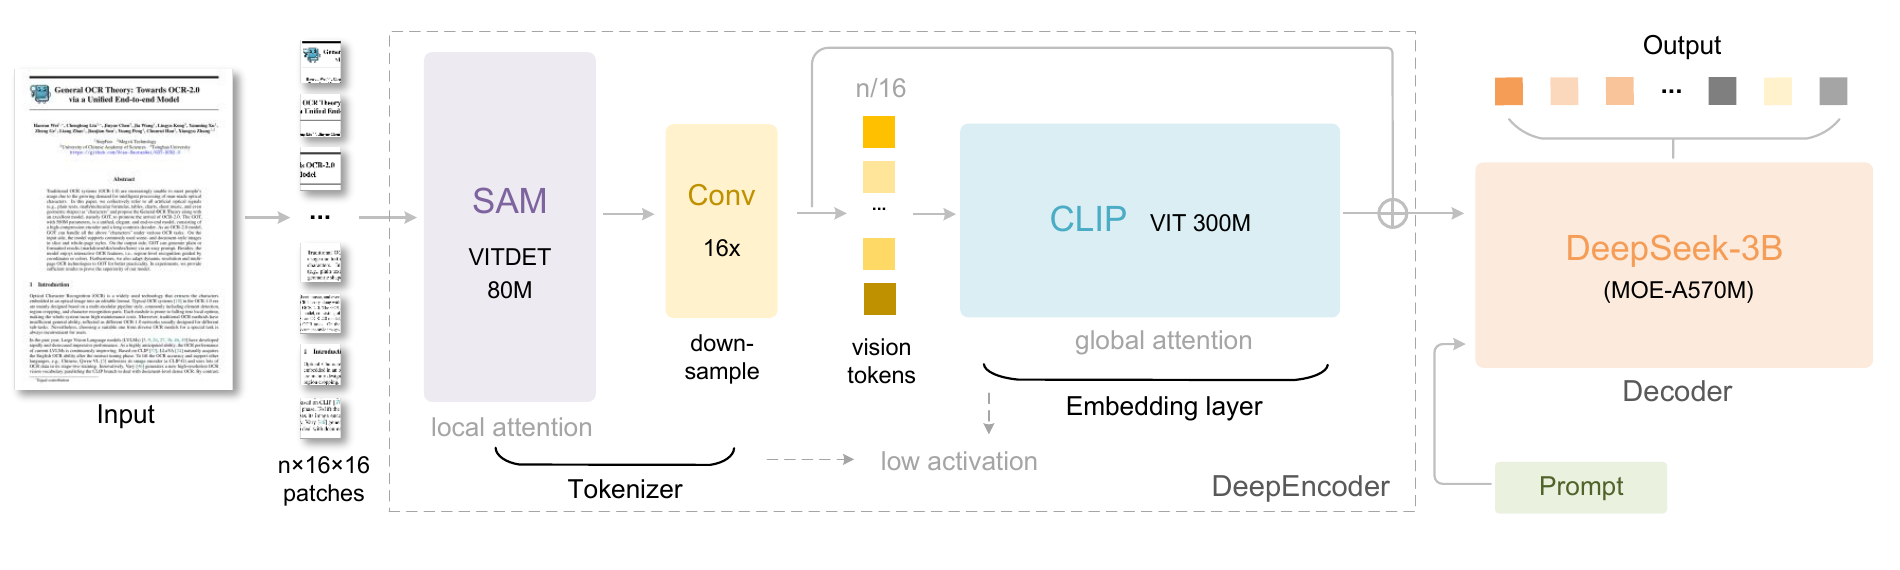
Figure 6. DeepSeek-OCR, Figure 3, arXiv v1, page 5; figure excerpt, CC BY 4.0.545
Figure 6 places compression before global vision attention, controlling the expensive visual sequence.
DeepSeek-OCR 2: learn a causal flow over visual evidence
Motivation: learn a useful sequence of visual representations before the language decoder generates text. A document is two-dimensional; flattening patches row by row need not match its logical reading order.6
For example, imagine a two-column page. A raster sequence moves across both columns, whereas a reader might finish the left column first. This is an illustration of the ordering problem—not a claim that ordinary vision encoders cannot understand columns or model global relationships.
Version 2 preserves the 80M tokenizer, 16× compression, and 3B MoE decoder, but replaces CLIP with a Qwen2-0.5B LM-style vision encoder. Compressed visual tokens attend bidirectionally. An equally large set of learned causal-flow queries sees every visual token and only earlier queries; only those query outputs are passed to the decoder.6
Think of the queries as learned reading slots: each gathers page evidence while incorporating earlier slots’ representations. This is intuition, not a guarantee that an individual slot corresponds to a particular document region. The mechanism is not an explicit sorting algorithm or a discrete permutation of patches. Query positions are processed in parallel through masked transformer layers, rather than generated one at a time.6
The intended effect is semantic ordering before language generation. With a global view and zero to six local crops, the encoder sends 256–1,120 query tokens to the decoder. “Reordering” is the authors’ interpretation of the learned query sequence—not a directly observed human reading path—but the attention mask is precise:
The top-left block gives visual tokens full mutual visibility; the lower-right block makes the flow queries causal. The decoder then performs a second causal stage over the resulting sequence.
Equation (2) is a visibility mask: one means allowed and zero means blocked. It is not the additive mask used directly in attention logits; the additive equivalent uses zero for allowed entries and negative infinity for blocked entries. The diagonal of the query block is allowed, so a query can attend to itself as well as earlier queries.
Takeaway: the encoder organizes visual evidence into learned sequential representations; the decoder turns those representations into text.
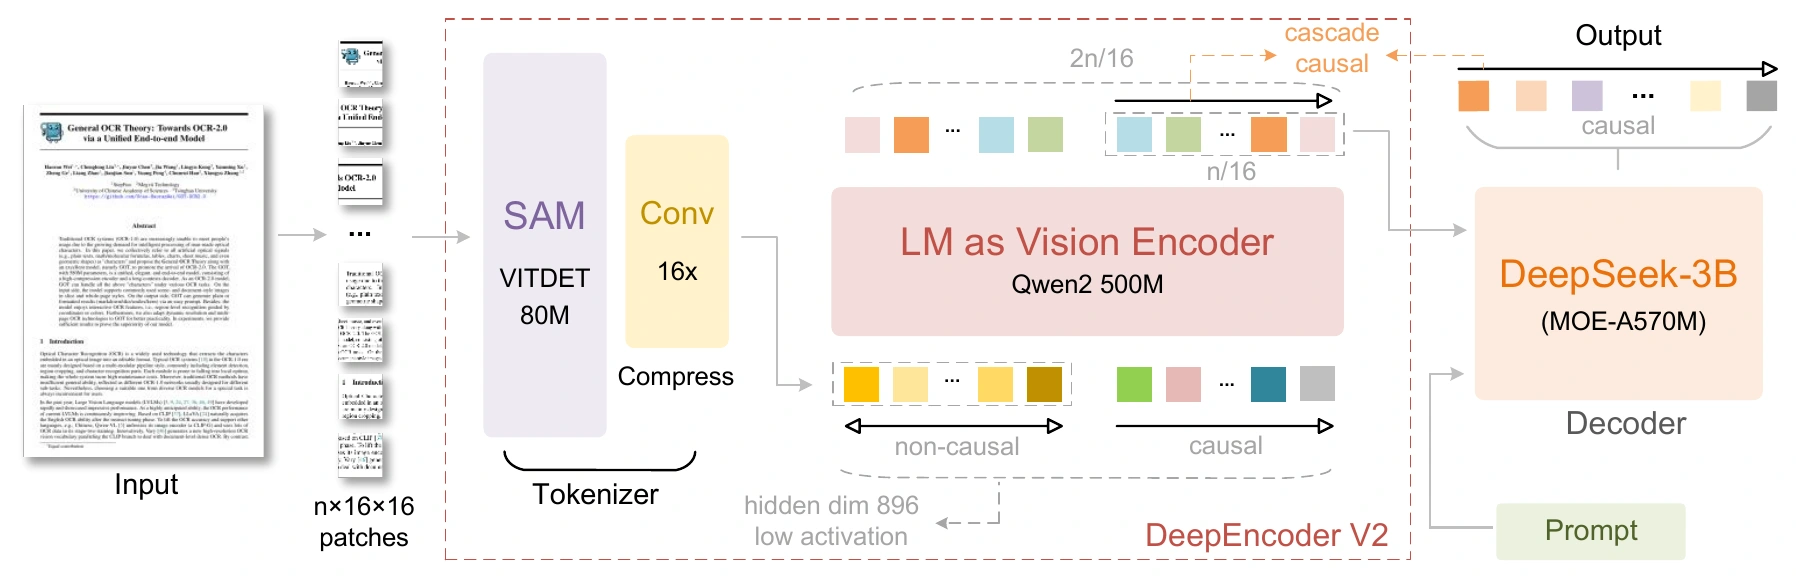
Figure 7. DeepSeek-OCR 2, Figure 3, arXiv v1, page 5; blank margins removed, CC BY 4.0.645
Figure 7 replaces CLIP with an LM-style encoder; the learned query stream is different from a discrete sort of page regions.
Unlimited-OCR: keep the reference, forget old output
Unlimited-OCR starts from DeepSeek-OCR’s compressed DeepEncoder and 3B MoE decoder, with about 500M parameters active during decoding. Its change is in every decoder attention layer: standard full attention becomes Reference Sliding Window Attention (R-SWA).7
- Permanent referencePrompt and all compressed page tokens
- Recent outputyₜ₋₄, yₜ₋₃, yₜ₋₂, yₜ₋₁
- Generate yₜAttend to both caches
- Reference unchangedSource evidence is not evicted
- Evict oldest outputRemove yₜ₋₄ from the output cache
- Append new outputKeep yₜ₋₃, yₜ₋₂, yₜ₋₁, yₜ
The paper defaults to a 128-token output window; four is only a readable illustration.
Figure 8. A cache-step illustration based on R-SWA. The reference stays; old output leaves.7
Figure 8 separates generation from cache maintenance. Eviction removes output history, not source evidence.
Read the example in two phases. While generating , the query reads the entire permanent reference cache and the four recent output tokens. After is generated, the oldest output token is evicted and is appended. The reference cache does not move.
For a generated token at step , R-SWA exposes two kinds of memory:
is the complete fixed prefix—the prompt and compressed visual tokens—and remains visible throughout generation. contains only the most recent output tokens. Therefore the decode-side KV cache stops growing after tokens, while visual evidence is never evicted. Equation (3) counts cached positions per attention layer, not memory bytes or model weights. It is different from ordinary sliding-window attention, which could also push the source image out of view.
This mechanism targets a different latency problem from GLM-OCR’s MTP or HunyuanOCR’s DFlash: those methods try to emit several tokens per target-model step, while R-SWA bounds how much past output each step must store and attend to. The released model supports a 32K context and single- or multi-page parsing through Transformers, vLLM, and SGLang.46
“Unlimited” is the design direction, not a literal bound. For a fixed visual prefix, R-SWA bounds cache growth with generated length. But total cache is still , and grows as more page images are added. The report’s 40+ page results use a small in-house benchmark, while the released model remains constrained by its 32K context. Treat the title as an aspiration toward long-horizon parsing, not proof of arbitrary-length PDF support.7
How to read the authors’ figure below: each row is a query position and each column is a key/value position it could read. Blue cells are the permanent reference prefix. Pink cells are generated-output history. In full attention, the pink area grows into a triangle; in R-SWA, it becomes a fixed-width diagonal band. In the R-SWA panel, white cells between the blue block and that pink band are old output that has left the cache—not missing document evidence. White cells to the right are future output positions excluded by causal decoding.
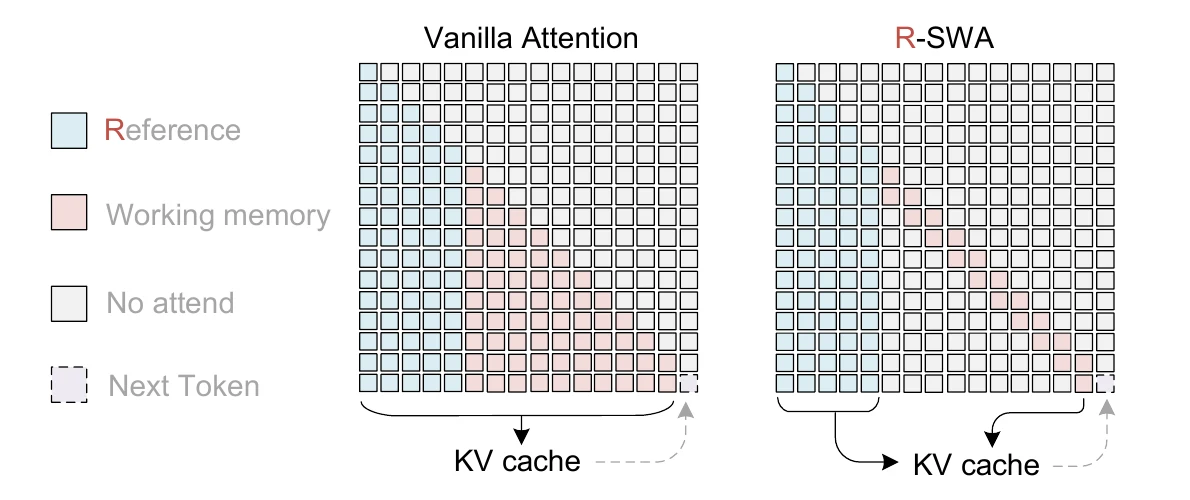
Figure 9. Unlimited OCR Works, Figure 1, arXiv v1, page 1; figure excerpt, CC BY 4.0.745
Figure 9 shows the same distinction as an attention matrix: a permanent reference block plus a moving output band.
Unlimited-OCR 2: bound attention and resident pages separately
The October 27 release addresses the cost left open by R-SWA: even after old output is evicted, every new token still reads all page references. Version 2 retains the DeepEncoder/MoE backbone and adds Sparse Reference Sliding Window Attention (SR-SWA). Its Page Gate restricts eligible visual blocks by page; Token Sieve scores block summaries and selects a fixed top-k set. Attention combines those selected blocks with a local token window. Selection is trained through a routing bias in the attention logits, rather than a separate dense-attention distillation objective.8
- All page referencesThe visual prefix grows with input pages
- Recent output windowOld generated tokens leave the cache
- Page GateRestrict eligible visual blocks by page
- Token SieveChoose a fixed number of scored blocks
- Attend locally and remotelySelected visual blocks plus recent tokens
A bounded attended set does not by itself bound all stored page KV.
- Process active chunkOnly a bounded set of pages is resident
- Reuse boundary contextOne shared page and a retained text tail
- Release inactive page KVContinue into the next overlapping chunk
Cross-chunk continuity is retained context, not unrestricted access to the whole book.
Figure 10. Independent synthesis of the two controls in Unlimited OCR Works 2: sparse access and page-chunk residency.8
Figure 10 separates how much a query attends to from how much source KV remains in memory. The report’s second mechanism processes overlapping page chunks, reuses the shared boundary page and a text tail, and releases inactive page caches. This is what bounds resident visual memory; sparse attention alone does not. Total processing still grows with document length.8
The authors report a peak KV reduction from 47.00 GB to 1.77 GB in their single-sequence chunking comparison. Their separate 7× per-step speedup versus full attention is measured at the hundred-page scale in Gundam mode, batch 3, with 1,024 generated tokens per page. These are different experiments, not an end-to-end speed-and-memory guarantee for any PDF.8
Official weights and a customized SGLang path are available. The deployment notes still identify prefill memory growth and a page-window tradeoff: smaller windows can weaken cross-page merging. The report itself says sparse access does not preserve all global document information, including heading hierarchies. Long transcription and whole-document understanding remain different requirements.847
HunyuanOCR-1.5: one model, long context, faster decoding
HunyuanOCR-1.5 retains the family’s end-to-end path: native-resolution Hunyuan-ViT → adaptive MLP connector → Hunyuan-0.5B decoder. Version 1.5 raises the maximum image resolution from 2K to 4K and the context window to 128K so the same model can handle document parsing, text spotting, extraction, QA, translation, and multiple images.31
What “native resolution” means. The original HunyuanOCR report gives the concrete lineage: Hunyuan-ViT is an approximately 0.4B visual encoder built on SigLIP-v2-400M. Its adaptive patching preserves the input aspect ratio, and all resulting patches pass through global ViT attention.48
This differs from a conventional ViT pipeline that resizes every image to one fixed square and therefore produces the same patch grid regardless of source shape. Hunyuan-ViT accepts a variable-height, variable-width grid instead: a long receipt remains tall and narrow, while a square page remains square. Conceptually, for patch size :
Fixed-square ViT:
Native-resolution ViT:
Preserving the page geometry helps retain small-character density, column relationships, and table or chart structure. The resulting number of visual tokens varies with the image; only after global vision attention does the adaptive MLP connector pool and project those features into a shorter sequence for the language model. The connector therefore reduces decoder-side visual tokens, but it does not remove the vision encoder’s cost of processing the high-resolution patch grid.48
This resembles NaViT’s broader variable-resolution, aspect-ratio-preserving principle, which HunyuanOCR-1.5 cites. But the original report does not describe Hunyuan-ViT as simply NaViT: it specifically describes a SigLIP-v2-based encoder with Hunyuan’s adaptive patching and training recipe.4948
“Native” does not mean that every source pixel passes through unchanged or that resolution is unlimited. Images may still be rescaled to a supported pixel budget and rounded to patch-compatible dimensions. HunyuanOCR-1.5 raises that supported envelope to 4K; the inspected image-processor configuration uses 16-pixel patches and a 2× spatial merge. Treat processor pixel limits, vision config fields and the paper’s supported envelope as separate contracts. The downstream Hunyuan-0.5B uses XD-RoPE to assign text, height, width, and time coordinates to the resulting multimodal sequence.3150
Its decoding addition is DFlash. A separate 90.7M, five-layer block-diffusion draft model proposes up to a block of candidate tokens in one parallel pass; the frozen target model verifies the block and accepts the longest valid prefix. This preserves the target distribution while spending otherwise idle compute to reduce sequential steps. The authors report 6.37× Transformer and 2.14× vLLM speedups in their setup; gains depend strongly on output length, regularity, batching, and serving conditions.31
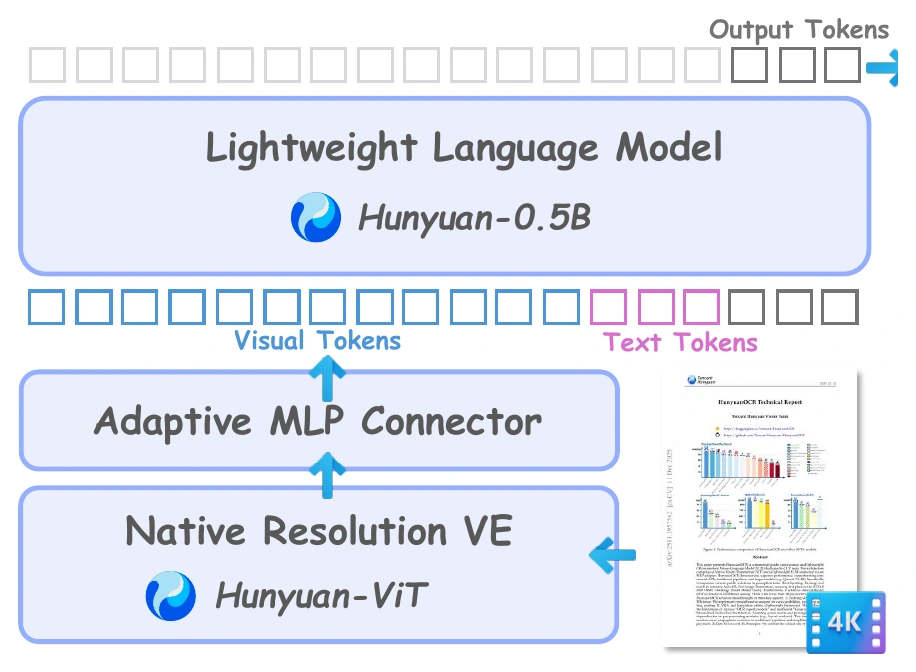
Figure 11. HunyuanOCR-1.5, architecture panel from Figure 1, arXiv v2, page 4; cropped to omit task examples, CC BY-SA 4.0.3145
Figure 11 keeps native visual encoding and decoder-token compression separate. The connector cannot erase upstream vision cost.
LightOnOCR-2: optimize data and the localization objective
LightOnOCR-2 is a 1B end-to-end specialist built around distilled document training data. The revised report expands scans, scientific pages and French content; introduces image bounding boxes; and uses reinforcement learning with an intersection-over-union reward for localization. Checkpoint averaging and task arithmetic produce distinct quality, speed and bounding-box variants. Do not treat one variant’s localization behavior as a property of every checkpoint.32
Current release check. The official catalog also lists LightOnOCR-3 in
0.8B, 1B and 4B variants. The 1B retains the previous architecture; 0.8B and 4B
use Qwen3.5. Its grounding mode adds typed boxes, image descriptions and
chart-to-table data; transcription mode remains distinct. The card limits
usage to the empty prompt or grounding, rather than arbitrary instructions.
This is documented capability, not an independently measured accuracy claim.33
Current model family · Version 2 report · Model family
Nemotron Parse 2.0: encoder–decoder attention is still useful
NVIDIA’s sub-billion-parameter parser combines a C-RADIO vision encoder, convolutional compression and a ten-block mBART decoder that cross-attends to visual features. The model emits text, element classes, reading order and locations. Its expanded vocabulary and data target multilingual content, handwriting and chart-to-table conversion.34
This is a useful counterexample to treating every document VLM as a decoder-only model with visual prefix tokens. Its separately archived auxiliary prediction head is not loaded by the standard checkpoint or inference examples. Do not infer an MTP serving speedup from the existence of that training head.34
Nemotron 3.5 Parse: inspect the attention path and inference passes
The October 17 release changes the version-specific lesson. Its approximately 0.631B model combines C-RADIOv4-SO400M, sequence compression and a ten-layer mBART causal visual-prefix decoder. This is distinct from the cross-attending Parse 2.0 described above. Its trained one-step MTP head is included in the checkpoint; ordinary Transformers generation and the vLLM plugin’s one-token speculative path are different serving contracts.28
One pass parses the page. Two passes refine table/chart crops selected by that parse; three add a separate detection request and refine the union of regions. More work can improve the authors’ ParseBench result while reducing throughput. Their merge retains differing page/crop alternatives, and the reported scores include those alternatives. Test a resolved downstream representation as well as that benchmark output. The model card, pipeline and runtime must be pinned together; its results do not establish one latency for every serving path.28
Chandra OCR 2: separate the open model from the service
Datalab’s released Chandra OCR 2 converts pages into Markdown, HTML or JSON with layout information. Its configuration uses a Qwen3.5-style architecture; the published open-model comparison counts 4.5B inference parameters under its own counting convention. Configuration type alone does not establish a particular base-checkpoint initialization.3536
The open checkpoint and the hosted product have different boundaries. Datalab’s current Convert service names Chandra 2.5, with fast, balanced and accurate modes and optional word boxes. Its service results cannot be assigned to the public Chandra OCR 2 weights. The latter’s code is Apache-2.0, while its weights have modified OpenRAIL-M commercial conditions. Inspect the chosen artifact’s terms and the complete serving path.3551
B. Layout-first and region-routed parsers
These systems use explicit page decomposition. The first stage simplifies the recognizer’s job and enables parallel crops, but it also creates an error boundary: content missed, merged, or misordered upstream may be unrecoverable.
MinerU2.5: global layout, then native-resolution crops
MinerU2.5 is a 1.2B Qwen2-VL-style model with a 675M NaViT visual encoder, a 2×2 pixel-unshuffle patch merger, and a 0.5B Qwen2-Instruct decoder. It first resizes the whole page to 1036×1036 and predicts layout boxes, then returns to the original image and recognizes selected crops at native resolution.27
The design separates two different visual needs: layout depends on global geometry, while transcription depends on local pixels. It saves high-resolution compute on blank margins, but a missed first-pass region cannot be repaired by the second pass.
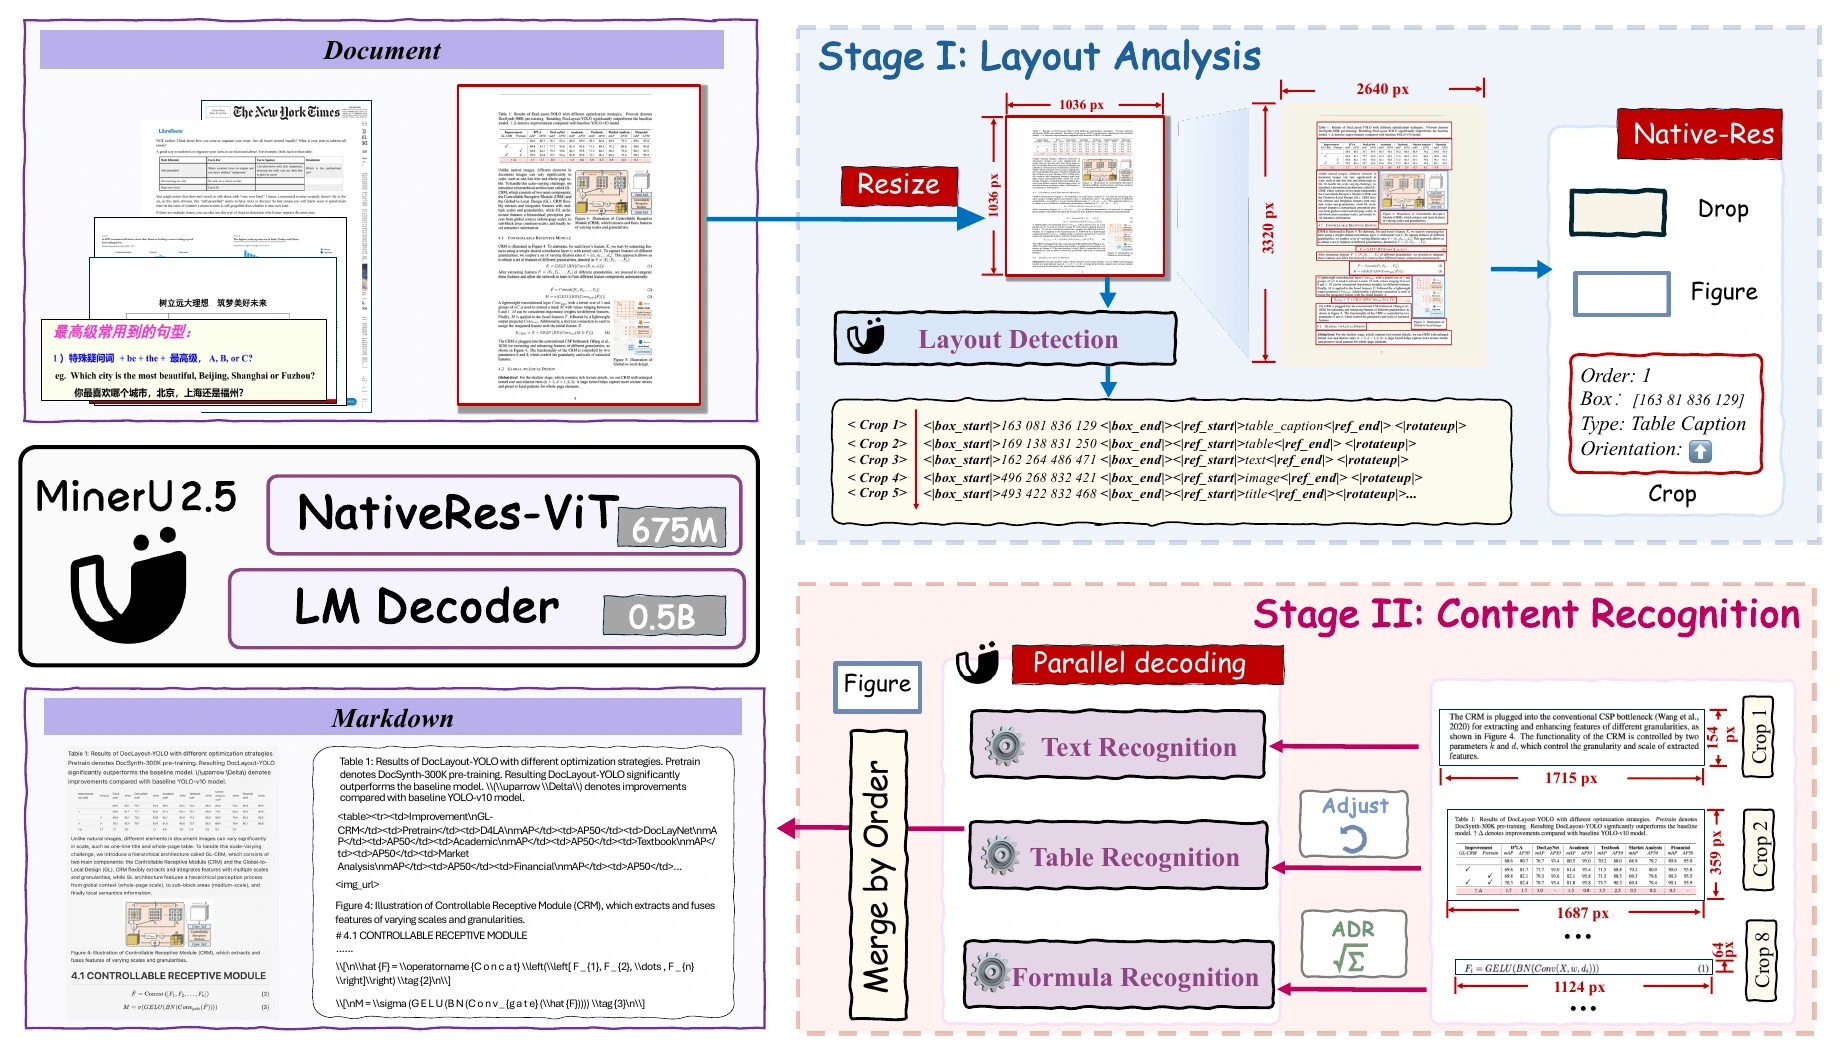
Figure 12. Global layout, local detail. Niu et al., MinerU2.5, Figure 2, arXiv v2, page 7; figure excerpt reproduced for technical review, not MIT licensed.2745
Figure 12 shows why layout recall matters: a crop never selected cannot be transcribed in the second stage.
MinerU2.5-Pro: improve the data engine, retain the architecture
The Pro report retains the 1.2B architecture but scales its corpus to 65.5M samples. Diversity and difficulty sampling, heterogeneous expert consensus, and rendering-based verification refine the supervision. Training proceeds through pretraining, hard-sample SFT and GRPO. The important contrast is with uniform data scaling: target the errors the current model still makes.9
The MinerU application has its own version history and now documents a 4.0 software workflow. That is not evidence of a new “MinerU4” neural architecture. Its repository license adds conditions to an Apache-based license; inspect software and checkpoint terms separately before adoption.52
The PaddleOCR family and its current VL model
Version check · October 11, 2026. PaddleOCR-VL 1.6 is the flagship VL version shown in the inspected official PaddleOCR repository. It belongs to a broader family that also includes modular PP-OCR text detection/recognition, PP-Structure document structure, PP-ChatOCR document understanding, preprocessing, table, formula, seal, and deployment pipelines.53
PaddleOCR-VL 1.6 is a two-model parsing system. PP-DocLayoutV3 performs layout analysis and multi-point localization, then PaddleOCR-VL-1.6-0.9B recognizes text, tables, formulas, charts, and seals using a native-resolution visual encoder, adaptive MLP connector, and ERNIE-4.5-0.3B decoder. Post-processing assembles Markdown or JSON and supports cross-page table and heading refinement.10
The important version detail is that 1.6 retains the 1.5 architecture. It mines three kinds of residual weak regions—checkpoint/perturbation-fragile, coverage-sparse, and unreliable-supervision—then retrieves or relabels nearby data with expert consensus and judge-and-refine. Training proceeds through CPT → hard-sample SFT → selected-data GRPO. In the authors’ OmniDocBench v1.6 ablation, most of the gain comes before RL: 94.93 at the 1.5 checkpoint, 95.62 after CPT, 96.25 after SFT, and 96.33 after RL.10
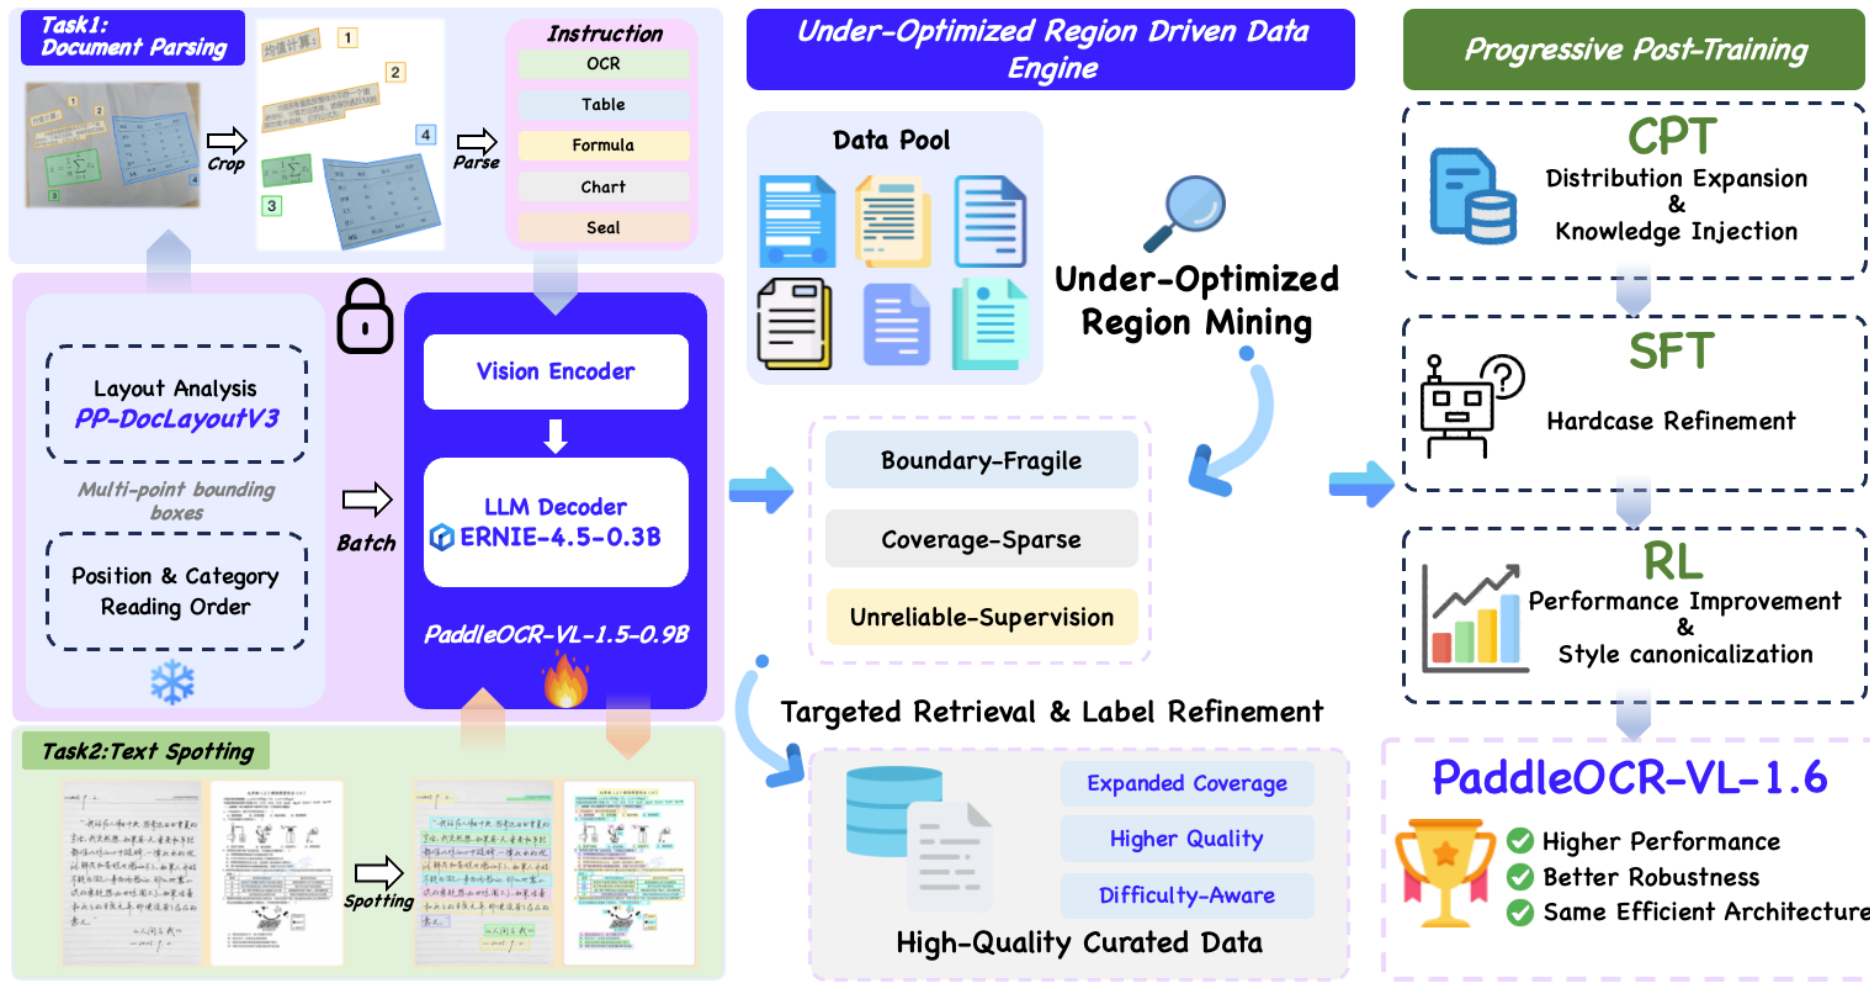
Figure 13. PaddleOCR-VL-1.6, Figure 2, arXiv v1, page 5; figure excerpt, CC BY 4.0.1045
Figure 13 makes the data engine visible alongside the retained architecture. The upgrade is not simply a larger backbone.
GLM-OCR: compact region recognition with multi-token heads
GLM-OCR combines a 0.4B CogViT encoder, lightweight connector, and 0.5B GLM decoder for 0.9B total parameters. For page parsing, PP-DocLayout-V3 finds and crops regions, which the core model recognizes in parallel before merge and post-processing restore structured Markdown/JSON. For key information extraction, the full page and schema prompt can go directly to the core model without explicit region cropping.11
Its distinctive decoding mechanism is shared-parameter multi-token prediction (MTP). Auxiliary heads learn different future offsets; the model is trained for ten tokens per step and averages 5.2 generated tokens per step in the report’s inference setup. Unlike Hunyuan’s external draft-and-verify model, MTP is built into the decoder. The authors report about 50% throughput improvement, while also acknowledging detector error propagation and difficult cross-page or multi-column reading order.11
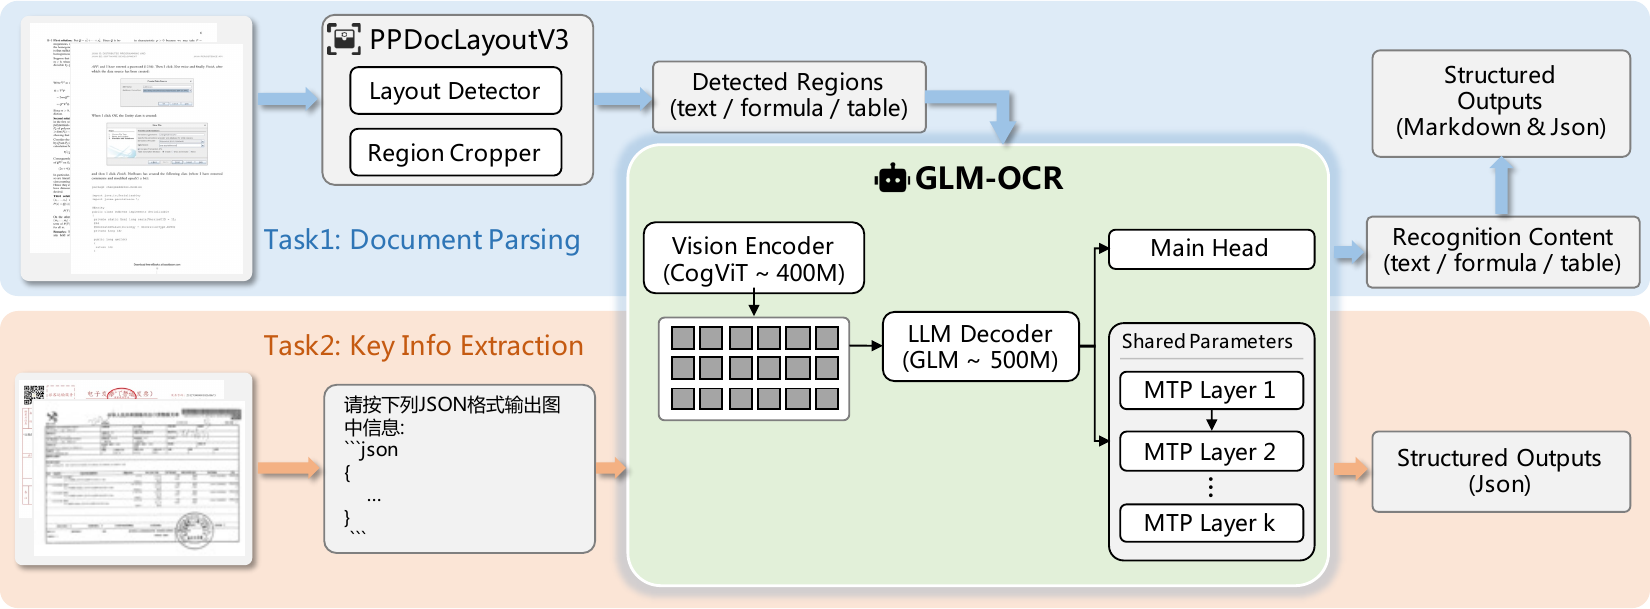
Figure 14. GLM-OCR, Figure 2, arXiv v2, page 4; figure excerpt, CC BY 4.0.1145
Figure 14 separates layout-routed parsing from direct schema-conditioned extraction.
MiniCPM-OCR 1.0: distinguish the recognizer from the parser
MiniCPM-OCR 1.0 is a released 1.3B recognition model combining a SigLIP vision encoder with a Qwen3.5 language backbone, specialized from the MiniCPM-V 4.6 family. Its document SDK supplies the rest of the parser: render PDF pages, run PP-DocLayoutV3 for regions and reading order, recognize crops concurrently, then assemble Markdown, HTML tables and LaTeX. Chinese and English are its primary languages. Direct schema-conditioned KIE is a separate path: image and requested fields go straight to the recognition service.12
This division matters when measuring size and speed. The 1.3B label excludes the layout detector, and page concurrency is different from concurrency among regions within a page. DSpark is optional decoding acceleration with a matching draft artifact; ordinary recognition does not require it. The authors report 1.217 pages/s over all 1,651 OmniDocBench v1.6 images on an RTX 5090, at image concurrency 1 with each system’s official accelerated SDK. Their reproduction guide leaves complete commands and logs for the separate 55% DSpark improvement pending. Neither number is a universal hardware requirement or an independently reproduced result.54
The useful architectural addition is the pairing with a separate verifier, MiniCPM-OCR Jev. Recognition produces a candidate; verification evaluates that candidate against its source. Both checkpoints are released under Apache-2.0.122
OXR-1.0: make layout replaceable, retain recognition and order
OXR uses a separate, pluggable layout model. The OXR network then handles content recognition and reading order as two branches, allowing a domain’s region taxonomy to change without assigning recognition to a different model. Its released implementation uses a SigLIP2/NaViT-style visual encoder and a Qwen3 decoder. A learned visual vocabulary maps soft visual-token distributions into embedding vectors for the language model; it is more specific than an ordinary linear projection of image features.13
The advertised size is 1.3B, while the inspected Hub metadata lists about 1.53B stored BF16 tensor values for the recognition checkpoint. Stored tensor values are not an independently counted trainable-parameter total, and the layout network is separate. Use the artifact and complete pipeline when budgeting memory.13
Its recursive self-improvement (RSI) is a post-training data loop. The official diagram uses a general VLM to classify predictions, compares multiple rollouts for disagreement, groups attributed errors, and generates new image–label pairs matching reference styles. This describes targeted training data construction, not automatic learning from every production document. A formal report was still marked forthcoming at inspection, so the evidence here is the release documentation and implementation, not a paper-level ablation of RSI.13
Weights are public, but the license is Apache-2.0 with additional OXR terms, including commercial thresholds, service attribution and a competing hosted-API restriction. Public weights do not imply unrestricted commercial use.37
Surya OCR 2: share recognition tasks without merging every stage
Surya OCR 2 uses a roughly 650M Qwen3.5-style VLM for recognition, layout and table tasks. Prompts select layout JSON or full-page HTML behavior. Text-line detection remains a separate small model, so “one shared VLM” does not mean that every stage or dependency disappears. The surrounding package supplies reading-order and table interfaces as well as recognition.38
This is a useful modular option beside full-page converters. Test whether the selected prompt and wrapper preserve the granularity your application needs, especially table relations and region identity. Code and weights have separate terms: the code is Apache-2.0, while the weights use a modified OpenRAIL-M license with commercial conditions.38
HPD-Parsing: parallelize the output tree
HPD-Parsing attacks the serial generation bottleneck differently. A main layout branch establishes global structure and dynamically forks local content branches that decode concurrently. Progressive multi-token prediction reduces steps inside each branch. Unlike independent crop calls after an external detector, the model’s decoding process coordinates the branching.39
Official usage and model link · Report
The documented runtime is a customized vLLM build supporting request forking and P-MTP. Parallel decoding is therefore a model-plus-runtime property, not something a generic Transformers loader automatically provides. Peak token throughput is not document latency at your batch size.39
MinerU-Diffusion: change the target decoder, not just its draft
The March 2026 report uses parallel block diffusion for document generation, with uncertainty-aware curriculum learning and inverse-rendered data. Its reported decoding acceleration is conditional on the tested setting; it is not a guarantee for end-to-end ingestion.40
This differs from Hunyuan’s DFlash: DFlash proposes tokens that an autoregressive target verifies. MinerU-Diffusion changes the target generation method itself. The report is inspected; checkpoint availability was not verified in this review.4031
C. Change the supervision or the output language
The next frontier is not only a better visual backbone. Some models change what counts as a correct parse or expand what a parser is expected to emit.
olmOCR 2: executable document tests as rewards
olmOCR 2 starts from Qwen2.5-VL-7B-Instruct, fine-tunes on 267,962 pages, and then applies GRPO on 2,186 synthetic pages with 30,381 HTML-derived binary tests. Each page produces 28 completions; tests check content presence and absence, reading order, table relations, formulas, and repetition.14
For output and tests, the main reward is
This is more semantically tolerant than raw edit distance: equivalent table serializations can pass while text in the wrong order fails. But tests only reward properties they encode, and the paper’s benchmark is English-only.
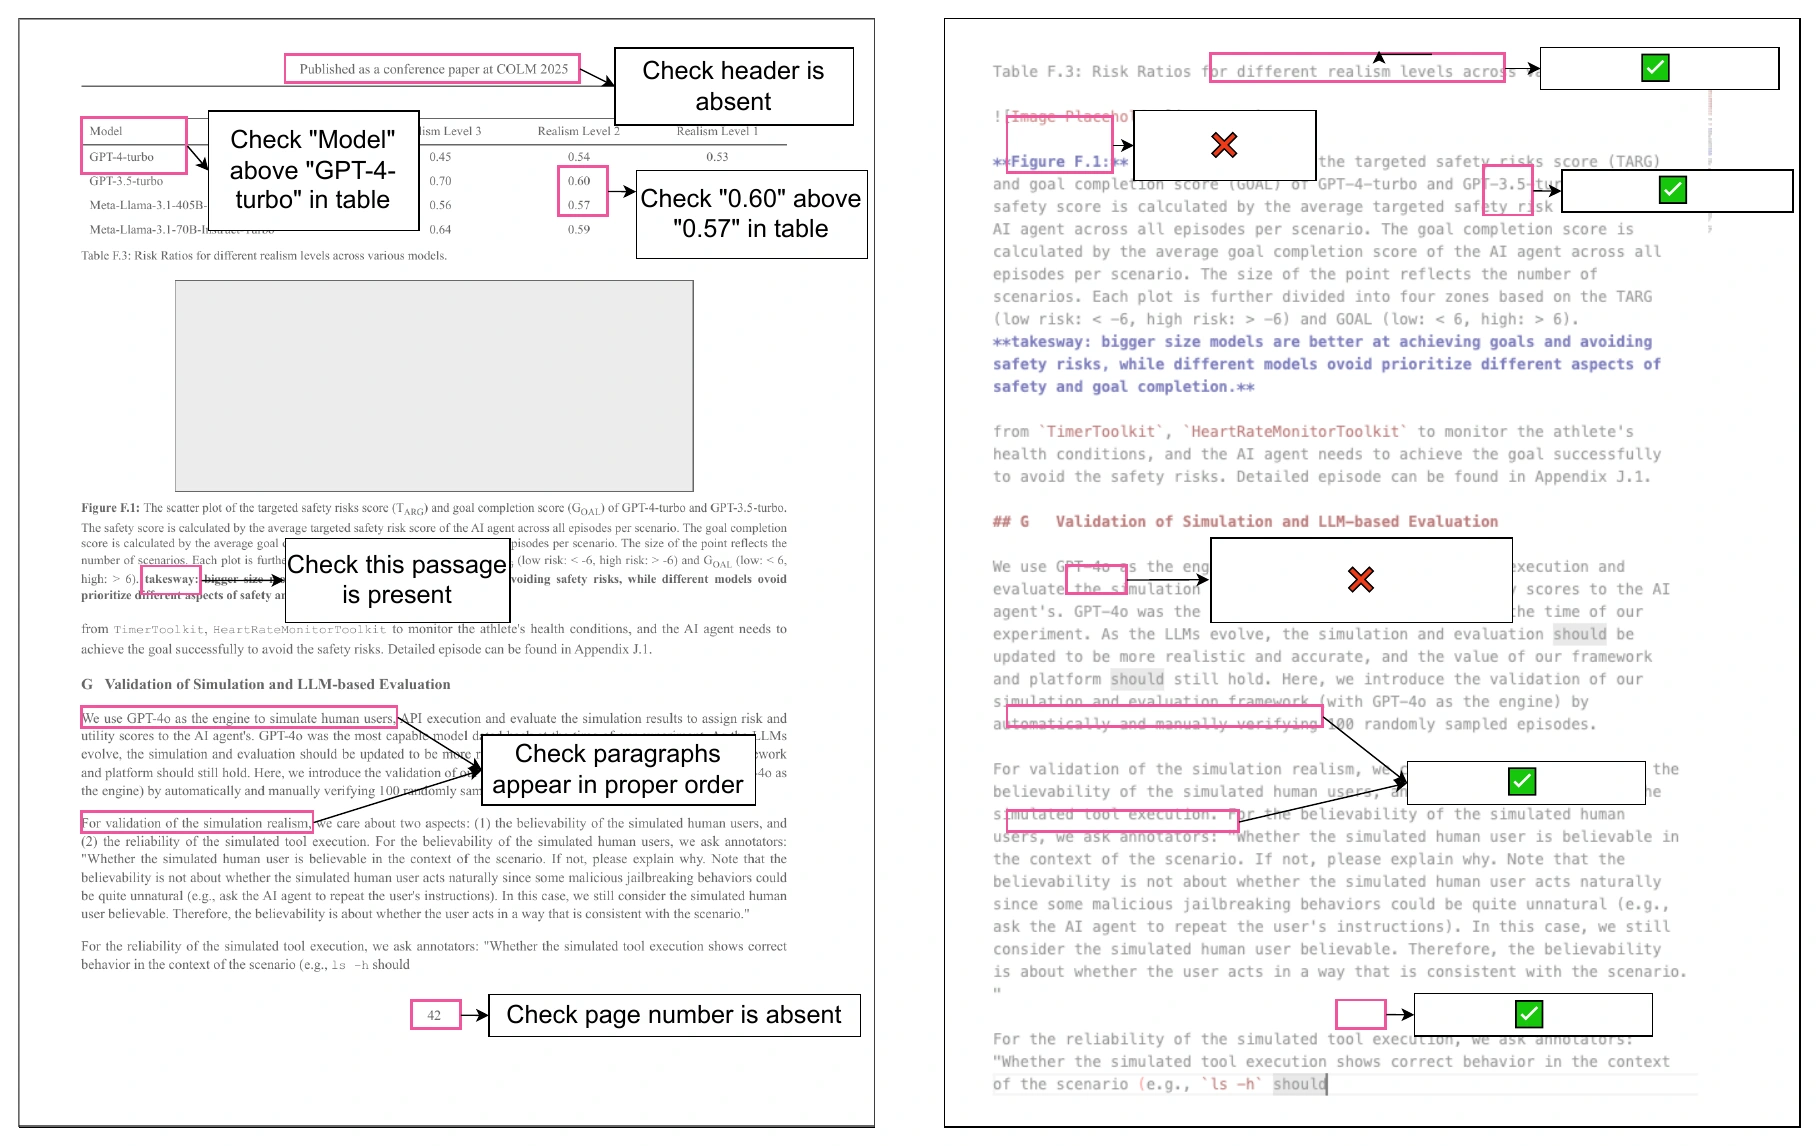
Figure 15. Executable tests score generated text. Poznanski et al., olmOCR 2, Figure 4, arXiv v1, page 6; figure excerpt, CC BY 4.0.1445
Figure 15 checks selected document properties, not exact serialization equality. Unspecified properties can still be wrong.
The rendered HTML is the canonical source for each synthetic training image. If a teacher changes the original document while rebuilding it as HTML, the synthetic image and tests can still be internally consistent. That does not prove faithful copying of the original. The reward above is the main test component, not the complete GRPO objective or every auxiliary reward.14
The release also changes the base model, prompts, image settings, retries and checkpoint merging. Its overall benchmark gain should not be attributed to RL alone without a controlled ablation.14
dots.mocr: treat graphics as programs, not leftover pixels
dots.mocr extends the output boundary beyond text-centric parsing. Its scratch-trained 1.2B high-resolution encoder accepts up to roughly 11 million pixels; a connector feeds a Qwen2.5-1.5B base decoder. The generated sequence contains ordered typed regions , where payload can be text, table markup, LaTeX, or renderable SVG for charts, icons, diagrams, and UI elements.17
The current release is not literally “parse everything in one pass.” Full-page text parsing and region-level image-to-SVG decoding are task-conditioned separate passes. SVG also introduces a different evaluation problem: many programs can render the same picture, so render fidelity and structural checks matter more than exact code match.
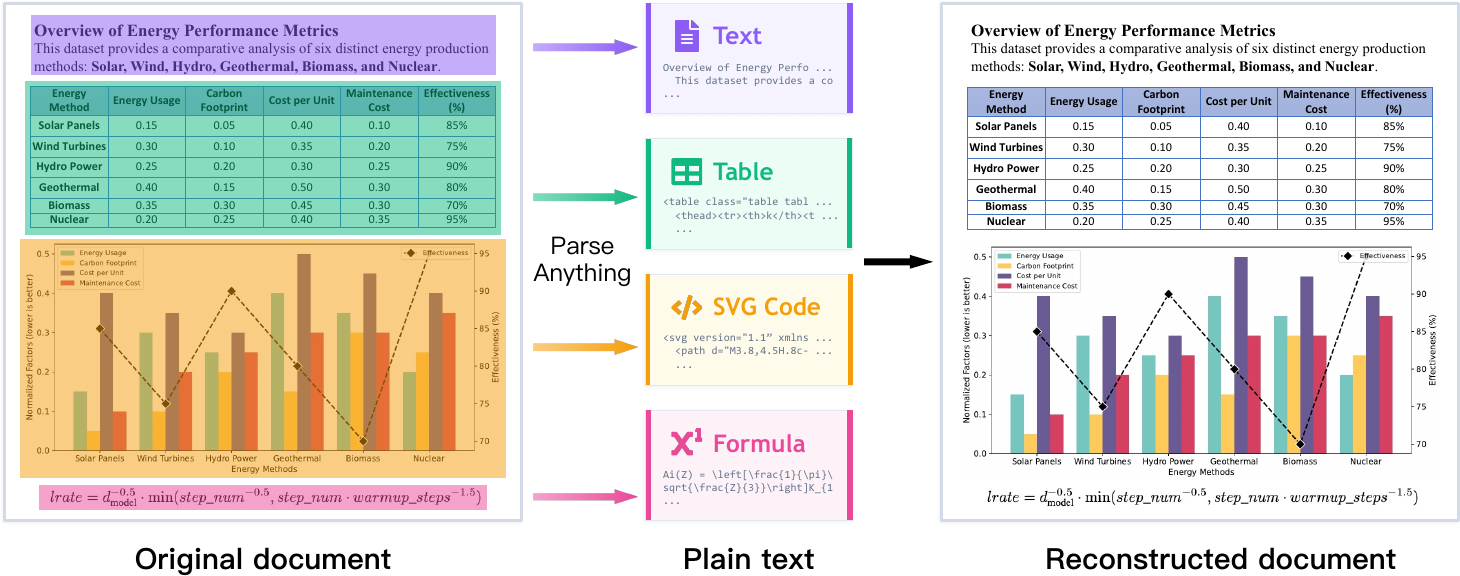
Figure 16. dots.mocr, Figure 1, arXiv v2, page 2; unchanged figure excerpt, CC BY-NC-ND 4.0.1745
Figure 16 expands the output contract to graphics code. Photos and graphics with no compact program remain raster content.
TeleOCR: geometry remains a frontier
TeleOCR adds deformation-aware learning, adaptive sampling for complex layouts and content/structure decoupling for formulas and tables. The current September revision uses the TeleOCR name; earlier indexing used NaviDC. Its reported 78.41 PureDocBench score is a later author result, illustrating why the original study’s roughly 74 score is not a current ceiling. Cross-report scores still require matching evaluator and dataset versions.41
Xiaomi-OCR-0: connect reading to understanding
Xiaomi-OCR-0 starts from Qwen3.5-0.8B and trains one compact model for parsing, key-information extraction and OCR-centric visual QA. Its report appeared September 28; the official repository records the weight release on September 30. Official checkpoints are available, correcting this guide’s earlier unverified availability status. The model and code carry Apache-2.0 terms; community quantized conversions are separate artifacts whose benchmark parity is not established here.1542
The main contribution is the relationship between label quality, spatial anchoring and understanding supervision. Its approximately 170M-sample corpus mixes regions, pages and understanding tasks. That is not 170M distinct pages, and it is not a text-token count.15
Build labels, then decide what to learn from them. A layout detector supplies regions to heterogeneous expert recognizers. The pipeline ranks experts by their mean pairwise agreement, keeps the top three, and selects the most central candidate among that trio. Uncertain cases undergo render-guided refinement and return to the expert pool for another consensus check; selected unresolved cases receive human review. This is not an exhaustive search over every possible expert triplet. Agreement is also not a calibrated probability of truth: correlated experts can share an error.15
Mining keeps two signals distinct: expert agreement estimates label reliability, while the student’s consistency and errors indicate learning need. Coverage-driven synthesis fills missing patterns; failure-driven synthesis targets verified weaknesses. A frozen, source-group-separated validation set guides recipe revisions but stays out of training and linked synthetic derivatives. Because that set guides development, a separate sealed test remains necessary for an unbiased final estimate.15
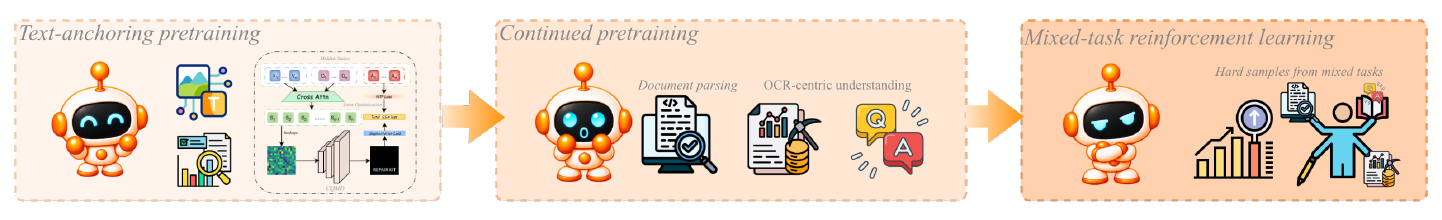
Figure 17. Xiaomi-OCR-0 training recipe. Chen et al., Figure 3, arXiv v1, page 9; figure excerpt, CC BY 4.0.1545
Figure 17 separates three training stages:
- Q-Mask text anchoring. A query-conditioned mask decoder adds spatial supervision alongside answer-token prediction. The mask decoder is removed before continued pretraining; it is not a required segmentation head in the deployed OCR path.
- Continued pretraining. Parsing, KIE and VQA share an autoregressive instruction format. The base model’s single multi-token prediction head is jointly trained, which does not establish default inference speedup.
- Mix-RL. Task-specific rewards score text similarity, table structure, formula rendering, field extraction and QA. The parsing reward also matches page elements; invalid format and length receive explicit treatment. A fluent answer alone is not the objective.15
What do the experiments establish? The authors report 96.83 on OmniDocBench v1.6, 95.24 on Real5 and 87.94 on Wild. These headline parsing results use PP-DocLayoutV3 → crop recognition → page assembly; the 0.8B label does not include that detector. Direct whole-page parsing, KIE and VQA are different operating paths.1542
The understanding-transfer ablation is more instructive than the ranking. Adding understanding tasks slightly hurts an early region-only model on OmniDocBench v1.6 (93.594 → 93.264), then helps after page-level parsing training is established (94.941 → 95.580). This supports a curriculum-dependent benefit, not “more tasks always help.” Its separate Q-Mask and Mix-RL gains use different training baselines and cannot simply be added. On the report’s 1,655-image in-house KIE set, average accuracy is 59.09%, including 45.93% on addresses: high parsing scores still leave substantial extraction failures.15
WeVisDoc: use residual errors to allocate training
WeVisDoc-2B and 4B keep a Qwen3-VL-based end-to-end parser and change its data curriculum. The two stages are training stages, not a layout→recognition inference pipeline. Stage I expands semantic, structural and appearance coverage, including degradations that preserve readable target content. Stage II measures residual errors on a disjoint diagnostic probe within fixed visual–structural clusters. Verified gaps guide new examples and training-token exposure, with broad replay to reduce forgetting.43
The paper carefully distinguishes an under-covered cluster from a measured failure: a group with no local probe evidence has a pooled prior, not an observed error rate. Its 4B model reports 75.54 averaged across PureDocBench’s three tracks and a 4.03-point Stage II gain on the Real Degraded track. Stage II changes data, allocation and total training; that gain does not isolate rebalancing under equal cumulative compute. Official 2B and 4B checkpoints are released.43
OCRia-1: reward associations, not just recovered strings
LlamaIndex’s October OCRia-1 report starts from Qwen3.5-4B and concentrates on merged headers, long tables, chart values and meaningful formatting. The official announcement establishes use inside LlamaParse; a downloadable public checkpoint was not verified. A reported model is not automatically a self-hostable release.1644
Its supervised dataset contains 100,979 pages, combining audited real pages with synthetic documents whose source structure supplies exact targets. Reinforcement learning uses 11,234 pages and 34 reward components, including 12 penalties. Rewards check such properties as whether a value is under its correct header and whether chart values retain their series labels. Reward tests found concrete shortcuts: an empty sequence can appear perfectly ordered, and counting elements without checking their placement can reward wrong output. Correctness needs content, placement and anti-omission checks together.16
The report’s serving result is a system result: a roughly 0.69B DFlash 2 draft, speculative block verification, mixed-precision weights and custom vLLM/kernel work supplement the 4B target. Concurrency and draft acceptance change the speed; a bare 4B checkpoint would not establish that latency.16
Read its benchmark denominators carefully. The reported 87.4/100 ParseBench average covers four dimensions and excludes visual grounding, because OCRia-1 does not emit bounding boxes. The report’s main-table 90.5 olmOCR score averages three table/formula categories, not the official eight-category overall. Appendix D separately reports 83.5 overall at a 1,288-pixel long-side rendering, in a comparison mixing author reruns and identified published baselines. These are author evaluations, not a cross-model ranking reproduced here. Old scans, some multilingual tables and output-budget-limited long tables remain failure cases.16
Youtu-Parsing-Omni: one grounded interface across modalities
Tencent’s October 29 report extends parsing beyond pages. The released 5B model uses modality-specific input stems around a shared perception Transformer, initialized from a text language model, then emits text through a language decoder. Space–time positions and selected audio–video fusion layers connect what is seen with what is heard. OmniSchema represents content and its spatial or temporal evidence in one structured interface.18
Its OmniSchema-Aware On-Policy Distillation (OSAD) trains on student-generated prefixes. A frozen teacher sees the reference parse, while the student does not; content and structure receive different token-level objectives. The teacher refreshes between rounds. “Self-evolving” therefore still depends on reference supervision. The report also says this larger autoregressive model does not yet implement its predecessor’s inference acceleration. Treat it as a broader perception option, with custom Youtu model terms, rather than an automatic throughput upgrade for ordinary PDF OCR.18
The architectural lesson
Choose by the limiting constraint
10 constraints| If the workload is constrained by… | Start by testing… | Inspect this failure boundary |
|---|---|---|
| edge memory or conversion throughput | SmolDocling or another compact converter | compression loss and vocabulary/task coverage |
| dense pages and limited visual-token budget | DeepSeek-OCR family | small text loss, reading order, and compression regime |
| multi-page transcription and growing reference/output memory | Unlimited-OCR 2 or another bounded working-set design | active attention versus resident KV, page-window continuity, global structure and small-text loss |
| auditable region boundaries and parallel serving | MinerU2.5, PaddleOCR-VL, GLM-OCR, MiniCPM-OCR or OXR | detector recall, crop context, merge order and full-pipeline licensing |
| long structured generation latency | GLM-OCR MTP or HunyuanOCR DFlash | hardware, concurrency, acceptance length, output stability |
| semantic correctness beyond edit distance | olmOCR 2-style executable tests | untested properties and synthetic-data coverage |
| diagrams and charts that must remain editable | dots.mocr-style SVG generation | render equivalence, geometry, and code validity |
| compact reading plus direct KIE/VQA | Xiaomi-OCR-0 | detector-inclusive parsing scores versus direct extraction reliability |
| merged table headers, chart values and formatting | OCRia-1/LlamaParse or a structure-preserving parser | hosted access, output contract, grounding and long-output limits |
| review cost or selection among parser candidates | MiniCPM-OCR Jev plus workload calibration | missing regions, invalid scoring status and false accepts at the chosen threshold |
No matching constraints. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
Across the families, the shared pattern is capacity allocation rather than parameter scaling alone: decide which pixels become tokens, which tokens reach the decoder, how many decoding steps are necessary, what structure the output language makes explicit, and which errors the training signal can see.
Extraction is becoming schema-conditioned generation
A common modern extraction path is:
- parse the document into text plus structure;
- supply a JSON schema, field descriptions, examples, or instructions;
- generate typed values;
- enforce structural validity;
- attach each consequential value to a page or region;
- normalize and check it against business rules or external data; and
- abstain or route high-risk uncertainty to review.
Valid JSON is not evidence of a correct value. Stable, high-volume schemas can still favor discriminative models with better latency and calibration. Generative extraction is strongest when layouts and schemas vary or when a field requires language understanding. A practical compromise uses a generative extractor plus a smaller verifier, deterministic rules, or sampled human review.
QA still needs retrieval and evidence
DocVQA established single-page visual question answering with 50,000 questions over more than 12,000 document images.55 Real workloads are often multi-page. MP-DocVQA therefore used hierarchical page representations—select or compress pages before answer generation and identify the supporting page.56
The same idea underlies reliable multimodal RAG: parse evidence-bearing blocks, retrieve documents then pages or regions, answer from the selected visual and textual evidence, return citations, and support “not found.” Long context does not remove retrieval; retrieval also allocates visual compute and creates an audit interface.
Benchmark versions matter. MMLongBench-Doc-V2 corrected 106 annotations and changed the evaluator to semantic equivalence; its authors explicitly state that V2 results are not comparable with published V1 scores.57
Retrieve the page image, not only its transcript
ColPali is an important complementary design. It embeds page images as multiple vectors and uses late interaction between query-token and page vectors. This lets retrieval retain layout and visual evidence that a plain OCR transcript can discard.29
For query vectors and page vectors , its MaxSim matching has the form:
Each query token finds its strongest page match; those matches are summed. This is retrieval, not transcription or answer generation. A practical hybrid can retrieve page images, then supply both the relevant image and typed parsed blocks to an answer model. Multiple vectors also mean more index storage and matching work than one vector per chunk; benchmark retrieval latency, recall and downstream answer quality separately.29
ColPali’s multi-vector approach is one option, not the only visual retrieval interface. The October Nemotron 3.5 Embed release also accepts page images, text or their combination. Its 1B-named variant returns one normalized 2,048-dimensional vector per input; a separate reranker can reorder the retrieved candidates. Its model card gives 1.55B total parameters, another reason not to read a size suffix as a full-pipeline memory budget.58
The design decision is where to spend information and compute: compact dense indexing, token-level late interaction, candidate reranking, then answer verification. Compare recall, index size, retrieval/rerank latency and cited answer quality on the same corpus. A retrieval score does not measure parse fidelity or prove that a generated answer uses the evidence correctly.
See multimodal integration for the underlying vision-language interfaces.
Summarization is a downstream grounding problem
This review does not establish a standard visual-document summarization leaderboard comparable to the parsing benchmarks discussed here. The critical work is preserving section and table structure, retrieving complete evidence, distinguishing observed facts from synthesis, citing pages, and detecting omitted requirements. A good parse does not prove summary coverage, and a fluent summary does not prove factuality.
Evaluation is now a limiting layer
Choose the benchmark by the failure you need to expose. “Document AI score” can mean transcription, spatial grounding, long-document continuity or finding evidence for a question. Those are different experiments.
Which failure is under test?
7 evaluation questions| Task to test | Useful benchmark examples | Boundary to keep visible |
|---|---|---|
| Text and page structure | OmniDocBench; olmOCR-bench5914 | pin task metrics, rendering, matching and evaluator version |
| Structure and grounding | ParseBench1628 | report every dimension; a four-dimension average omits grounding |
| Specific content properties | OmniParseBench60 | tagged pass/fail tests are selected properties, not whole-document correctness |
| Degraded capture | PureDocBench; Real5-OmniDocBench3020 | keep clean, digital and physical conditions distinct |
| Rare expert structures | Dr. DocBench61 | failure-selected challenge pages do not estimate production prevalence |
| Long-document continuity | MarathonDocBench8 | hundred-page transcription is different from whole-document QA |
| Retrieved evidence and answers | MMLongBench-Doc-V2; ViDoRe v35758 | QA and retrieval have different outputs; neither substitutes for parse evaluation |
No matching evaluation questions. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
Public leaderboards can mislead through corpus mismatch, page-level metrics that hide catastrophic field errors, benchmark corrections, contamination, vendor-specific tuning, and a gap between digital pages and real capture. PureDocBench reports 2,580 confirmed errors in 21,353 evaluator-scored OmniDocBench blocks, or 12.08%; this denominator is not every annotated block in the dataset. Real5-OmniDocBench separately reconstructs pages through scanning, warping, screen photography, illumination changes, and skew to expose a persistent physical-capture gap.1920
Dr. DocBench adds expert-domain structures such as chemical formulas, music notation, difficult tables and cross-page relationships. Its failure-based selection is useful as a stress test, but does not estimate your production error prevalence. Combine challenge sets with representative workload samples instead of averaging them into one undifferentiated score.61
Long-document evaluation adds another axis. Unlimited OCR Works 2 introduces MarathonDocBench: 100 documents spanning 103–300 pages, with cross-page text and table continuations. This is an author-created stress test, not a representative sample of all enterprise PDFs. Test page coverage, joins, hierarchy and recovery after chunk boundaries separately from ordinary single-page accuracy.8
OmniParseBench adds a useful October view. Datalab publishes 16,288 pass/fail tests over 2,937 pages from 2,343 documents, with language, structure and capture tags and a recorded derivation for each test. The headline averages text, table and layout family scores; it is not the pass rate of all tests pooled together. Missing layout output also changes which comparisons are defined.6036
Its open scorer makes failures inspectable, but this is a vendor-authored benchmark that also compares the vendor’s own products. Test construction has heterogeneous sources, including model-assisted verification. Deterministic scoring does not make the reference labels infallible, and a test suite cannot reward properties it never checks. Use its slices and released verdicts to form workload hypotheses, then test those on independent documents.6260
Agree on the output before scoring it
Two transcripts can contain every printed word but encode different meaning: a two-row table header flattened into one row can detach a value from its year. LlamaIndex’s Document Parsing Protocol (DPP), working draft 0.1, published October 28, makes such representation choices explicit. Its proposed rules preserve spanning headers in HTML, distinguish blank form fields from missing content, and retain chart data and readable diagram relationships. It grew from ParseBench annotation guidance; it is a vendor-authored proposal, not an adopted interoperability standard.63
The general lesson is to version your own output contract before comparing parsers. Decide which structures, locations and omissions matter, which serializations are equivalent, and whether a benchmark actually scores them. OCRia’s four-dimension ParseBench average, for example, cannot establish its unmeasured visual grounding.16
A production bake-off should use a rights-cleared, stratified sample of the actual workload, including easy pages, rare but expensive layouts, bad scans, handwriting, long packets, and “not present” cases. Keep a sealed test split and measure the losses that matter:
- exact transcription for critical fields;
- reading order, table structure, and header–value association;
- field precision/recall, normalized match, and evidence coverage;
- document-level perfect-pass rate where every required field must be right;
- answer accuracy, abstention, and citation correctness for QA;
- factual consistency and required-fact coverage for summaries;
- straight-through processing rate and review minutes at a fixed quality bar;
- p50/p95 latency, throughput, retries, and fully loaded cost; and
- every metric sliced by document type, language, capture condition, and parser/model version.
Vendor confidence is not automatically a calibrated probability. Estimate empirical error by field and slice, and price false values, missing values, unnecessary reviews, and delays separately.
MiniCPM-OCR Jev: score the candidate against the crop
Jev is a released 2B verifier, trained from Qwen3.5-2B with a binary classification head replacing the language-model output head. It takes three matched inputs: the original region image, candidate OCR text, and an image rendered from that candidate. It returns a 0–1 score for text, table or formula regions. It evaluates existing candidates; it does not transcribe a page or repair a region that every parser missed.2
- Preserve source identityPage, crop, category and reading-order ID
- One or more parsersCandidates must describe the same crop
- Render candidateKeep text, rendering and source paired
- Jev scores the tripleSource image + text + rendered candidate
- Check verdict firstOnly scored means inference completed
- Apply calibrated policyAccept, choose among candidates, retry or review
Keep failed scoring separate from low quality; retain unresolved regions and audit accepted samples.
Figure 18. Proposed integration of the released Jev interface. The routing policy requires workload-specific validation.2
Figure 18 preserves identity across generation and assessment.
The service contract makes an important distinction: only verdict: scored
means model scoring completed. Fixed scores returned for precheck, rendering
or forward-pass failures must follow a failure/retry path, rather than being
interpreted as low-quality OCR. Pin the renderer as well as the model;
fonts, browser and formula/table rendering change the verifier’s input.2
The authors report 93.6 AUROC ×100 on JevOCRBench. That measures how well scores rank correct versus incorrect candidates; it is not 93.6% accuracy or proof that a 0.9 score means 90% correctness. A cross-parser check on the same 200 sampled regions reports AUROC between 91.9 and 93.4, including Xiaomi, GLM and PaddleOCR outputs. It does not establish one threshold for every document distribution.2
For deployment, label representative workload regions, choose a threshold using both accepted-result accuracy and acceptance volume, then test it on independent data. Audit randomly sampled accepted regions too: reviewing only low scores cannot reveal the verifier’s false accepts. Parser and verifier errors can correlate, and a region scorer does not measure page-level detector recall. These are separate production checks, not capabilities established by the benchmark.
Validating a model-based judge
An LLM judge is not ground truth. Published evaluations identify position, verbosity, and self-enhancement biases; agreement on one benchmark does not establish reliability for document extraction or figure summaries.64
A proposed document-specific checklist: define correctness, coverage, and conciseness separately; build a human-reviewed sample across relevant document slices; inspect false accepts and false rejects, not just average agreement. For paired comparisons, swap answer order to check sensitivity. Include fluent but wrong outputs and terse but correct ones. Fix the judge version and rubric when comparing systems, and recheck reliability after either changes.
Separate the measurements: summary rubrics assess the summary; direct QA tests answerability from the supplied representation; RAG adds retrieval and context selection. A downstream gain does not identify which stage improved without additional comparisons. For synthetic training data, judge scores are an intermediate check, not a substitute for held-out model evaluation.
- Source figure or pageHuman-reviewed facts and task scope
- Summary plus structured dataRubric: correctness, coverage and conciseness
- Fixed questions and contextSupply only the summary and chart CSV
- Answer correctnessTest whether the representation preserves needed facts
- Index and retrieveInclude realistic distractors and access rules
- Answer with citationsMeasure retrieval, answers and evidence together
Compare with raw-source and oracle-context baselines to localize regressions.
Figure 19. A proposed evaluation design. Rubric, direct QA and RAG scores are complementary, not interchangeable.
Figure 19 isolates representation, answerability and retrieval. Run each test before interpreting an end-to-end gain.
A dependable production architecture
- Ingest and route. Preserve the source, verify file and page metadata, detect native text, classify and split packets, and route by language, quality, complexity, and governance boundary.
- Parse with evidence. Keep blocks, coordinates, reading order, hierarchy, tables, formulas, figures, source text, and parser version. Flat Markdown is convenient but may discard information needed for review or reprocessing.
- Execute a typed task. Use a schema for extraction, an evidence plan for QA, or a coverage rubric for summarization. Separate observed values from normalization, inference, and arithmetic.
- Validate and abstain. Combine schema checks, ranges, totals, cross-field consistency, master data, grounding coverage, capture risk, and calibrated thresholds. A region verifier can score a matched candidate, but failed scoring and missing detections need separate handling.
- Review by risk. Send people the fields where expected error cost exceeds review cost, with the source crop and reason for escalation—not every page.
- Monitor outcomes. Track input drift, versions, validation failures, corrections, downstream rejection, cost, and latency. Canary changes and keep rollback paths. Track parse completion, dropped regions, truncated output and cross-page joins as well as field errors.
Agreement between two models is not proof: they can have correlated failures. Grounding is not proof either, but it makes a mistake inspectable. Reliability comes from the complete control loop.
For a new parser, record four contracts in the deployment manifest: the model/checkpoint; the SDK, renderer and decoding mode; the output schema and normalization rules; and the evaluation plus acceptance policy. This is a proposed operating practice. It keeps optional draft models, extra passes, changed confidence semantics and revised label sets from silently changing what an “accepted document” means.
Treat document content as data, not authority
A document can contain instructions aimed at the model, including text hidden in a PDF or embedded in retrieved content. Indirect prompt-injection research shows why retrieved data must not acquire the privileges of system instructions.65
The following are system-design recommendations:
- Enforce access rules before retrieval and when assembling evidence. Apply the same rules to crops, summaries, extracted fields and indexes.
- Keep source content separate from tool permissions. A page may suggest an action, but it cannot authorize a write, payment or external message.
- Validate files and sanitize generated HTML or SVG. Do not execute embedded scripts or fetch arbitrary URLs while rendering a parse.
- Define retention, deletion, redaction and outbound-service rules for originals and every derived representation.
Grounded output can still disclose restricted information. Accuracy and authorization are separate tests. See Security & Control.
Product landscape: compare boundaries, not demos
The market contains overlapping layers. Cloud services supply processors and analyzers inside a cloud estate. Workflow suites add operator review, process state and business-system integration. Parser APIs expose conversion or extraction to developers. Pipeline toolkits leave more serving and operations with the application team. A model checkpoint is a component in these layers, not a substitute for their complete contract.
The role labels are an orientation, not exclusive categories. Search a product, role or capability, then compare the adoption question in the same row.
Products and their boundaries
14 products| Product and role | Documented boundary | Adoption question |
|---|---|---|
| Google Cloud Document AI66 Cloud service |
OCR, layout, extraction, classification and splitting processors | which processors, region and validation workflow fit the task? |
| Azure Document Intelligence + Content Understanding6768 Cloud service |
document models plus generative multimodal analyzers; GA and preview APIs coexist | which API, analyzer, region and model deployment are in the service contract? |
| AWS Textract + Bedrock Data Automation69 Cloud service |
forms/tables/query primitives plus multimodal standard or custom outputs | what orchestration and review remain outside each service? |
| ABBYY Vantage70 Workflow suite |
skills, manual review, connectors, cloud and self-hosted deployment | what process design, integration and deployment contract are required? |
| UiPath Document Understanding / IXP7172 Workflow suite |
annotation, classification, extraction and validation inside the automation platform | which Helix/generative features and deployment-region settings apply? |
| Rossum73 Workflow suite |
field/document automation using confidence and built-in, historical or custom checks | which business checks and exceptions permit automatic export? |
| Instabase AI Hub74 Workflow suite |
no-code apps, configurable flows and human review | is the flow editor’s Enterprise single-tenant boundary acceptable? |
| Mistral Document AI / OCR 4.175 Parser API |
OCR, paragraph boxes, structural labels, confidence and annotations | how will validation, review and model lifecycle be managed? |
| LandingAI ADE7677 Parser API |
separate Parse, Extract, Classify, Section and Split interfaces | which model generation, tier and output contract does each operation use? |
| LlamaParse / OCRia-144 Parser API |
hosted parsing emphasizing table relationships, chart data and formatting | does the chosen mode provide required grounding and review evidence? |
| Datalab / Chandra 2.5 Convert51 Parser API |
managed conversion modes, structured output and optional word boxes | how do the service mode and add-ons differ from the public OCR 2 weights? |
| Reducto78 Parser API |
structured parsing and schema extraction with optional field citations | how will parse omissions, review and multi-operation cost be tested? |
| Unstructured79 Pipeline toolkit / service |
connectors, partitioning, schema extraction, enrichment, chunking and embedding | who operates the pipeline and verifies extraction/retrieval quality? |
| Docling ecosystem80 Pipeline toolkit |
local conversion, typed document representation, exports and model integrations | who owns deployment, chosen model terms and the downstream workflow? |
No matching products. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
Product boundaries were rechecked October 31 against first-party documentation. This map establishes documented capability, not independent quality or ease of adoption. Marketing service results, a downloadable checkpoint and an SDK’s output are separate evidence. Datalab’s managed Chandra 2.5 and open Chandra OCR 2 are one concrete example.5135
Version stability is a product requirement
The current LandingAI notice is stronger than an upcoming migration: all plan tiers moved on October 8, 2026. Old DPT-2 and Extract Gen1 snapshot names now execute the newer September snapshots. Keeping the old request string does not keep the old model. Mistral separately marks OCR 4.0 deprecated and recommends 4.1. These are documented lifecycle behaviors, not service tests performed here.7675
Maturity also belongs to a specific interface. Azure Content Understanding’s
2025-11-01 API is GA, while 2026-06-01-preview features retain preview terms.
Its October async PDF/TIFF limit is 2,000 pages; synchronous analysis remains
limited to five. Service capacity is not proof of cross-page understanding.
UiPath similarly documents GA Helix 2.0 with region-dependent defaults, while
some complex-layout generative extractors remain preview features.687271
Record provider transitions and inspect observed outputs. Canary sets should cover omitted fields, geometry, formatting and confidence semantics. Keep request configuration, resolved model/version metadata where available, response schema, raw output and the acceptance decision. Re-test after either the provider’s implementation or your normalization changes.
Why the price-per-page table is usually misleading
Vendors meter different objects: pages, documents, characters, tokens, fields, workflow operations, service tiers, add-ons, or human tasks. A parser API and a full IDP suite also deliver different boundaries. Compare instead:
Report this by document slice. A small set of difficult pages can dominate both cost and risk.
A practical selection framework
A starting point for each workload
9 workloads| Workload | Sensible starting class | Why |
|---|---|---|
| Clean digital files for search or RAG | native-text baseline with Docling or Unstructured; compare image retrieval on visual pages | preserve cheap text while testing what layout and images add |
| Visually complex PDFs feeding an AI app | API-first specialist or self-hosted document VLM | strong page structure and developer integration |
| Stable high-volume forms with strict fields | hyperscaler custom/prebuilt model or enterprise IDP | repeatability, calibration, validation, and review dominate novelty |
| Invoices, orders, and shipping workflows | enterprise IDP; include relevant cloud processors in the bake-off | operator process and ERP validation are central |
| Mixed packets in an existing cloud estate | corresponding hyperscaler, benchmarked against specialists on hard slices | identity, storage, region, and procurement integration reduce complexity |
| Strict private or on-premises boundary | open specialist stack or explicitly private enterprise offering | deployment and outbound dependency evidence becomes a hard constraint |
| Ad hoc multi-document QA or summarization | visual/text retrieval, optional reranking, then a grounded answer model | retrieval, representation and answer fidelity need separate checks |
| Hundred-page books or packets | bounded-memory parser with explicit continuation tests | page completion and cross-chunk structure matter as much as single-page scores |
| Expensive review or several candidate parses | calibrated region verification plus sampled accepted-result audits | a quality score does not expose missed regions or prove field correctness |
No matching workloads. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
Run at least one cheap baseline, one document specialist, one general-VLM path, and—when operator workflow matters—one full IDP suite. Hold corpus, schemas, prompts, page ranges, output normalization, versioning, and review policy constant. Test “field absent,” damaged pages, retries, rollbacks, data retention, review correction, concurrency, and p95 latency—not only the happy-path demo.
What comes next
Directions already visible in released systems
- Compact models and adaptive serving. Small cores can be paired with crop refinement, draft decoding or bounded attention; the complete serving path determines the resource tradeoff.12288
- Data and rewards that target remaining errors. Xiaomi, WeVisDoc and OCRia illustrate different ways to choose useful supervision and preserve structure. Their results do not isolate every ingredient.154316
- Separate generation, verification and acceptance. Jev makes the first separation explicit; workload tests and review policy still own the final decision.2
- Representations and retrieval that retain visual evidence. Typed documents, page-image embeddings and grounded records widen the options beyond one Markdown transcript.45818
- More inspectable evaluation. Revised reference labels, tagged unit tests and published output contracts make the scorer itself part of the versioned system.306063
Plausible, but dependent on disciplined execution
- Agentic workflows can choose parsers, refine schemas, query systems, and reconcile discrepancies—but only bounded tools, typed state, evidence, and acceptance tests make those loops safer.
- Multimodal retrieval will increasingly retain page images, structure, tables, and multiple representations rather than only text chunks.
- Evaluation will become continuous and slice-aware, with regression tests generated from corrections.
- Selective specialist/general-model ensembles may help, but their correlated failures and added cost must be measured.
More uncertain are one universal document foundation model replacing most pipelines, self-improving agents without governed test gates, and a confidence score that transfers reliably across corpora and tasks.
Working conclusion
The durable unit of comparison is the complete document workflow: what evidence it reads, what structure it preserves, how much work its serving path performs, and which errors its acceptance policy allows through. Recent releases improve different parts of that workflow. Their headline scores do not collapse those parts into one interchangeable capability.
Choose the output contract and error cost first. Establish a cheap baseline, compare specialists and general models on the same workload slices, and test retrieval, candidate verification and human review where they change the result. Keep the source evidence and version every contract that affects an accepted document. Optimize for information a downstream user can verify and use.
References
-
Milestones were checked October 31, 2026. Each atlas entry links its report revision, official release card or announcement. Granite uses its card’s September 17, 2025 release date; IBM’s September 24 article establishes design succession from SmolDocling. TeleOCR uses its September 10 report v3, not the first August submission under its earlier name. OCRia’s October 22 announcement is dated in LlamaIndex’s official article listing. LightOnOCR-3 and MiniCPM-OCR/Jev use announcement dates. Chandra and Surya use the dated October 23 open-model comparison as benchmark snapshots, not first release dates. Family updates do not assert shared weights or benchmark superiority. ↩ ↩2
-
OpenBMB, MiniCPM-OCR Jev guide, architecture, input triple, status handling and evaluation; fine-tuning and renderer guidance; checkpoint. Inspected October 31, 2026. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10
-
Ahmed Nassar et al., SmolDocling, 2025, Sections 2–4 and Figure 1. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
IBM Granite, Granite Docling 258M model card, architecture, curriculum and intended use. ↩ ↩2 ↩3 ↩4 ↩5
-
Haoran Wei, Yaofeng Sun, and Yukun Li, “DeepSeek-OCR: Contexts Optical Compression”, arXiv, 2025. ↩ ↩2 ↩3 ↩4
-
Haoran Wei, Yaofeng Sun, and Yukun Li, “DeepSeek-OCR 2: Visual Causal Flow”, arXiv, 2026. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
Youyang Yin et al., “Unlimited OCR Works”, Baidu technical report, arXiv v1, June 2026. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
Shu Wei et al., Unlimited OCR Works 2, October 29, 2026; mechanism inspection used the repository report, Sections 3–6, Algorithm 1 and Table 4. The October 27 checkpoint release and October 29 paper submission are different milestones. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11
-
Bin Wang et al., MinerU2.5-Pro, April 2026 revision, data engine and progressive training; checkpoint. ↩ ↩2 ↩3
-
Zelun Zhang et al., “PaddleOCR-VL-1.6: Expanding the Frontier of Document Parsing with Under-Optimized Region Refinement and Progressive Post-Training”, arXiv, 2026. ↩ ↩2 ↩3 ↩4 ↩5
-
Shuaiqi Duan et al., “GLM-OCR Technical Report”, 2026; Zhipu AI, GLM-OCR repository. ↩ ↩2 ↩3 ↩4 ↩5
-
OpenBMB, MiniCPM-OCR 1.0 guide, architecture, SDK pipeline, KIE and license; checkpoint. Inspected October 31, 2026. ↩ ↩2 ↩3 ↩4 ↩5
-
SoMark, OXR repository, Technical Architecture and RSI diagrams; OXR-1.0 artifact, model card, visual-tokenizer implementation and tensor metadata. Inspected October 31, 2026; formal report listed as forthcoming. ↩ ↩2 ↩3 ↩4 ↩5
-
Jake Poznanski, Luca Soldaini, and Kyle Lo, “olmOCR 2: Unit Test Rewards for Document OCR”, arXiv, 2025. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8
-
Xin Chen et al., Xiaomi-OCR-0 Technical Report, September 28, 2026. Sections 2–3, Figure 3 and Section 4 evaluation/ablations; headline parsing results use the two-stage pipeline. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11 ↩12
-
LlamaIndex, OCRia-1 technical report, October 2026, Sections 2–5 and Appendices B, D and E; 37-page edition inspected October 31, 2026. Reward shortcuts, benchmark denominators/rendering, failure cases and serving stack. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10
-
Handong Zheng et al., “Multimodal OCR: Parse Anything from Documents”, arXiv v2, 2026. ↩ ↩2 ↩3 ↩4 ↩5
-
Yunhang Shen et al., Youtu-Parsing-Omni, October 29, 2026, Sections 2–4 and 7; official checkpoint and custom license. Shared encoder, OmniSchema, reference-conditioned OSAD and inference limitations. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
Zhiheng Li et al., “How Far Is Document Parsing from Solved? PureDocBench”, arXiv, 2026. ↩ ↩2 ↩3
-
Cheng Cui et al., Real5-OmniDocBench, June 2026 revision. ↩ ↩2 ↩3
-
Birgit Pfitzmann et al., “DocLayNet: A Large Human-Annotated Dataset for Document-Layout Analysis”, KDD 2022. ↩ ↩2
-
Yiheng Xu et al., “LayoutLM: Pre-training of Text and Layout for Document Image Understanding”, KDD 2020. ↩
-
Yupan Huang et al., “LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking”, ACM Multimedia 2022. ↩
-
Geewook Kim et al., “OCR-free Document Understanding Transformer”, ECCV 2022. ↩
-
Kenton Lee et al., “Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding”, ICML 2023. ↩
-
Zineng Tang et al., “Unifying Vision, Text, and Layout for Universal Document Processing”, CVPR 2023. ↩
-
Junbo Niu et al., MinerU2.5, 2025, Section 3 and Figure 2. ↩ ↩2 ↩3 ↩4
-
NVIDIA, Nemotron 3.5 Parse model card and released configuration, inspected October 31, 2026. October 17 release field; causal visual-prefix decoder, bundled MTP head, output contract and ParseBench multi-pass/alternative-merge conditions. See also the October 21 author explanation. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
Manuel Faysse et al., ColPali, ICLR 2025, page-image multi-vector retrieval and late interaction. ↩ ↩2 ↩3
-
PureDocBench authors, maintained benchmark repository, inspected October 31, 2026. September 26 model expansion, October 27 supplied-prediction pipeline rescore, exact ground-truth/evaluator revisions and community-result archive; distinct from the original May report table. ↩ ↩2 ↩3
-
Gengluo Li et al., “HunyuanOCR-1.5: Making Lightweight OCR VLMs Faster and Better”, arXiv v2, August 2026. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
LightOn, LightOnOCR, June 2026 revision; LightOnOCR-2-1B. ↩ ↩2
-
LightOn, LightOnOCR-3-4B model card, family architectures, grounding output and supported prompt modes. ↩ ↩2
-
NVIDIA, Nemotron Parse 2.0 model card and configuration, inspected October 31, 2026. Cross-attention decoder configuration, separate training-only auxiliary head and output contract; the card links 3.5 as the newer version. ↩ ↩2 ↩3
-
Datalab, Chandra OCR 2 card, configuration and license, inspected October 31, 2026. Output formats, Qwen3.5-style configuration and separate code/weight terms; no claim of equivalence with the hosted Chandra 2.5 service. ↩ ↩2 ↩3 ↩4
-
Vik Paruchuri, Open-source OCR models on OmniParseBench, October 23, 2026. Publisher inference-parameter counting convention, per-family comparisons and absence of a headline when layout is unsupported. Vendor-authored evaluation. ↩ ↩2 ↩3
-
SoMark, OXR license with additional terms, commercial thresholds, online-service attribution and competing hosted-API restriction, inspected October 31, 2026. ↩ ↩2
-
Datalab, Surya OCR 2 card, configuration and license, inspected October 31, 2026. Shared VLM, prompt-specific outputs, separate line detector and commercial conditions. ↩ ↩2 ↩3
-
PaddlePaddle, HPD-Parsing usage tutorial, hierarchical branching, P-MTP and custom-runtime requirements; report. ↩ ↩2 ↩3
-
MinerU-Diffusion, March 2026, block diffusion, curriculum and inverse rendering. ↩ ↩2 ↩3
-
TeleOCR, September 2026 revision, deformation and structured-content methods. Earlier indexing used NaviDC. ↩ ↩2
-
Xiaomi Research, official repository, release news and evaluation pipeline; official checkpoint, inspected October 31, 2026. Release date, Apache-2.0 terms and direct/two-stage task interfaces. ↩ ↩2 ↩3
-
Hao Yu et al., WeVisDoc, September 17, 2026, Sections 3–4; official repository and checkpoint links. Two training stages, diagnostic split, fixed clusters and scoped stage comparisons. ↩ ↩2 ↩3 ↩4
-
LlamaIndex, Introducing OCRia-1, October 2026 announcement, inspected October 31. Establishes availability inside LlamaParse, not a verified public checkpoint release. ↩ ↩2 ↩3
-
Figure sources, licenses and reuse notices. Third-party figures are excluded from the repository’s MIT license. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11
-
Baidu, Unlimited-OCR repository and model card. ↩
-
Baidu, Unlimited-OCR release and deployment documentation and version 2 model card. Custom SGLang, prefill memory, page-window tradeoffs and released sparse-attention configuration, inspected October 31, 2026. ↩
-
Hunyuan Vision Team et al., “HunyuanOCR Technical Report”, arXiv v2, December 2025. ↩ ↩2 ↩3
-
Tencent Hunyuan, image-processor configuration and model configuration. Processor limits and vision config fields are not interchangeable. ↩
-
Datalab, Convert processor, inspected October 31, 2026. Hosted Chandra 2.5, serving modes, structured outputs and optional word boxes; provider claims were not independently exercised. ↩ ↩2 ↩3
-
OpenDataLab, MinerU repository, current software workflow and license information. ↩
-
PaddlePaddle, PaddleOCR, flagship VL 1.6, PP-OCRv6 and HPD-Parsing release documentation. ↩
-
OpenBMB, benchmark reproduction guide, official accelerated SDK comparison and incomplete DSpark reproduction logs; DSpark deployment. Author results, inspected October 31, 2026. ↩
-
Minesh Mathew, Dimosthenis Karatzas, and C. V. Jawahar, “DocVQA: A Dataset for VQA on Document Images”, WACV 2021. ↩
-
Ruben Tito, Dimosthenis Karatzas, and Ernest Valveny, “Hierarchical Multimodal Transformers for Multi-Page DocVQA”, Pattern Recognition, 2023. ↩
-
Mingtian Zhang, “MMLongBench-Doc-V2: A Corrected-Annotation, Semantics-Aware Revision of MMLongBench-Doc”, arXiv, 2026. ↩ ↩2
-
NVIDIA, Nemotron 3.5 Embed 1B BF16, input, pooling, dimensionality and total parameters; Embed, Rerank and Parse release, October 21, 2026. Retrieval is separate from parsing and answer generation. ↩ ↩2 ↩3
-
OpenDataLab, OmniDocBench, current version history and evaluation documentation, inspected October 31, 2026. Quoted model scores elsewhere retain their stated benchmark version. ↩
-
Datalab, OmniParseBench design and open scorer documentation, inspected October 31, 2026. Tests, family averaging, tags, failure coverage and published verdicts. A vendor-authored benchmark, not an independent audit of competing services. ↩ ↩2 ↩3 ↩4
-
Minglai Yang et al., Dr. DocBench, 2026, expert-domain and parser-failure-based evaluation. ↩ ↩2
-
Datalab, OmniParseBench dataset card and test construction, inspected October 31, 2026. Test derivation, annotation construction, output types and source-level rights; deterministic scoring does not establish perfect reference labels. ↩
-
Gauthami Polasani and Pierre-Loic Doulcet, Introducing the Document Parsing Protocol, October 28, 2026. Working draft 0.1 and ParseBench annotation provenance; a proposed representation contract. ↩ ↩2
-
Lianmin Zheng et al., Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena, 2023. The document-specific checklist above is a proposed application, not an experiment reported by this paper. ↩
-
Kai Greshake et al., Not what you’ve signed up for, 2023, indirect prompt injection through retrieved content. ↩
-
Google Cloud, Document AI overview. ↩
-
Microsoft, Document Intelligence overview. ↩
-
Microsoft, Content Understanding updates, inspected October 31, 2026. GA versus preview API scope and October async/synchronous page limits; no service test was performed. ↩ ↩2
-
Amazon Web Services, “Analyzing Documents” and “Bedrock Data Automation”. ↩
-
ABBYY, “Vantage introduction”. ↩
-
UiPath, Helix Extractor 2.0 and Document Understanding in IXP, inspected October 31, 2026. GA, regional defaults, existing-version behavior and platform boundary; complex-layout generative feature status is documented separately. ↩ ↩2
-
Rossum, “Data Capture Automation with Rossum”. ↩
-
Instabase, AI Hub overview. ↩
-
Mistral AI, OCR 4.1 and OCR 4.0 lifecycle status. ↩ ↩2
-
LandingAI, “Agentic Document Extraction changelog”. ↩ ↩2
-
LandingAI, ADE overview, inspected October 31, 2026. Parse, Extract, Classify, Section and Split interfaces; see the changelog for model-generation and snapshot behavior. ↩
-
Reducto, Extract overview. ↩
-
Unstructured, “Welcome to Unstructured”. ↩
-
Docling contributors, Docling, features, document representation and model-license boundary. ↩