Distillation methods differ in what they transfer, where they supervise the student, and how they update it. Separating those decisions is more useful than memorizing algorithm names. A teacher answer, a teacher probability distribution and a reward for completing a task are different objects.
This is a selected method map through October 14, 2026, including recent preprints. It is not a universal leaderboard. The foundations define the objectives; LLM and VLM recipes show deployed model families’ disclosed uses.
Start with the access you actually have
| Teacher access | Available signal | Important constraint |
|---|---|---|
| Responses only | Answers, rationales and tool trajectories | Unselected alternatives and internal states are unavailable. |
| Probabilities or logits | Soft targets at specified prefixes | Vocabularies, event meanings, precision and truncation must align. |
| Intermediate computation | Hidden states, attention or feature relationships | Layer, width, token and modality correspondence must be defined. |
This is an editorial access map. A few API log probabilities do not imply full-vocabulary access. Conversely, different network architectures can still share an output vocabulary. Access and architecture are separate constraints.
The main families
Methods by learning signal
8 method families| Family | Mechanism | What to check |
|---|---|---|
| Response or sequence | Train on selected teacher responses with token likelihood. SeqKD established this route for translation.1 | Selection and decoding change which teacher behavior survives. |
| Soft token targets | Match next-token alternatives rather than one observed token. Gemma 2 uses this during smaller-model pretraining.2 | Events must align; full, sampled and top-k targets differ. |
| Feature hints | Match an intermediate teacher representation through a specified mapping. FitNets studies this for thinner students.3 | Matching dimensions alone does not establish matching semantics. |
| Relationship matching | Transfer distances or angles between examples, as in RKD; MiniLM transfers attention and value relations within sequences.45 | State which objects are related and which structure is preserved. |
| Student-rollout distillation | Ask the teacher to supervise prefixes the student actually generates, as in GKD.6 | Rollout freshness and the divergence are independent choices. |
| Contrastive distillation | DistiLLM-2 couples different objectives with teacher and student responses.7 | It is not simply DPO with a teacher substituted for the reference. |
| Cross-tokenizer transfer | ALM compares likelihoods of aligned text chunks under different tokenizations.8 | Token IDs cannot be compared as if they denoted the same event. |
| Context and self-distillation | OPCD teaches a student without extra context using a teacher that receives it.9 | Identify the teacher’s information advantage and update policy. |
No matching method families. Try another term or reset the search.
Scroll to compare. Focus view gives the table more room.
Methods can be combined. An assistant can first learn teacher demonstrations, then receive soft targets on its own rollouts. A VLM can combine output supervision with visual relationships. The combination needs a defined objective and evidence, not just more loss terms.
Why supervise the student’s own mistakes?
Training only on polished teacher responses can leave the student unprepared for its own imperfect continuations. At inference, one mistaken step changes the prefix for every later step. GKD addresses this mismatch using student responses and allows several discrepancy measures.6
- PromptTask input
- Teacher responseTeacher supplies the trajectory
- Student updateHard labels or soft teacher targets
Feedback is evaluated on the selected demonstration prefixes.
- Student generatesCurrent or recorded student version
- Teacher scoresThe same visited response prefixes
- Student updateChosen divergence and token weighting
Refresh experience after updates. A replayed rollout is not automatically on policy for the new student.
Figure 1. Change the visited experience, not only the loss. Independent explanation informed by GKD.6
In Figure 1, the teacher evaluates what should come next, conditional on the visited prefix. It does not rewrite the past. If the prefix is already contradictory, teacher advice may itself be unreliable. Filtering, a useful cold start and retaining correct demonstrations remain meaningful design options.
The loss and sampling policy are independent axes
A useful conceptual objective is:
Here, is the visited prefix, supplies trajectories, and specifies the ordered discrepancy. Forward KL, reverse KL and generalized Jensen–Shannon objectives give different updates. This length-averaged expression is a schematic of prefix-conditioned matching, not the exact objective of every method.6
In a common implementation, rollout collection is outside backpropagation and the update treats collected prefixes as fixed. Differentiating the full parameter-dependent trajectory distribution would introduce additional terms. MiniLLM derives a policy-gradient optimizer for its reverse sequence KL; that is not interchangeable with every local token-KL update.10
“Offline” often means a fixed stored dataset. “On policy” means experience from the policy being updated. A dataset generated yesterday by an older student is student-generated but stale. “Online distillation” can also mean co-trained teacher/student networks in other literature. State the operational meaning rather than treating these labels as synonyms.
DistiLLM-2: match the objective to the response source
DistiLLM-2 combines a contrastive loss with teacher and student outputs, dataset curation and a changing skew coefficient. Its implementation collects student responses ahead of each training epoch, instead of regenerating them at every update. That trades rollout freshness for generation efficiency. The paper evaluates instruction, code, preference and VLM settings; these are its tested settings, not evidence of optimality on every task.7
Different tokenizers need a common event
For the same text, one model may emit a single token where another emits several. Padding a vocabulary or aligning token indices does not solve this. ALM, Approximate Likelihood Matching, identifies chunks covering the same text span, then approximates a discrepancy between their likelihoods. It also studies debiasing and optional hidden-state supervision.8
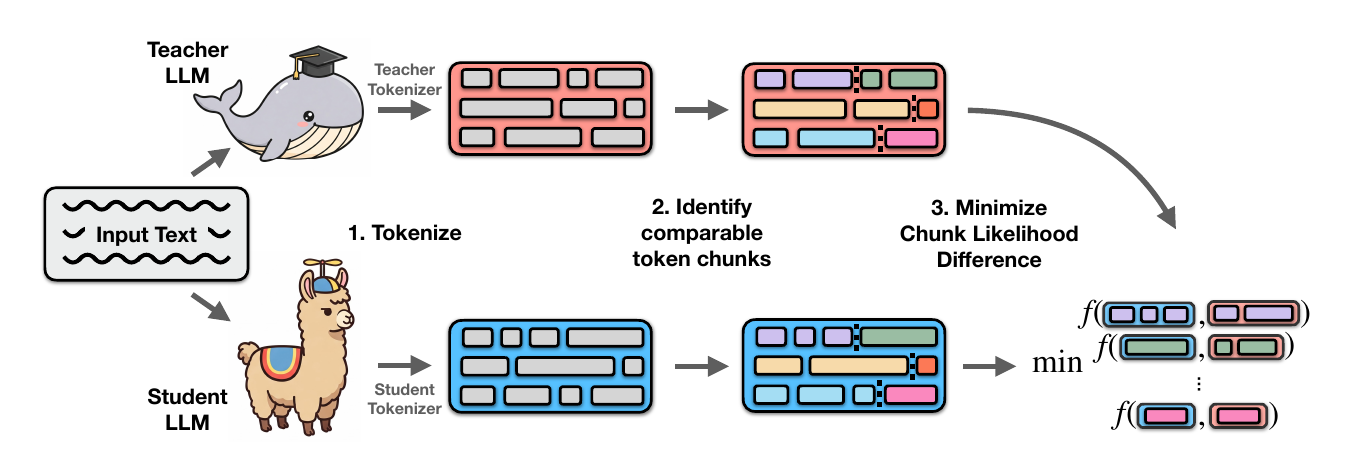
Figure 2. Match text spans across different token boundaries. Minixhofer, Vulić and Ponti, ALM v4, original Figure 1; figure-region crop, CC BY-SA 4.0.811
Notice in Figure 2 that matching a chunk is not enumerating every possible string continuation. The approximation is part of the method, not an exact conversion of arbitrary teacher logits into student vocabulary logits.
Reasoning: transfer more than an answer
Distilling Step-by-Step uses teacher rationales as an additional task alongside label prediction. This is different from requiring a deployed student to emit the entire rationale before every answer. Its reported benefits concern specific task models and datasets.12
For a modern reasoning assistant, separate four experiments: final answers only, answer plus rationale, verified or filtered rationale, and feedback on student-generated reasoning. Keep answer correctness, reasoning length and generalization separate. A fluent rationale can still be wrong; an answer check alone cannot establish that every reasoning step is valid.
A teacher can know more because it sees more
OPCD conditions the teacher on additional context, such as accumulated experience or a system prompt, while the student generates without it. The teacher may be a separate model or share the student’s weights. In the latter case, the information advantage comes from the context, not additional parameters.9
This suggests a useful deployment question: which stable behavior can move from repeated context into weights? It does not establish that a changing knowledge base can be safely discarded. Test unseen questions, factual updates and retained capabilities independently.
Recent directions worth watching
Selective teacher supervision. Dr. OPD, a September 2026 preprint, uses outcome rewards to weight token-level teacher guidance. Its surrogate connects teacher corrections with reward improvement, with practical approximations and assumptions. The published experiments concern math and code, not every assistant workload.13
Agent skill feedback. OPID extracts episode and critical-step guidance from completed trajectories. An old policy re-scores the same actions with and without that guidance. The resulting token signal augments an outcome-based RL objective; this is not merely copying a teacher tool transcript. Its reported environments include ALFWorld, WebShop and search QA.14
Do methods teach facts or better execution? The October 2026 fact/skill study tests this distinction directly. It strengthens the case for separate evaluation dimensions, while leaving open how results change with privileged context, data, scale and objectives.15
The open problem is not simply finding a new divergence. It is allocating teacher attention where a particular student can learn something useful, without losing rare behaviors or mistaking agreement for capability. Continue with the training recipes.
References
-
Yoon Kim and Alexander M. Rush. Sequence-Level Knowledge Distillation, EMNLP 2016, Section 3. ↩
-
Gemma Team. Gemma 2: Improving Open Language Models at a Practical Size, 2024, Section 3.2. ↩
-
Adriana Romero et al. FitNets: Hints for Thin Deep Nets, ICLR 2015, hint-based training and representation mapping. ↩
-
Wonpyo Park et al. Relational Knowledge Distillation, CVPR 2019, distance and angle losses between examples. ↩
-
Wenhui Wang et al. MiniLM: Deep Self-Attention Distillation for Task-Agnostic Compression of Pre-Trained Transformers, NeurIPS 2020, attention and value-relation transfer. MiniLM is distinct from MiniLLM. ↩
-
Rishabh Agarwal et al. On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes, ICLR 2024, Section 3 and Algorithm 1. ↩ ↩2 ↩3 ↩4
-
Jongwoo Ko et al. DistiLLM-2: A Contrastive Approach Boosts the Distillation of LLMs, ICML 2025, Sections 2.2–3, Algorithm 1 and Section 6. ↩ ↩2
-
Benjamin Minixhofer, Ivan Vulić and Edoardo M. Ponti. Universal Cross-Tokenizer Distillation via Approximate Likelihood Matching, NeurIPS 2025, Figure 1 and Section 3. The original submission used a shorter title. ↩ ↩2 ↩3
-
Tianzhu Ye et al. On-Policy Context Distillation for Language Models, March 23, 2026 preprint, Section 3 and Algorithm 1. ↩ ↩2
-
Yuxian Gu et al. MiniLLM: Knowledge Distillation of Large Language Models, ICLR 2024, Section 2 and Appendix A. ↩
-
Figure sources and reuse records, ALM extraction and retained share-alike artwork terms. Original figures are not under the site’s MIT license. ↩
-
Cheng-Yu Hsieh et al. Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes, ACL 2023, Section 3’s multitask rationale and label formulation. ↩
-
Zhenyu Wang et al. Dr. OPD: Learning What to Follow for Optimal On-Policy Distillation of Large Language Models, September 29, 2026 preprint, Sections 3–5; theoretical assumptions and practical credit approximation are separate. ↩
-
Shuo Yang et al. OPID: On-Policy Skill Distillation for Agentic Reinforcement Learning, June 25, 2026 preprint, Sections 3.2–3.4 and evaluation settings. ↩
-
Yixuan Tang and Yi Yang. On-Policy Distillation Teaches New Skills but Not New Knowledge, October 7, 2026 preprint, independent control of teacher facts and compositional skill. ↩