This page builds a foundational understanding of the Transformer: a starting point for studying modern large language models (LLMs), vision language models (VLMs), and the architectures that come next.
Start with a simple idea: turn one sequence into another, as Figure 1 illustrates. A sentence becomes a translation, a document becomes a summary, and a question becomes an answer. This sequence to sequence formulation brings many language tasks under one framework.1 It can also reach beyond text: an image can become a sequence describing the objects it contains and where they are.2 The original Transformer was designed for translation, but the broader idea is a useful starting point: represent an input and learn to produce the desired output.3
Doing this well requires context. “Bank” means something different beside “river” than beside “account.” A Transformer builds numerical representations of its input, then refines them through repeated layers. Each position draws on relevant information from the context it is allowed to see.3
The design also suits large scale training. Unlike recurrent models, which process a sequence through dependent steps, a Transformer can process many positions together using matrix operations that run efficiently on GPUs.3 Researchers can grow the model through more layers and wider representations; studies have found predictable improvements in text prediction as model size, data, and compute increase within tested ranges.4 This is not unlimited: comparing all pairs of positions is costly for long contexts, and ordinary text generation still proceeds one token at a time.3
We follow the original architecture, connect it to Harvard NLP’s readable implementation, and then look at modern LLMs and VLMs. Each component is introduced when it becomes useful.
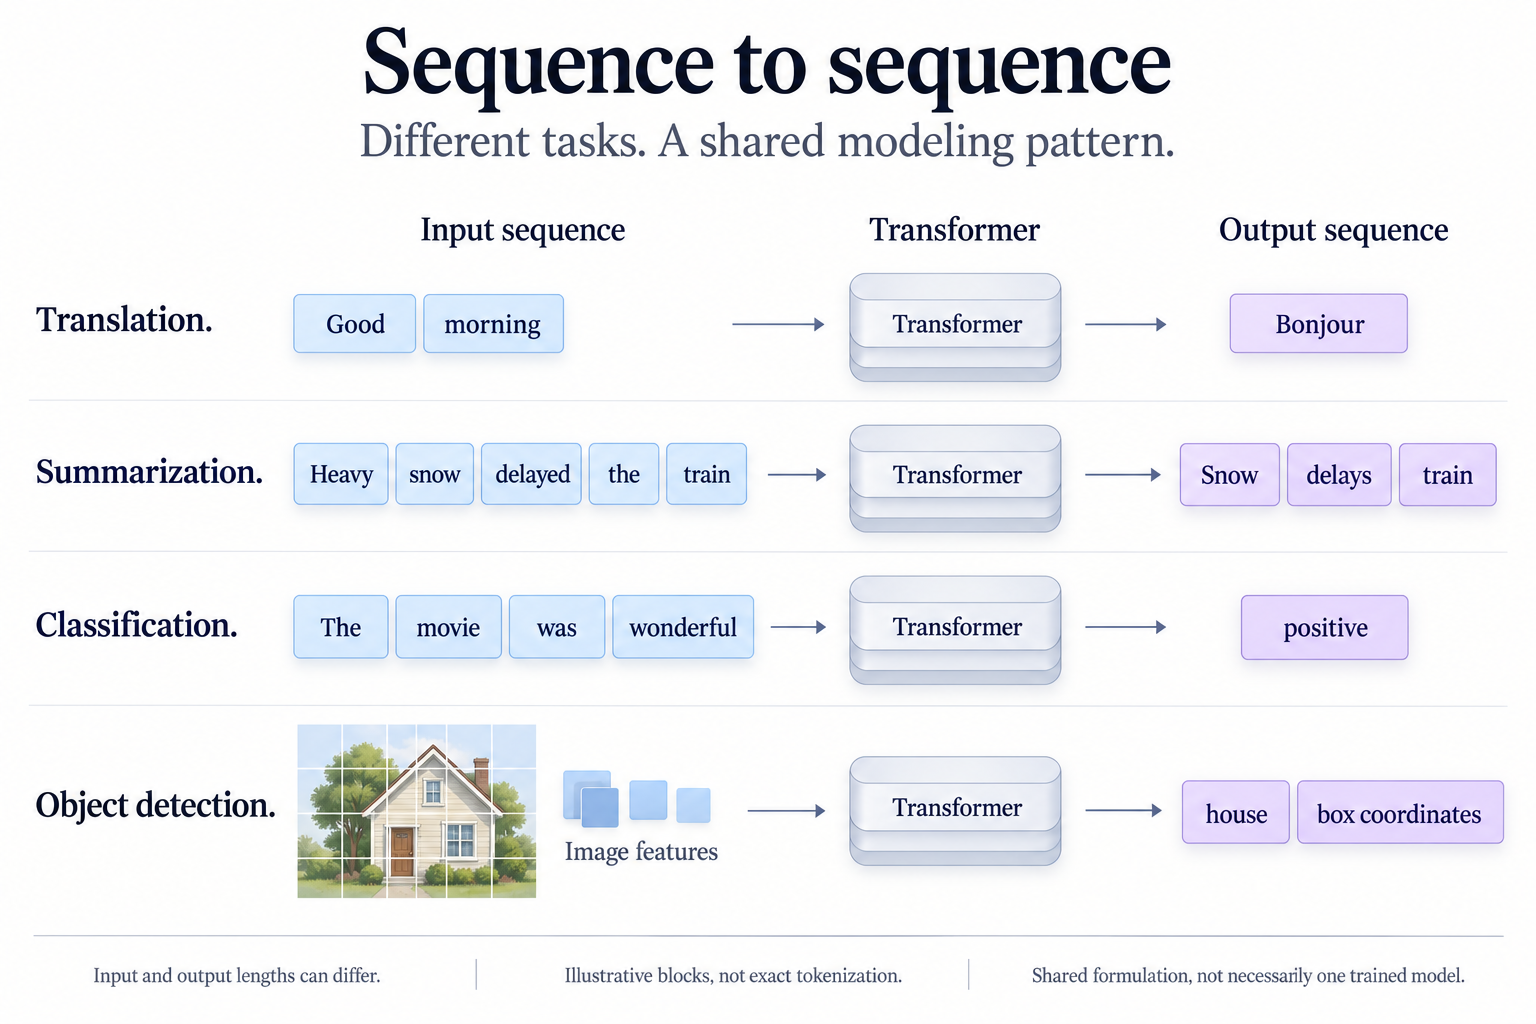
Figure 1. Different tasks, a shared sequence formulation. AI generated illustration informed by Transformer, T5, and Pix2Seq.312
| Reading path | What to understand |
|---|---|
| Architecture and data flow | Two streams, encoder memory, decoder states, vocabulary scores |
| Attention and masking | Q, K, V, scaling, softmax, visibility, head shapes, KV sharing |
| Components and full model | Residuals, normalization, FFN, embeddings, position, independent layers |
| Training and inference | Shifted labels, loss, optimization, SFT, decoding, caching |
| From Transformer to modern LLMs | Which contracts persist and which design choices change |
Architecture and data flow
Read the original architecture
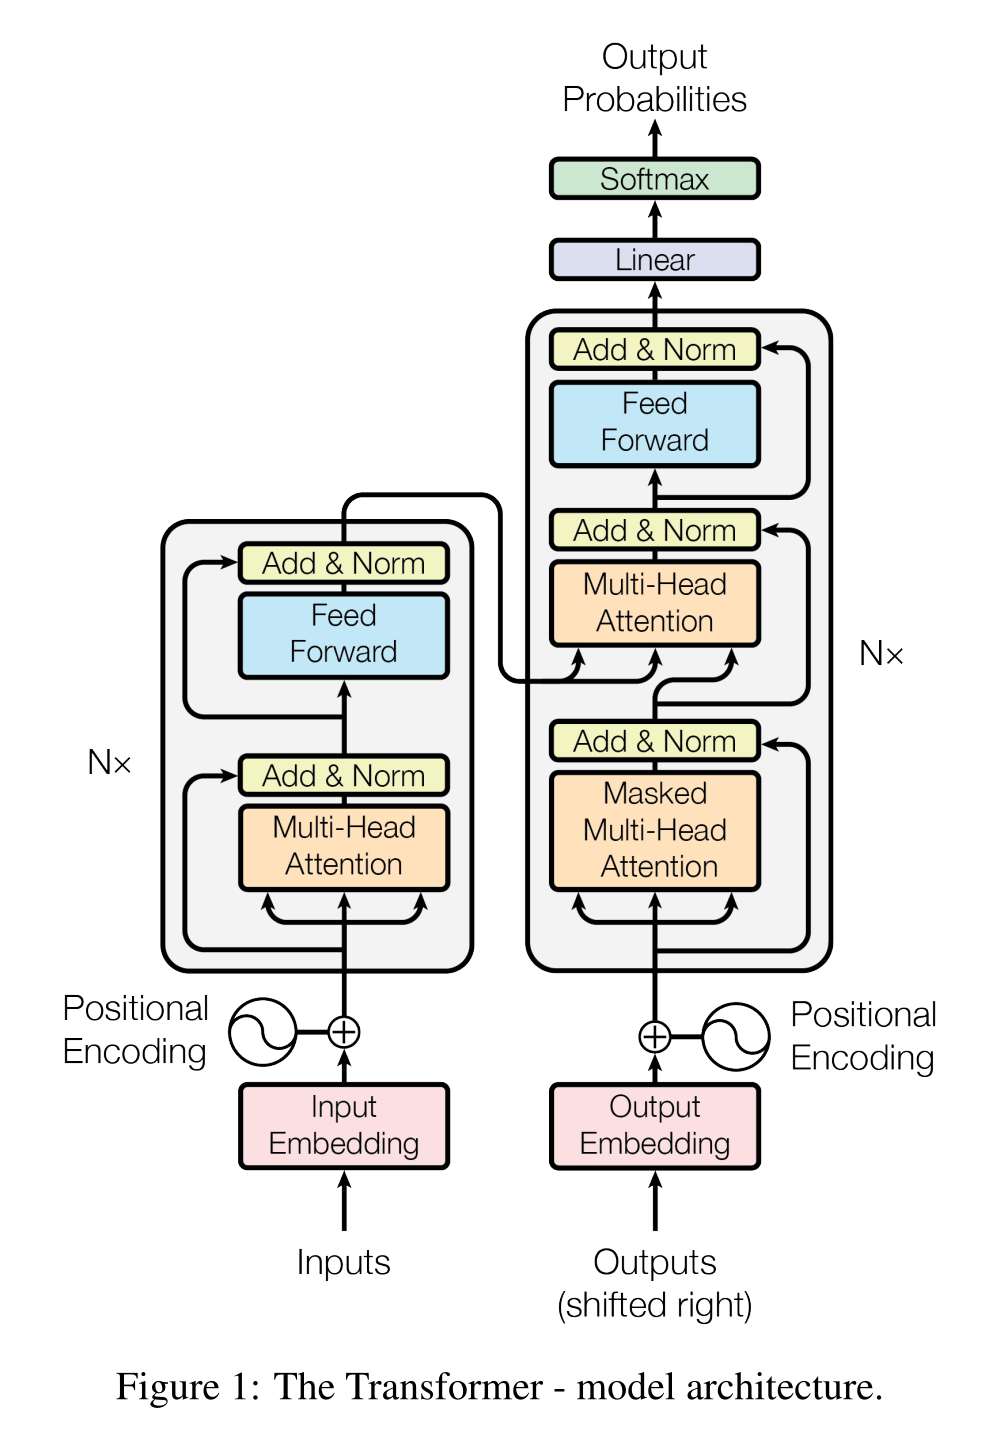
Figure 2. Original Transformer architecture. Reproduced from Figure 1 of Vaswani et al. (2017, v7), with the source’s scholarly reproduction permission.3
The encoder creates contextual representations of a source sequence. The decoder reads a target prefix and that encoder memory to predict the next target token. Its masked self-attention prevents access to later target positions; cross-attention can read all unpadded source positions. The paper draws post-normalization: residual addition comes before LayerNorm.3
Follow the top level contract
Memory Z connects the two paths. Every decoder cross attention layer reads it; S and T need not match.
Figure 3. Two streams connected by encoder memory. Original diagram based on the Transformer architecture and Harvard implementation.35
Let B be batch size, S source length, T target input length, D model
width, and V target vocabulary size. The two sequence lengths can differ:
cross-attention uses T queries against S keys and values.
| Value | Shape | Meaning |
|---|---|---|
| Source IDs | B × S |
Source token indices |
| Source embedding | B × S × D |
Token features plus position |
| Encoder memory Z | B × S × D |
Contextual source features |
| Shifted target IDs | B × T |
Target prefix at each position |
| Decoder hidden states | B × T × D |
Contextual target features |
| Vocabulary logits or log probabilities | B × T × V |
Next token scores per target position |
This shape ledger is a local derivation from the module interfaces.5
The encoder preserves S; the decoder preserves T; neither requires
source length to equal target length.
About the code examples
These are teaching excerpts, not a standalone runnable library. They assume
PyTorch and the helper modules from the pinned Harvard tutorial. Differences
between the original paper and the tutorial are explained where they matter.
Adapted code is MIT licensed, copyright 2018 Alexander Rush. The
full license notice is retained in
public/licenses/annotated-transformer-MIT.txt.56
# Adapted from Harvard NLP, commit debc9fd, MIT license.
class EncoderDecoder(nn.Module):
    def __init__(self, encoder, decoder, src_embed, tgt_embed, generator):
        super().__init__()
        self.encoder, self.decoder = encoder, decoder
        self.src_embed, self.tgt_embed = src_embed, tgt_embed
        self.generator = generator

    def forward(self, src, tgt, src_mask, tgt_mask):
        memory = self.encode(src, src_mask)
        return self.decode(memory, src_mask, tgt, tgt_mask)

    def encode(self, src, src_mask):
        return self.encoder(self.src_embed(src), src_mask)

    def decode(self, memory, src_mask, tgt, tgt_mask):
        return self.decoder(self.tgt_embed(tgt), memory, src_mask, tgt_mask)
The top level forward returns decoder features, not probabilities.
The generator is a separate vocabulary projection followed by log-softmax:
# Adapted from the same pinned Harvard implementation.
class Generator(nn.Module):
    def __init__(self, d_model, vocab):
        super().__init__()
        self.proj = nn.Linear(d_model, vocab)

    def forward(self, x):
        return F.log_softmax(self.proj(x), dim=-1)
D is a representation width; V is a number of candidate tokens. A modern
loss API may consume raw logits and apply the stable log-softmax internally.
For example, PyTorch CrossEntropyLoss expects unnormalized logits and applies
log-softmax internally. Check the API contract rather than assuming every loss
expects the tutorial’s output.7
The tutorial’s generator returns log probabilities for its KL loss.5
The separate generator also makes weight tying an explicit choice. The original paper shares embedding and output projection weights; the pinned tutorial factory instantiates separate modules rather than establishing that sharing. A shared matrix needs compatible vocabulary and width contracts.35
Attention and masking
One head from scores to content
Queries encode matching features for destination positions. Keys encode matching features for source positions. Values carry the content to combine. “What I seek,” “how I can be found,” and “what I carry” are useful interpretations, not fixed semantic roles assigned to individual neurons.
Here is key width, and softmax normalizes over key positions. This is the paper’s original scaled dot product attention formula.3
When masking is needed, forbidden scores are set to negative infinity before softmax. Implementations can replace logits or use a fused causal kernel rather than materializing an additive mask.38
✓ visible · × blocked
Visibility is not an attention weight.
| Stage | Key 1 | Key 2 | Key 3 |
|---|---|---|---|
| Scores | 2 | 1 | 4 |
| Masked | 2 | 1 | −∞ |
| Weights | 0.731 | 0.269 | 0 |
Output ≈ 0.731 v₁ + 0.269 v₂
Key 3 has the highest score, but is in the future.
Masking gives it zero weight. These numbers are illustrative.
The diagonal is visible. Padding can exclude additional keys.
Figure 4. Scores become weights, then weighted content. Original diagram based on the paper and Harvard implementation; example numbers are calculated here.35
Queries and keys determine routing weights; values supply the content to mix.3
The grid shows permitted connections, not attention weights. For the illustrated
query 2, scaled scores [2, 1, 4] become [2, 1, −∞], giving weights about
[0.731, 0.269, 0]. The output is therefore about 0.731 times the first value
vector plus 0.269 times the second. This row is an illustrative calculation,
not a measured model result.
For one head, Tq queries and Tk key/value positions give:
| Tensor | Shape | Interpretation |
|---|---|---|
| Q | B × Tq × dₖ |
Destination matching features |
| K | B × Tk × dₖ |
Source matching features |
| V | B × Tk × dᵥ |
Source content |
| QKᵀ and attention weights | B × Tq × Tk |
One routing distribution per query |
| Output | B × Tq × dᵥ |
Weighted source content |
K and V must share their sequence length because the weight assigned to key j
multiplies value j. Q can have a different length. The contraction is over key
positions, leaving one output for every query. These shapes follow directly from
the attention equation.3
Why divide by the square root
Under the illustrative assumption that components of q and k are independent, zero mean, and unit variance:
The standard deviation grows as . Dividing by that factor keeps the scale near one under these assumptions and helps avoid saturating softmax early. This is a variance argument, not a claim that learned features always obey those assumptions.3
# Adapted from Harvard NLP's attention function, MIT license.
def attention(query, key, value, mask=None, dropout=None):
    scores = query @ key.transpose(-2, -1)
    scores = scores / math.sqrt(query.size(-1))
    if mask is not None:
        # This teaching variant uses -inf instead of the tutorial's -1e9.
        scores = scores.masked_fill(~mask.bool(), float('-inf'))
    weights = scores.softmax(dim=-1)
    if dropout is not None:
        weights = dropout(weights)
    return weights @ value, weights
The order is score, scale, mask, normalize, optional training dropout, and value
mixing. Softmax produces normalized rows before dropout; a realized row after
dropout need not sum to one. Every scored row needs at least one visible key.
An all −∞ row has no meaningful softmax distribution. The tutorial’s finite
sentinel does not fix that semantic error, and −1e9 is not safe for every dtype.
This excerpt is for understanding, not a substitute for a tested production kernel.5
Padding and causality are different restrictions
In Figure 4, multiplying scores by the Boolean mask instead would
give [2, 1, 0], which still assigns positive probability to
the blocked cell. Masking weights afterwards requires explicit renormalization.
This numerical example is a local calculation.
| Mask | What it excludes | Shape before head broadcast |
|---|---|---|
| Source padding | Padded source keys | B × 1 × S |
| Target padding | Padded target keys | B × 1 × T |
| Causal visibility | Keys later than the query | 1 × T × T |
| Combined target visibility | Padding or future keys | B × T × T |
# Adapted from Harvard NLP's subsequent_mask, MIT license.
def subsequent_mask(length):
    future = torch.triu(torch.ones(1, length, length), diagonal=1).bool()
    return ~future  # True means visible in this page's teaching code.
Decoder row can see keys . This diagonal is valid because the input is shifted relative to the label. Source padding is reused in encoder self-attention and decoder cross-attention. Mask polarity differs across APIs: shape compatibility alone does not establish correct semantics.58
Multi-head attention
Each head uses learned Q, K, and V projections. Its attention weights can differ from those of another head. The outputs are concatenated and projected back to model width. Concatenation is not averaging, and projecting into several spaces is not simply copying the same attention computation.3
Self-attention uses the same states for both inputs. Cross-attention can use different lengths, Tq and Tk.
H heads run in parallelAᵢ contains Tq × Tk weights per batch item. Each head returns B × Tq × dᵥ.
Concatenate, not average. In the original equal-width setup, dₖ = dᵥ = D/H. The cards are illustrative, not a checkpoint.
Figure 5. Parallel heads, concatenated outputs. Original diagram based on the paper and Harvard implementation; head cards are illustrative.35
Query states have shape B × Tq × D; key and value states have shape
B × Tk × D. Each head forms Tq × Tk attention weights per batch item and
returns B × Tq × dv. Concatenation and the output projection restore width D.
In self-attention both inputs are the same states; in cross-attention their
sequence lengths can differ.35
For heads in the original equal width setup, :
Learned projections    B × T × D
Reshape                B × T × H × d
Transpose              B × H × T × d
Attention scores       B × H × Tq × Tk
Head outputs           B × H × Tq × d
Transpose back         B × Tq × H × d
Concatenate            B × Tq × D
Output projection      B × Tq × D
# Adapted shape excerpt from Harvard's MultiHeadedAttention, MIT license.
if mask is not None:
mask = mask.unsqueeze(1) # Share visibility across the head axis.
query, key, value = [
linear(x).view(batch_size, -1, num_heads, head_width).transpose(1, 2)
for linear, x in zip(qkv_linears, (query, key, value))
]
head_output, weights = attention(query, key, value, mask=mask)
output = head_output.transpose(1, 2).contiguous().view(
batch_size, -1, num_heads * head_width
)
output = output_linear(output)transpose changes strides. The tutorial requests contiguous storage before
using view to merge head and feature axes. If using reshape instead, understand
when it can copy rather than assume the memory layout stayed unchanged.5
Three attention patterns
| Location | Query input | Key and value input | Visibility |
|---|---|---|---|
| Encoder self-attention | Source states | Same source states | Unpadded source |
| Decoder self-attention | Target states | Same target states | Unpadded causal prefix |
| Cross-attention | Decoder states | Encoder memory | Unpadded source |
The function is the same; tensor origin and visibility change. This is why
cross-attention can return T outputs while reading S memory positions.3
MHA, GQA, and MQA
These variants can retain the same query head count Hq. What changes is the
number of distinct key and value heads Hkv.
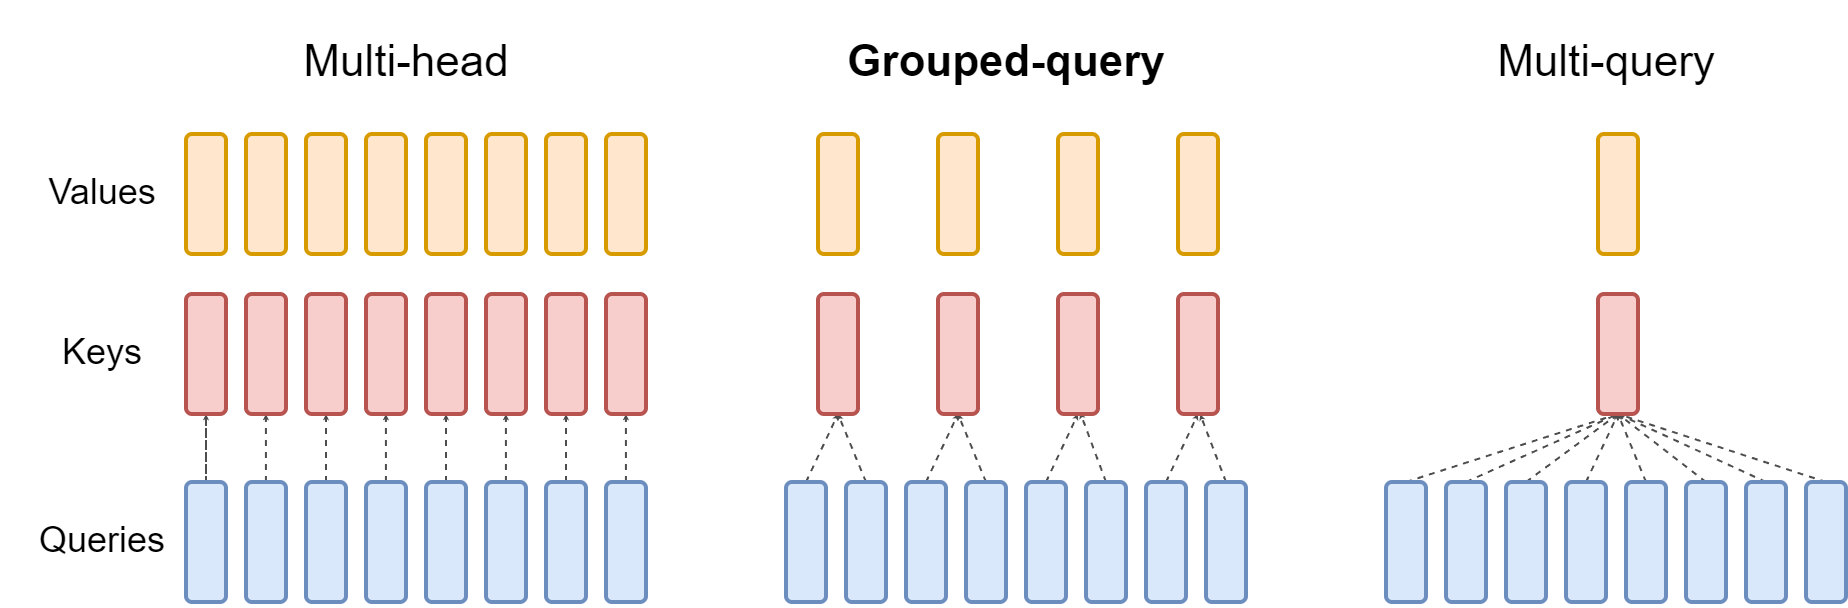
Figure 6. Query and KV sharing. Reproduced unchanged from Figure 2 of Ainslie et al., GQA (2023), under CC BY 4.0.9
| Variant with Hq = 8 | Hkv | KV sharing | Relative cache elements |
|---|---|---|---|
| MHA | 8 | One KV pair per query head | 100% |
| Illustrated GQA | 4 | Two query heads per KV pair | 50% |
| MQA | 1 | All query heads share one KV pair | 12.5% |
Each query head still produces its own score matrix and weighted output. Q has
shape B × Hq × Tq × dₖ, K has B × Hkv × Tk × dₖ, and V has
B × Hkv × Tk × dᵥ. A mapping assigns each query head its KV head:
For equal groups, each KV head serves Hq/Hkv query heads. Efficient kernels
can reuse K/V without materializing copies for every query head.8 The table’s cache
fractions are a local derivation for equal head width and sequence length.9
The GQA paper also converts MHA checkpoints by averaging groups of K/V projection heads and continuing training. That is an uptraining recipe, not a pooling operation in every GQA forward pass. KV sharing primarily targets cache and memory bandwidth; it does not turn full attention into a linear operator.9
Components and full model
The assembly map
- Self-attention
- FFN
- Masked self-attention
- Cross-attention · K, V from Z
- FFN
Repeat with independent parameters. The final norm sits outside the repeat.
Figure 7. Residual bypasses and repeated layers. Original diagram of the pinned Harvard Pre-LN implementation, not the paper’s Post-LN order.53
Each sublayer transforms a normalized branch; its unchanged input bypasses that
branch and is added back after dropout. An encoder layer has self-attention and
FFN blocks; a decoder layer adds cross-attention. Each stack repeats its layer
N times with independent parameters, then applies a final LayerNorm.5
Residual paths and normalization
The Harvard wrapper normalizes the input before the sublayer:
# Adapted from Harvard NLP's SublayerConnection, MIT license.
class SublayerConnection(nn.Module):
    def __init__(self, size, dropout):
        super().__init__()
        self.norm = LayerNorm(size)
        self.dropout = nn.Dropout(dropout)

    def forward(self, x, sublayer):
        return x + self.dropout(sublayer(self.norm(x)))
Residual addition requires matching shapes. It carries the input forward while adding a learned update. LayerNorm transforms each token’s feature vector without mixing sequence positions. Normalization placement changes the gradient path; it is not merely interchangeable notation. The tutorial additionally normalizes the output of each completed stack.510
Read the implementation as well as the name. The pinned tutorial’s custom
LayerNorm uses x.std and adds epsilon outside the standard deviation. That
does not establish numerical equivalence to a framework LayerNorm with its
own variance estimator and epsilon convention. For a reproduction, preserve
the implementation; for new code, use a tested layer and document the change.5
Encoder and decoder layers
# Explanatory pseudocode adapted from the pinned Harvard layers.
def encoder_layer(x, source_mask):
    x = residual(x, lambda h: self_attention(h, h, h, source_mask))
    return residual(x, feed_forward)

def decoder_layer(x, memory, source_mask, target_mask):
    x = residual(x, lambda h: self_attention(h, h, h, target_mask))
    x = residual(x, lambda h: cross_attention(h, memory, memory, source_mask))
    return residual(x, feed_forward)
The wrapper passes normalized h to the lambda. In cross-attention, only the
decoder query stream follows that residual wrapper; keys and values come from
the already encoded memory. The self-attention and cross-attention objects
have separate learned projection weights.5
The position wise FFN
Attention determines which contextual information reaches a position. The FFN
then provides a nonlinear feature transformation at that position, using shared
weights across tokens. It does not directly mix the sequence axis. The paper’s
base configuration expands width 512 → 2048 → 512.3
# Adapted from Harvard's PositionwiseFeedForward, MIT license.
def forward(self, x):
    return self.w_2(self.dropout(self.w_1(x).relu()))
The expansion gives the nonlinear operation more intermediate features while the contraction restores the residual interface. Without an intervening nonlinearity, two linear transformations would collapse into one linear map. That is an algebraic explanation, not proof that every expansion ratio is optimal.
Embeddings and sinusoidal position
Token IDs select learned vectors. The tutorial multiplies them by , adds a sinusoidal position vector, then applies dropout:
Each sine and cosine pair uses a different angular frequency. The position
vector has width D so it can be added to token features; a stored
1 × max_length × D buffer broadcasts across the batch.35
Exact toy encoding: D = 8. Three of its four sine / cosine pairs are shown.
Position p →
Vertical axis: encoding value. Frequencies follow the paper's rule, ωᵢ = 10000^(−2i/D); this is a calculation, not a trained-model measurement.
Figure 8. Position at different frequencies. Calculated from the paper’s
sinusoidal rule for a toy width of D = 8.3
Three channel pairs are plotted over positions 0–63, with angular frequencies
1, 0.1, and 0.01. The fourth pair, at 0.001, is omitted. Every pair has
a sine channel starting at zero and a cosine channel starting at one; lower
frequencies vary more slowly. The lines show the analytical functions between
integer positions, not a measured model result.
# Teaching excerpt adapted from Harvard, MIT license; D is even here.
positions = torch.arange(max_length).unsqueeze(1)
frequencies = torch.exp(torch.arange(0, D, 2) * (-math.log(10000.0) / D))
pe = torch.zeros(max_length, D)
pe[:, 0::2] = torch.sin(positions * frequencies)
pe[:, 1::2] = torch.cos(positions * frequencies)
# In an nn.Module, register the fixed tensor as a buffer, not a parameter.
self.register_buffer('pe', pe.unsqueeze(0))
model_input = dropout(embedding(token_ids) * math.sqrt(D) + self.pe[:, :T])
Sine and cosine addition identities make a fixed position offset a linear rotation within each pair. This explains the relative offset motivation; it does not guarantee useful generation beyond the trained length. Ordinary self-attention alone, without position or asymmetric visibility, cannot distinguish arbitrary permutations by order.3
Independent layers and the factory
Deep-copying a module creates independent parameter objects. Calling the same module object N times ties weights. Identical structure and identical initial values are not the same as shared parameters. The tutorial factory builds distinct encoder/decoder layers and distinct self/cross-attention modules:
# Condensed from Harvard's make_model; classes come from that tutorial.
c = copy.deepcopy
attn = MultiHeadedAttention(heads, d_model)
ff = PositionwiseFeedForward(d_model, d_ff, dropout)
position = PositionalEncoding(d_model, dropout)
model = EncoderDecoder(
    Encoder(EncoderLayer(d_model, c(attn), c(ff), dropout), layers),
    Decoder(DecoderLayer(d_model, c(attn), c(attn), c(ff), dropout), layers),
    nn.Sequential(Embeddings(d_model, source_vocab), c(position)),
    nn.Sequential(Embeddings(d_model, target_vocab), c(position)),
    Generator(d_model, target_vocab),
)
for parameter in model.parameters():
    if parameter.dim() > 1:
        nn.init.xavier_uniform_(parameter)
The factory’s Xavier initialization follows construction. Architecture contracts alone do not specify optimization behavior.5
| Boundary | Invariant |
|---|---|
| Embedding to stack | Final width D |
| Sublayer to residual add | Same input and output shape |
| Original head split | D divisible by H |
| Memory to cross-attention | Width compatible with K/V projections |
| Decoder to generator | Width D |
| Generator to loss | Vocabulary axis V and correctly aligned labels |
This boundary checklist is a local synthesis of the paper and tutorial interfaces.35
Training and inference
Teacher forcing and shifted labels
| Position | 1 | 2 | 3 | 4 |
|---|---|---|---|---|
| Input | BOS | y₁ | y₂ | y₃ |
| Label | y₁ | y₂ | y₃ | EOS |
Loss → backward → optimizer update. Predictions are trained in parallel, but each position sees only its allowed prefix.
Stop at EOS or the length limit. KV caching saves repeated work; it does not remove the next-token dependency.
Figure 9. Parallel training, autoregressive generation. Original diagram based on Harvard’s Batch and decoding loops; EOS stopping is added here.5
During training, shifted inputs are known in advance and scores at each position are compared with the next known label. Labels enter the loss, not a token selection step. During generation, the selected token is appended to the prefix and fed back for the next step; stop at EOS or the length limit. Cache reuse changes the work performed, not this dependency.51112
Full target       BOS  y₁  y₂  y₃  EOS
Decoder input     BOS  y₁  y₂  y₃
Prediction label  y₁   y₂  y₃  EOS
All correct previous tokens are available at training time. The causal mask prevents a prediction from reading future target inputs. Teacher forcing does not mean that future labels are visible through attention. At inference time the model conditions on its own previous choices instead.5
# Condensed from Harvard's Batch, MIT license.
source_mask = (source != pad_id).unsqueeze(-2)
target_input = target[:, :-1]
target_label = target[:, 1:]
target_mask = (target_input != pad_id).unsqueeze(-2)
target_mask = target_mask & subsequent_mask(target_input.size(-1)).to(target.device)
token_count = (target_label != pad_id).sum()
Padding masks block padded keys; loss handling separately excludes padded prediction targets. Padded query rows can still produce hidden states, which must not accidentally become supervised targets. Normalize the loss by actual targets, not the padded area of the batch.5
Forward pass and optimization
A training step prepares inputs and masks, runs the model and generator, computes token loss, normalizes it, backpropagates, updates parameters at the chosen optimizer boundary, advances the scheduler, and clears gradients. Evaluation disables parameter updates and training dropout. Architecture defines the differentiable function; the loop defines execution policy.5
The paper used Adam with , , and , and a warmup followed by inverse square root decay. These are historical recipe choices, not defaults recommended for every current model.3
Here is optimizer step and is warmup length. Before the schedule
rises linearly; at the branches meet; afterwards it decays as .
The tutorial exposes a multiplicative factor:5
# Adapted from Harvard's rate function, MIT license.
def rate(step, model_size, factor, warmup):
    step = max(step, 1)
    return factor * model_size ** (-0.5) * min(
        step ** (-0.5), step * warmup ** (-1.5)
    )
Label smoothing and loss interpretation
For a simplified vocabulary with no padding class, distribute target mass as:
The pinned tutorial reserves a padding class, distributes smoothing over alternative classes, sets padding probability to zero, and removes entire loss rows whose target is padding. It minimizes using model log probabilities as input.5
Smoothing discourages assigning all probability to the observed label, but does not universally improve every metric. The original paper reports improved accuracy and BLEU while perplexity worsened.3
A useful algebraic distinction: cross entropy equals . For a nondegenerate smoothed target, its minimum is positive . KL itself can reach zero when . Do not compare raw smoothed loss to ordinary hard target cross-entropy as if their baselines were the same.
The bridge to VLM supervised fine tuning
The same conditional next token objective applies when context includes an image and instruction, and is the target answer:
Here denotes the preceding answer tokens, and selects supervised positions with at least one selected target. This is local notation for token averaged conditional cross-entropy, with the conditional objective and ignore rules described by SFT and loss documentation. It is not a proprietary training recipe.137
An attention mask controls what a position can read. A loss mask controls which predictions contribute gradients. Prompt tokens can remain visible context while their prediction targets are ignored. Completion or assistant only loss depends on data format, chat template, and configuration. Inspect decoded examples and labels rather than relying on a setting’s name.13
With examples per device, accumulated microbatches, and data parallel workers, the nominal effective batch is . That count does not prove numerical equivalence to one physical batch.
For microbatch with summed token loss and supervised token count , the true combined token mean is:
It is not generally the mean of . For example, token means 1 and 3 over 10 and 30 tokens give a combined mean 2.5, not 2. Choose whether tokens or examples should receive equal weight, and make distributed reductions and gradient scaling implement that choice. This is a local derivation. Mixed precision scaling, clipping, and optimizer stepping must respect the effective batch boundary.14
Full fine tuning updates the selected model weights. LoRA freezes base weights and learns low rank updates to selected matrices. It reduces trainable parameters and their optimizer state, not the need to run the base model. Rank and target matrices are design choices; fewer trainable parameters do not automatically mean a smaller inference model.15
Evaluate a data or training change
This is a proposed experiment checklist, not a report of executed experiments:
- Define the hypothesis, downstream metric, and important workload slices.
- Separate training, development, and final test roles. Group pages and synthetic variants of one source document when a random split would leak shared information. Hold out templates or sources if that is the intended generalization test.
- Fix the starting checkpoint, evaluation protocol, and declared budget. Equal steps and equal tokens are different comparisons.
- For two changes, compare baseline, A, B, and A+B when feasible.
- Repeat training when feasible. Resampling evaluation documents does not measure training seed variability.
- If only A+B was tested, attribute the result to that combined intervention.
Greedy decoding and the cache
# Condensed from Harvard's greedy_decode, MIT license.
# Assumes one source example. No KV cache is implemented in this excerpt.
memory = model.encode(source, source_mask)
prefix = torch.tensor([[bos_id]], device=source.device)
for _ in range(max_length - 1):
    mask = subsequent_mask(prefix.size(1)).to(source.device)
    hidden = model.decode(memory, source_mask, prefix, mask)
    log_probs = model.generator(hidden[:, -1])
    next_token = log_probs.argmax(dim=-1)
    prefix = torch.cat([prefix, next_token[:, None]], dim=1)
    # Added stopping rule; the pinned tutorial runs to the length limit.
    if next_token.item() == eos_id:
        break
Use evaluation mode and disable gradient recording for generation. The tutorial’s simple loop recomputes the full prefix each step; source memory is computed once. The EOS break above is an explicit teaching addition.5
Incremental causal decoding can instead reuse each layer’s earlier K/V. The new query reads cached history plus its own new K/V. Earlier causal states do not change when a later token is appended, so reuse preserves the model’s causal computation, up to numerical differences. For encoder/decoder models, cross-attention K/V derived from fixed memory can also be reused.12
For layers, cached length , equal key/value head width , and bytes per element, a simple uncompressed self attention cache uses:
This is a local element-count derivation. It excludes allocation overhead, padding, sharding, quantization metadata, and any extra cross-attention cache. For unequal K/V widths, replace with .
Greedy decoding selects the most probable next token locally. Beam search retains candidate prefixes; temperature rescales logits; top-k truncates to a fixed number of candidates; nucleus sampling retains a probability mass. These are decoding policies, not different trained architectures. Their usefulness depends on the task; greedy choice does not guarantee the best whole sequence.1116
Computational cost
For a dense decoder with layers, batch , sequence length , width , and FFN width proportional to , a local matrix multiplication count gives:
Full sequence forward:
One cached decoding step at history length :
Projections and the FFN contribute the width squared term; and weight/value mixing contribute the sequence interaction term. This omits the vocabulary head, whose full sequence cost can be , and assumes ordinary dense attention rather than experts or restricted connectivity. A causal triangle changes constants, not quadratic growth. A full sequence forward is not the cost of repeatedly recomputing that prefix during generation.
The attention score tensor contains elements if materialized. Exact tiled kernels can avoid storing that full matrix while retaining quadratic arithmetic.17
From Transformer to modern LLMs
These choices can coexist. This is a comparison, not a ranking or a recipe that every model follows.
Figure 10. Coexisting design choices, not an inevitable timeline. Original comparison synthesized from the cited architecture and implementation sources.31819202191712
One causal stream instead of two
A decoder language model removes the separate source encoder and its cross-attention path. Prompt, context, and continuation occupy one causal sequence. Attention, FFN, residual width, normalization, position, and a vocabulary head remain recognizable. GPT-2 is a concrete example with learned position embeddings and pre-normalized blocks, not the full list of later choices in the diagram.18
LayerNorm and RMSNorm
LayerNorm centers a feature vector and rescales it using variance. RMSNorm rescales by root mean square without subtracting the mean. This removes a statistical operation while preserving rescaling invariance; it is not the same function as LayerNorm and is not universally better for every model.19
Additive position and RoPE
Sinusoidal position adds a vector to the input residual stream. RoPE instead rotates query and key feature pairs with position dependent angles, making their dot product depend on relative displacement. It changes compatibility geometry, not just a stored table. Reliable long context behavior still needs appropriate training and evaluation.20 Continue with Position and long context.
ReLU, GELU, and gated FFNs
The original FFN uses ReLU; GPT-2 uses GELU. A gated FFN introduces a second input projection and multiplies the branches before projecting back:
Biases are omitted in this notation. The gate is a learned multiplicative
feature interaction, not a probability constrained to [0,1]. SwiGLU uses
three projection matrices, so fair comparisons should account for parameter
and compute budgets, not simply reuse the same hidden width. Shazeer’s paper
reports gains in its controlled experiments, not a universal guarantee.21
Continue with FFNs and experts.
Different meanings of efficient attention
| Change | What changes | What not to infer |
|---|---|---|
| FlashAttention | IO schedule and score materialization | Full attention becomes linear arithmetic |
| MQA or GQA | Distinct KV projection heads and cache | Query head count must shrink |
| Sliding window | Allowed direct connections | Every token still directly reads all history |
| MLA | Joint compressed KV representation | It is just fewer ordinary KV heads |
FlashAttention preserves the dense attention operator up to numerical differences. Sliding window attention changes connectivity; Mistral describes how information can still travel across layers. DeepSeek-V2’s MLA introduces low rank KV compression. These mechanisms address different costs and should not be bundled into one unexplained claim of efficiency. The comparison table is a local synthesis of these mechanisms and the GQA design.1792223 Continue with Attention and memory.
Dense and routed experts
An MoE layer routes each token to selected FFN experts rather than activating all experts. Switch Transformer uses one expert per token with routing weights, capacity handling, and load balancing. The residual output still has width D. More total parameters do not imply that all parameters are active for every token, nor that device communication becomes free.24 Sparse expert activation is not the same as sparse attention.24
Information across depth
Attention and FFNs describe computation within a layer. Residual paths describe how representations reach later layers. Start with the original single-stream residual, then compare multiple streams, attention across earlier layers and gated reads and writes in Depth and residual paths. That companion page supplies the equations, source reports and their limits.
Read a model as a set of contracts
For any model report or implementation, record:
- Stack: encoder/decoder, prefix, or causal decoder?
- Normalization: which statistic, and where in the residual path?
- Position: additive, rotary, learned, or biased?
- Attention: full, local, latent, linear, or hybrid?
- Heads: query count, KV count, and head widths?
- FFN: activation, intermediate width, dense or routed?
- Context: trained length, served length, and any extension method?
- Runtime: cache, kernel, precision, and parallelism?
- Depth: one residual stream, multiple streams, or selective depth reads?
- Evidence: exact checkpoint, pinned code, and supporting ablations?
This is a local reading checklist. It helps separate the mathematical model from the strategy used to execute it. For VLMs, add how image features enter the model and how their positions and token budget are defined. Continue with Multimodal integration and Model Deep Dives.
Check your understanding
Shape and information checks
- Why can S differ from T? Cross-attention maps T queries over S keys/values.
- What does the decoder return? D-wide features, before the V-wide generator.
- Which axis does attention softmax normalize? Key positions, for each query.
- Does a causal mask make dense attention linear? No; the dense interaction matrix remains quadratic in length.
- Does deep-copying layers share parameters? No; reusing the same object would.
- Can ignored prompt labels remain visible context? Yes; loss and attention masks serve different purposes.13
- Does KV caching alter causal dependencies? No; it reuses earlier computation.12
- Does an MoE layer activate every expert? No; the router chooses a subset.24
Optional implementation checks
- Assert the source, memory, target, head, residual, and vocabulary shapes. Deliberately swap sequence axes and predict the first failing operation.
- Test self-attention, cross-attention with different lengths, padding, and causality. Changing hidden K/V positions should not change visible outputs when dropout is disabled.
- Verify that two cloned layers have distinct parameter storage. Check every residual addition for equal shapes.
- Print shifted inputs, labels, and one combined mask row. Compare cached and uncached generation logits within numerical tolerance.
- Fill the reading checklist for one model, cite each source section, and mark whether an efficiency choice changes arithmetic, traffic, cache, or active parameters.
These are learning exercises, not tests reported as completed on this page.
Sources and attribution
The primary implementation reference is Harvard NLP’s Annotated Transformer
at commit debc9fd.5 Read the
original tutorial
for its full runnable implementation and experiments. Adapted excerpts retain
Alexander Rush’s MIT license.6 Paper figures retain their own
reproduction terms, not Latent Light’s MIT grant. Numbered references connect
the explanations to their supporting sources.
References
-
Colin Raffel et al., Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer, JMLR 2020, arXiv version 4. A shared text input and text output formulation covers translation, summarization, question answering, classification, and other language tasks. ↩ ↩2
-
Ting Chen et al., Pix2seq: A Language Modeling Framework for Object Detection, ICLR 2022, arXiv version 2. Sections 2.1–2.2 describe serializing object labels and bounding box coordinates into tokens and generating them conditioned on an image. ↩ ↩2
-
Ashish Vaswani et al., Attention Is All You Need, NeurIPS 2017, arXiv version 7. Sections 3.1–3.5 define the architecture, attention, FFN, embeddings, and position; sections 5.3–5.4 describe optimization and smoothing. Figure 1 is reproduced under the source’s stated scholarly or journalistic reproduction permission. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11 ↩12 ↩13 ↩14 ↩15 ↩16 ↩17 ↩18 ↩19 ↩20 ↩21 ↩22 ↩23 ↩24 ↩25 ↩26 ↩27 ↩28
-
Jared Kaplan et al., Scaling Laws for Neural Language Models, 2020, arXiv version 1. The authors report empirical relationships between language modeling loss, model size, dataset size, and training compute within the studied ranges. These findings do not guarantee improvement on every downstream task. ↩
-
Harvard NLP, The Annotated Transformer, commit
debc9fd747bb2123160a98046ad1c2d4da44a567. Inspected interfaces include EncoderDecoder and Generator (lines 230–269), residuals and stacks (292–438), attention and heads (441–628), FFN and position (677–786), make_model (822–848), Batch and training (907–1024), LabelSmoothing (1148–1176), and greedy_decode (1313–1328). Teaching changes are marked beside the excerpts. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11 ↩12 ↩13 ↩14 ↩15 ↩16 ↩17 ↩18 ↩19 ↩20 ↩21 ↩22 ↩23 ↩24 ↩25 ↩26 ↩27 ↩28 -
Alexander Rush, Annotated Transformer MIT license, copyright 2018, same pinned commit. The complete notice is retained with the adapted excerpts. ↩ ↩2
-
PyTorch, CrossEntropyLoss, version 2.14. Logit inputs, LogSoftmax equivalence, ignored labels, and loss reduction. ↩ ↩2
-
PyTorch, Scaled dot product attention, version 2.14. Mask polarity, causal handling, backend selection, GQA, and numerical differences between kernels. ↩ ↩2 ↩3
-
Joshua Ainslie et al., GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints, EMNLP 2023. Section 2 describes KV sharing and uptraining; Figure 2 compares MHA, GQA, and MQA. The inspected arXiv HTML version 3 provides the same mechanism. Figure 2 is reproduced unchanged under CC BY 4.0. ↩ ↩2 ↩3 ↩4 ↩5
-
Ruibin Xiong et al., On Layer Normalization in the Transformer Architecture, ICML 2020. Analysis of normalization placement and gradient behavior. ↩
-
Hugging Face, Transformers GenerationConfig, main documentation inspected October 3, 2026. Greedy decoding, beams, temperature, top-k, and top-p parameters. ↩ ↩2
-
Hugging Face, Transformers cache strategies, main documentation inspected October 3, 2026. KV reuse and the encoder/decoder cache section. Main documentation can change; check the installed version when implementing. ↩ ↩2 ↩3 ↩4
-
Hugging Face, TRL SFT Trainer: completion and assistant message loss, inspected October 3, 2026. Configuration and templates determine which tokens are supervised; behavior must be checked against the installed version. ↩ ↩2 ↩3
-
PyTorch, Automatic mixed precision examples: gradient accumulation, version 2.14. Scaling, clipping, and optimizer boundaries for an effective batch. ↩
-
Edward J. Hu et al., LoRA: Low-Rank Adaptation of Large Language Models, 2021, ICLR 2022. Frozen base weights and trainable low rank adaptation matrices. ↩
-
Ari Holtzman et al., The Curious Case of Neural Text Degeneration, ICLR 2020. Nucleus sampling and comparison with other decoding policies. ↩
-
Tri Dao et al., FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness, NeurIPS 2022, arXiv version 2. Sections 2–3 distinguish attention arithmetic from memory traffic and materialization. ↩ ↩2 ↩3
-
Alec Radford et al., OpenAI, Language Models are Unsupervised Multitask Learners, 2019, section 2.3. GPT-2 architecture and normalization changes. ↩ ↩2
-
Biao Zhang and Rico Sennrich, Root Mean Square Layer Normalization, NeurIPS 2019. Rescaling without mean centering. ↩ ↩2
-
Jianlin Su et al., RoFormer: Enhanced Transformer with Rotary Position Embedding, 2021, arXiv version 5, section 3. Position dependent rotations and relative displacement in query/key dot products. ↩ ↩2
-
Noam Shazeer, GLU Variants Improve Transformer, 2020, arXiv version 1. Gated FFN definitions and controlled comparisons. ↩ ↩2
-
Albert Q. Jiang et al., Mistral 7B, 2023, arXiv version 1, section 2. Sliding window connectivity and information propagation across layers. ↩
-
DeepSeek-AI, DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model, 2024, arXiv version 5, section 2.1. Multi-head latent attention and joint KV compression. ↩
-
William Fedus, Barret Zoph, and Noam Shazeer, Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity, JMLR 2022, arXiv version 3, sections 2–3. Expert routing, capacity, and balancing. ↩ ↩2 ↩3